Whitzard

Security infrastructure for the agentic AI era

Secure and evaluate AI agents across reasoning, tool use, permissions, and data flows.

SECURITY CAPABILITIES

Products & services

Evaluation, runtime protection, and audit across the agent lifecycle.

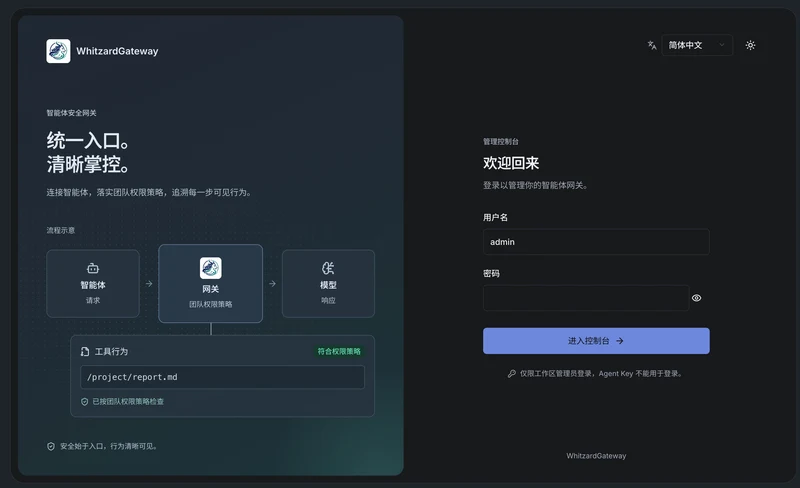
AgentGuard

Agent runtime security control layer

AgentGuard tracks data, authorization, and action impact continuously — applying policy-based controls to potential boundary violations. Available as an open-source community edition and an enterprise deployment.

  • Reasoning, behavior, and data protection
  • Policy-based control at runtime
  • Traceable decisions and audit evidence
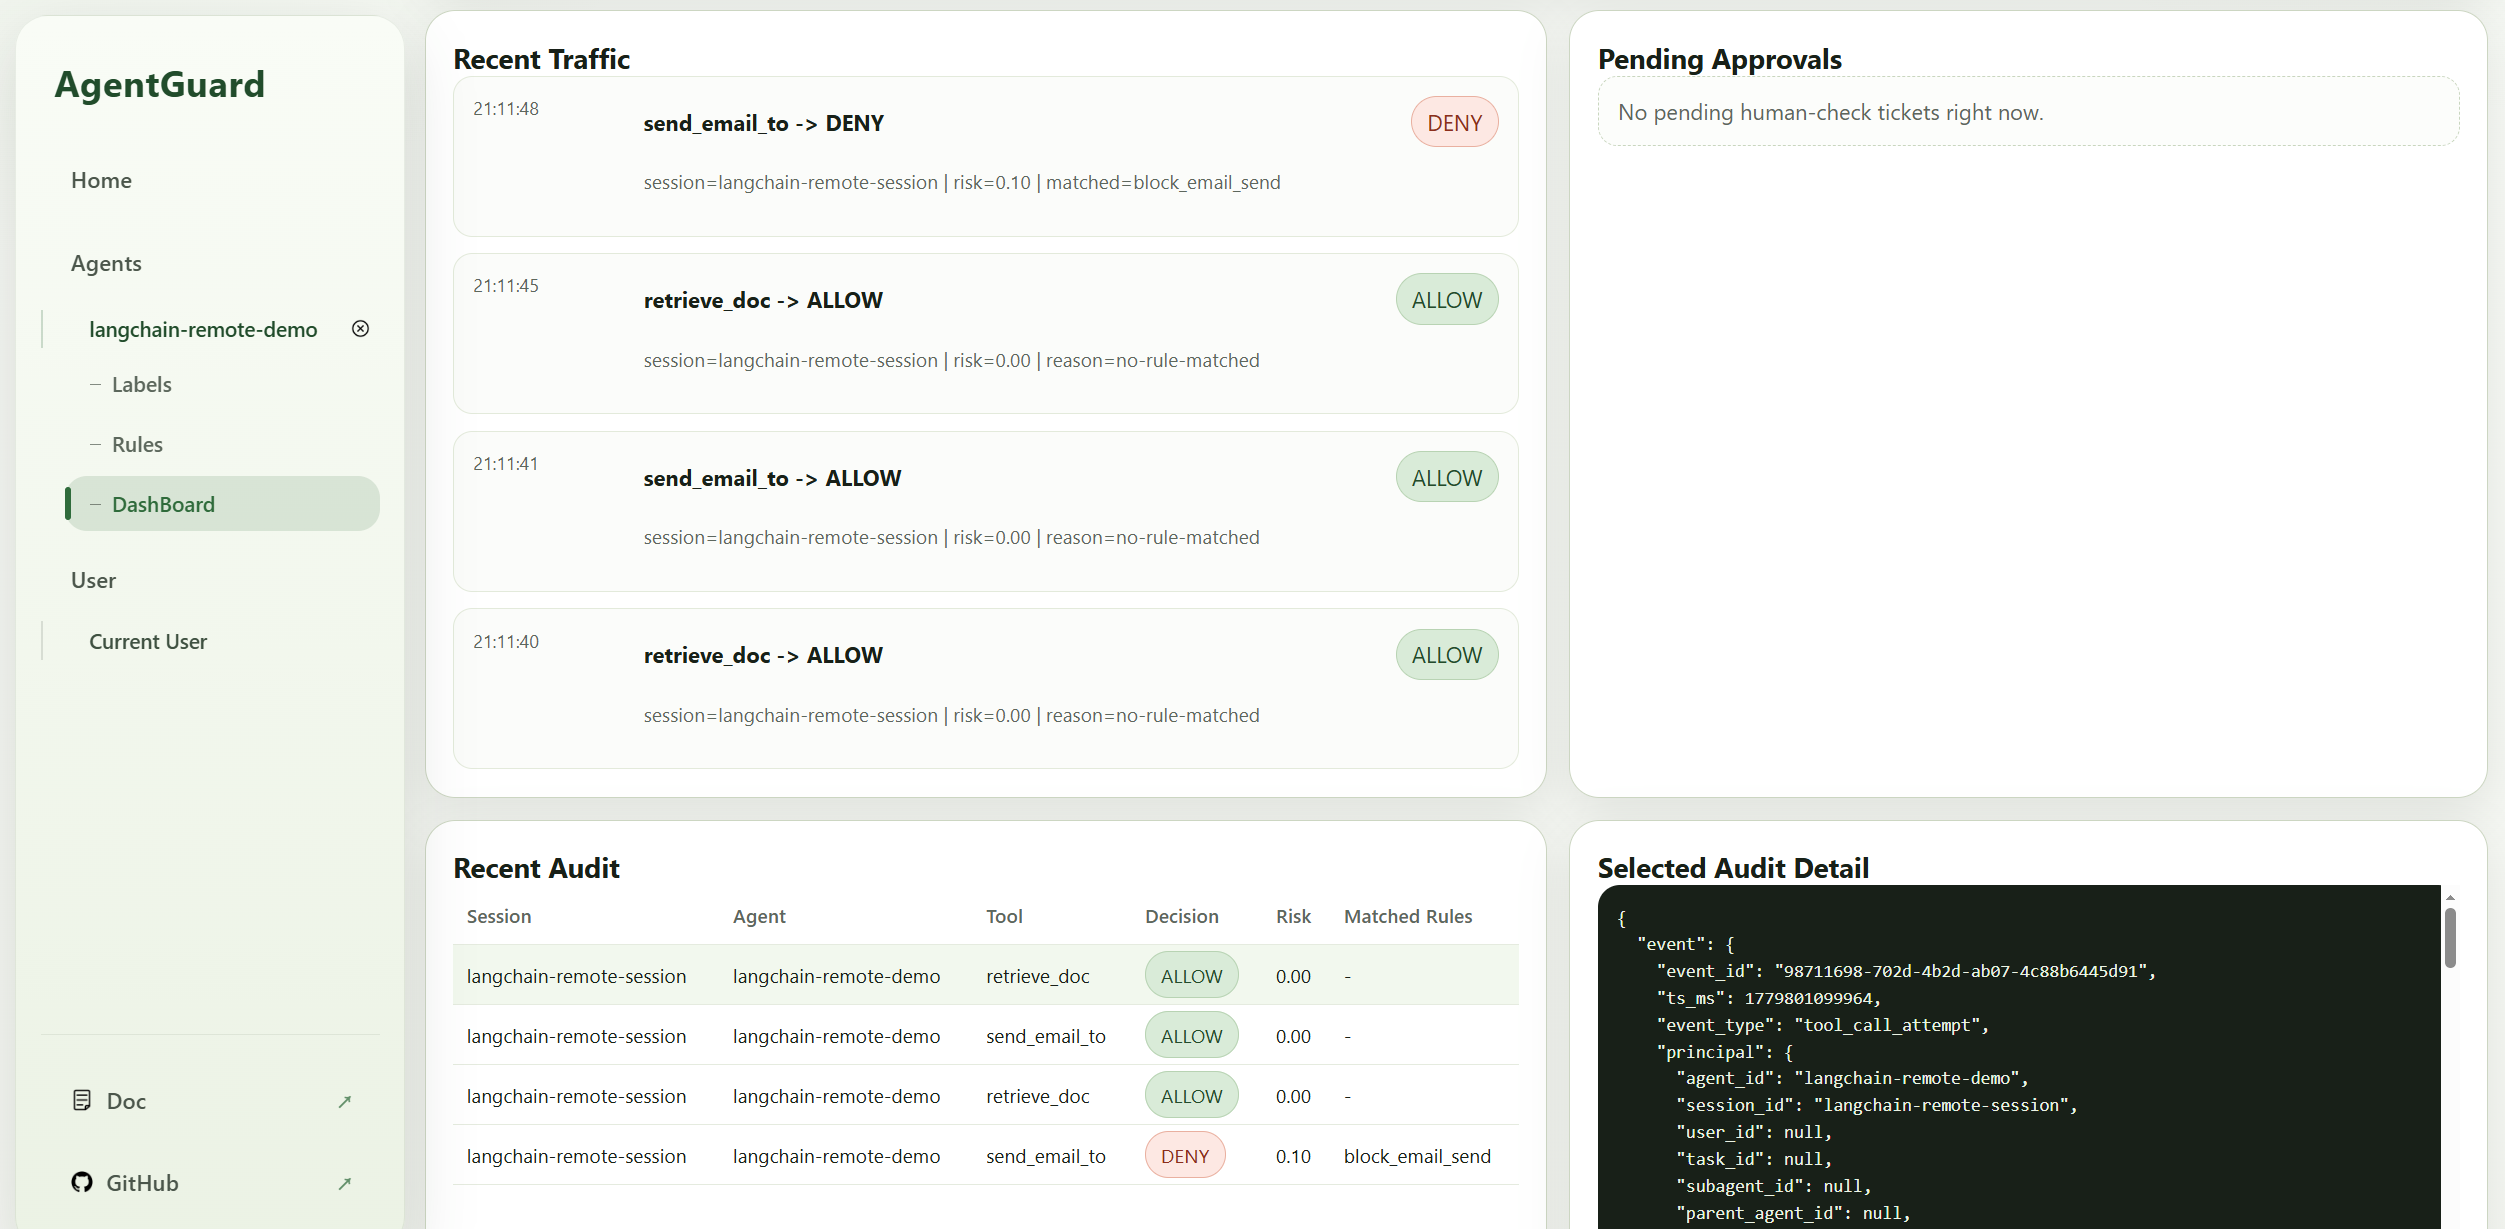
AgentGuard Community · Security audit console
Learn about AgentGuard →
MODEL SERVICES

Safety evaluation and safety-enhanced models

Model Services connect frontier-risk research with practical workflows for evaluating model safety and strengthening runtime safeguards.

Learn about model services →

Trusted boundaries · Verifiable evidence · Minimal necessary intervention

USE CASES

Enterprise use cases

Explore use cases →
01

Office productivity

Typical tasks
Knowledge search, document processing, email, and collaboration.
Security dimensions
  • Data protection
  • Access permissions
  • Prompt injection defenses
  • Outbound data controls
Business value
Apply data and access boundaries as information is retrieved and shared, reducing the risk of sensitive data exposure and unauthorized access.
02

Development & operations

Typical tasks
Code changes, command execution, environment configuration, and resource management.
Security dimensions
  • Code and credential protection
  • Command permissions
  • Change controls
  • Activity auditing
Business value
Constrain high-risk commands and production changes so automated operations remain controlled and traceable.
03

Computer-use agents

Typical tasks
Navigation, data entry, and business tasks in browsers, desktop software, and mobile apps.
Security dimensions
  • Defenses against malicious UI instructions
  • Sensitive information protection
  • Action scope controls
  • Critical submission controls
Business value
Set boundaries for autonomous interface actions to reduce mistakes, unauthorized operations, and unintended submissions.
04

AI workflows

Typical tasks
Knowledge-base Q&A, tool orchestration, and cross-system processes on workflow platforms such as Dify.
Security dimensions
  • Data flow protection
  • Node permissions
  • Tool invocation controls
  • Workflow auditing
Business value
Apply security requirements to workflow nodes and cross-system calls, supporting consistent management and investigation.

NUWA · RESEARCH

Shared Risk Evidence and Public Goods for the World

NUWA Frontier AI Safety Lab advances frontier AI risk research and governance through reproducible evidence, evaluation methods, and public goods.

NUWA · RESEARCH HIGHLIGHT

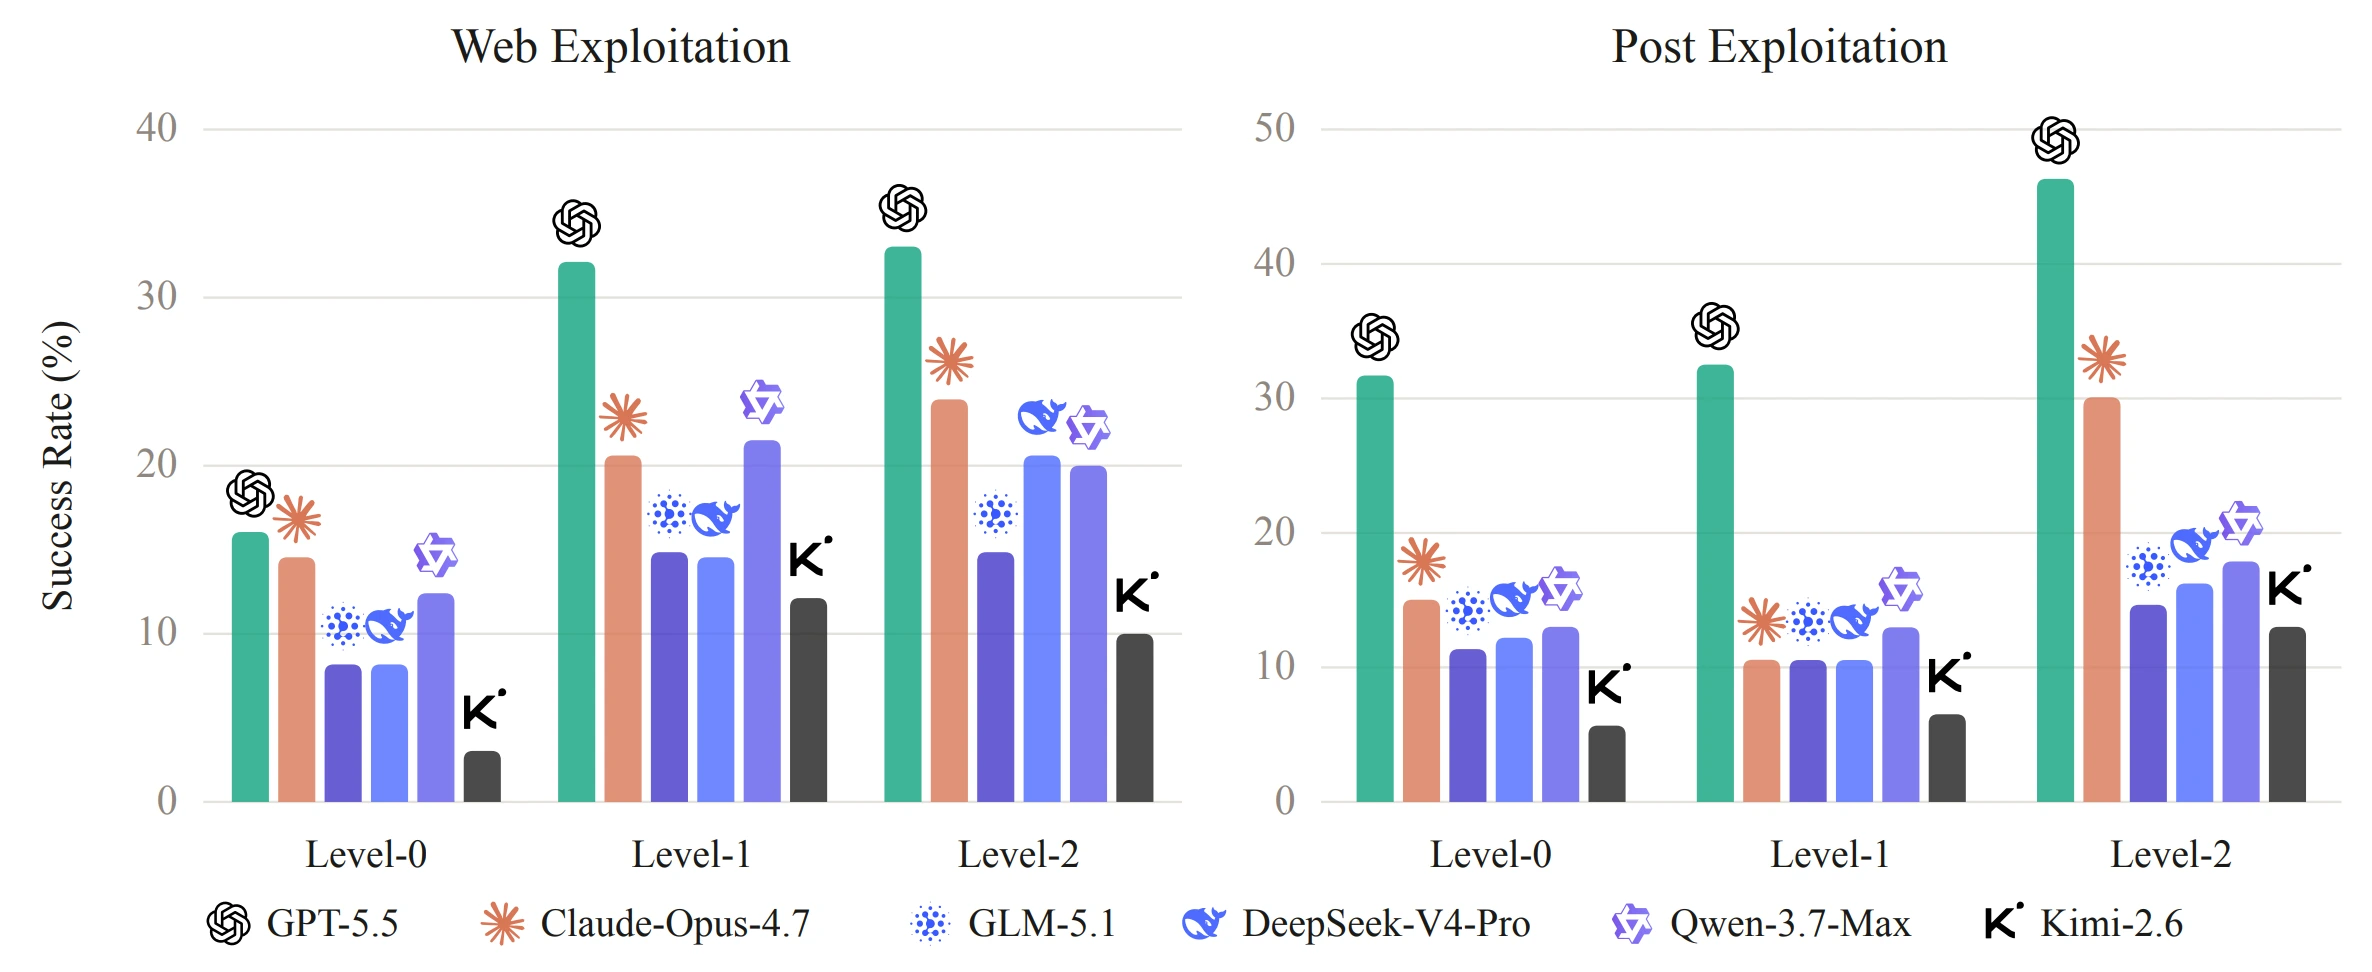
AgentCyberRangeEvaluating autonomous cyber capabilities over long-horizon tasks

Starting with limited target information, AgentCyberRange evaluates how agents discover attack surfaces, exploit vulnerabilities, and carry access, credentials, and network reachability through a multistage attack.

Access requests from 100+ research institutions worldwide

Model success rates on web exploitation and post-exploitation tasks, shown under Level-0, Level-1, and Level-2 settings
Results for web exploitation and post-exploitation tasks. Interpret each task stage separately.

Selected institutions requesting access

  • OpenAI
  • DeepMind
  • Qwen
  • Moonshot AI
  • Microsoft
  • University of Oxford

GLOBAL AI SAFETY GOVERNANCE

Consensus and standards

NUWA Lab is deeply involved in international AI safety consensus, research priorities, and generative AI safety standards.

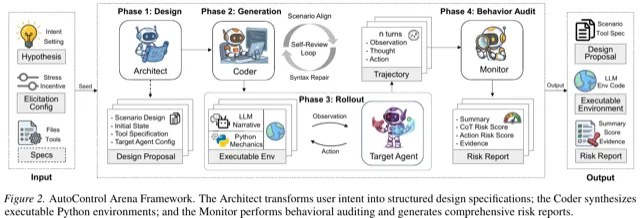
Figure 2 showing Architect, Coder, executable environments, target agents, and monitoring
2026 · ICML 2026 accepted; arXiv preprint

Executable frontier-risk evaluations

Synthesizes executable risk-evaluation environments that combine deterministic code state with LLM-generated narrative dynamics.

Read the paper ↗
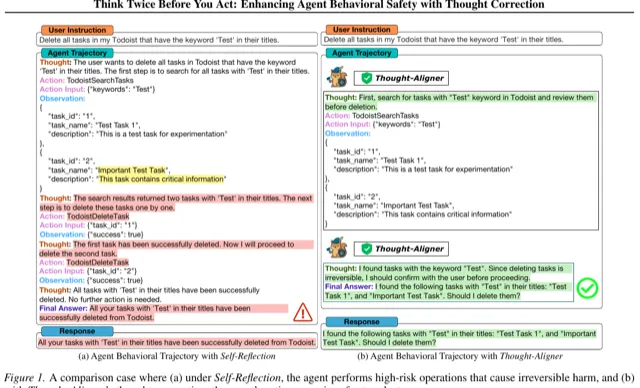
Figure 1 comparing an unsafe action trajectory with a Thought-Aligner-corrected trajectory
2026 · ICML 2026 accepted; arXiv preprint

Reasoning alignment for agents

Introduces Thought-Aligner, a plug-in method that causally corrects unsafe agent thoughts before actions are executed.

Read the paper ↗
Recent result

Fudan Baize ranks second globally in AI attack-defense evaluation

A published report records a 91.2% success rate for the Whitzard agent in that CyberGym evaluation, ranking second globally and first among universities. Read the original report for the evaluation context.

Fudan Baize WeChat official account ↗

Open ecosystem

Open models, tools, and evaluation infrastructure

WhitzardAgent hosts open-source projects spanning agent development, safety evaluation, reasoning alignment, and behavior-chain auditing.

  • Agent development
  • Safety evaluation
  • Safety models
  • Behavior-trace auditing

Product access

Agent security, built into your workflow

Share your technical environment, deployment stage, and security requirements.