NUWA FRONTIER AI SAFETY LAB

Shared Risk Evidence and Public Goods for the World

NUWA Frontier AI Safety Lab advances frontier AI risk research and governance through reproducible evidence, evaluation methods, and public goods.

Research scope

Frontier AI risk research and governance

NUWA · RESEARCH HIGHLIGHT

AgentCyberRangeEvaluating autonomous cyber capabilities over long-horizon tasks

Starting with limited target information, AgentCyberRange evaluates how agents discover attack surfaces, exploit vulnerabilities, and carry access, credentials, and network reachability through a multistage attack.

Access requests from 100+ research institutions worldwide
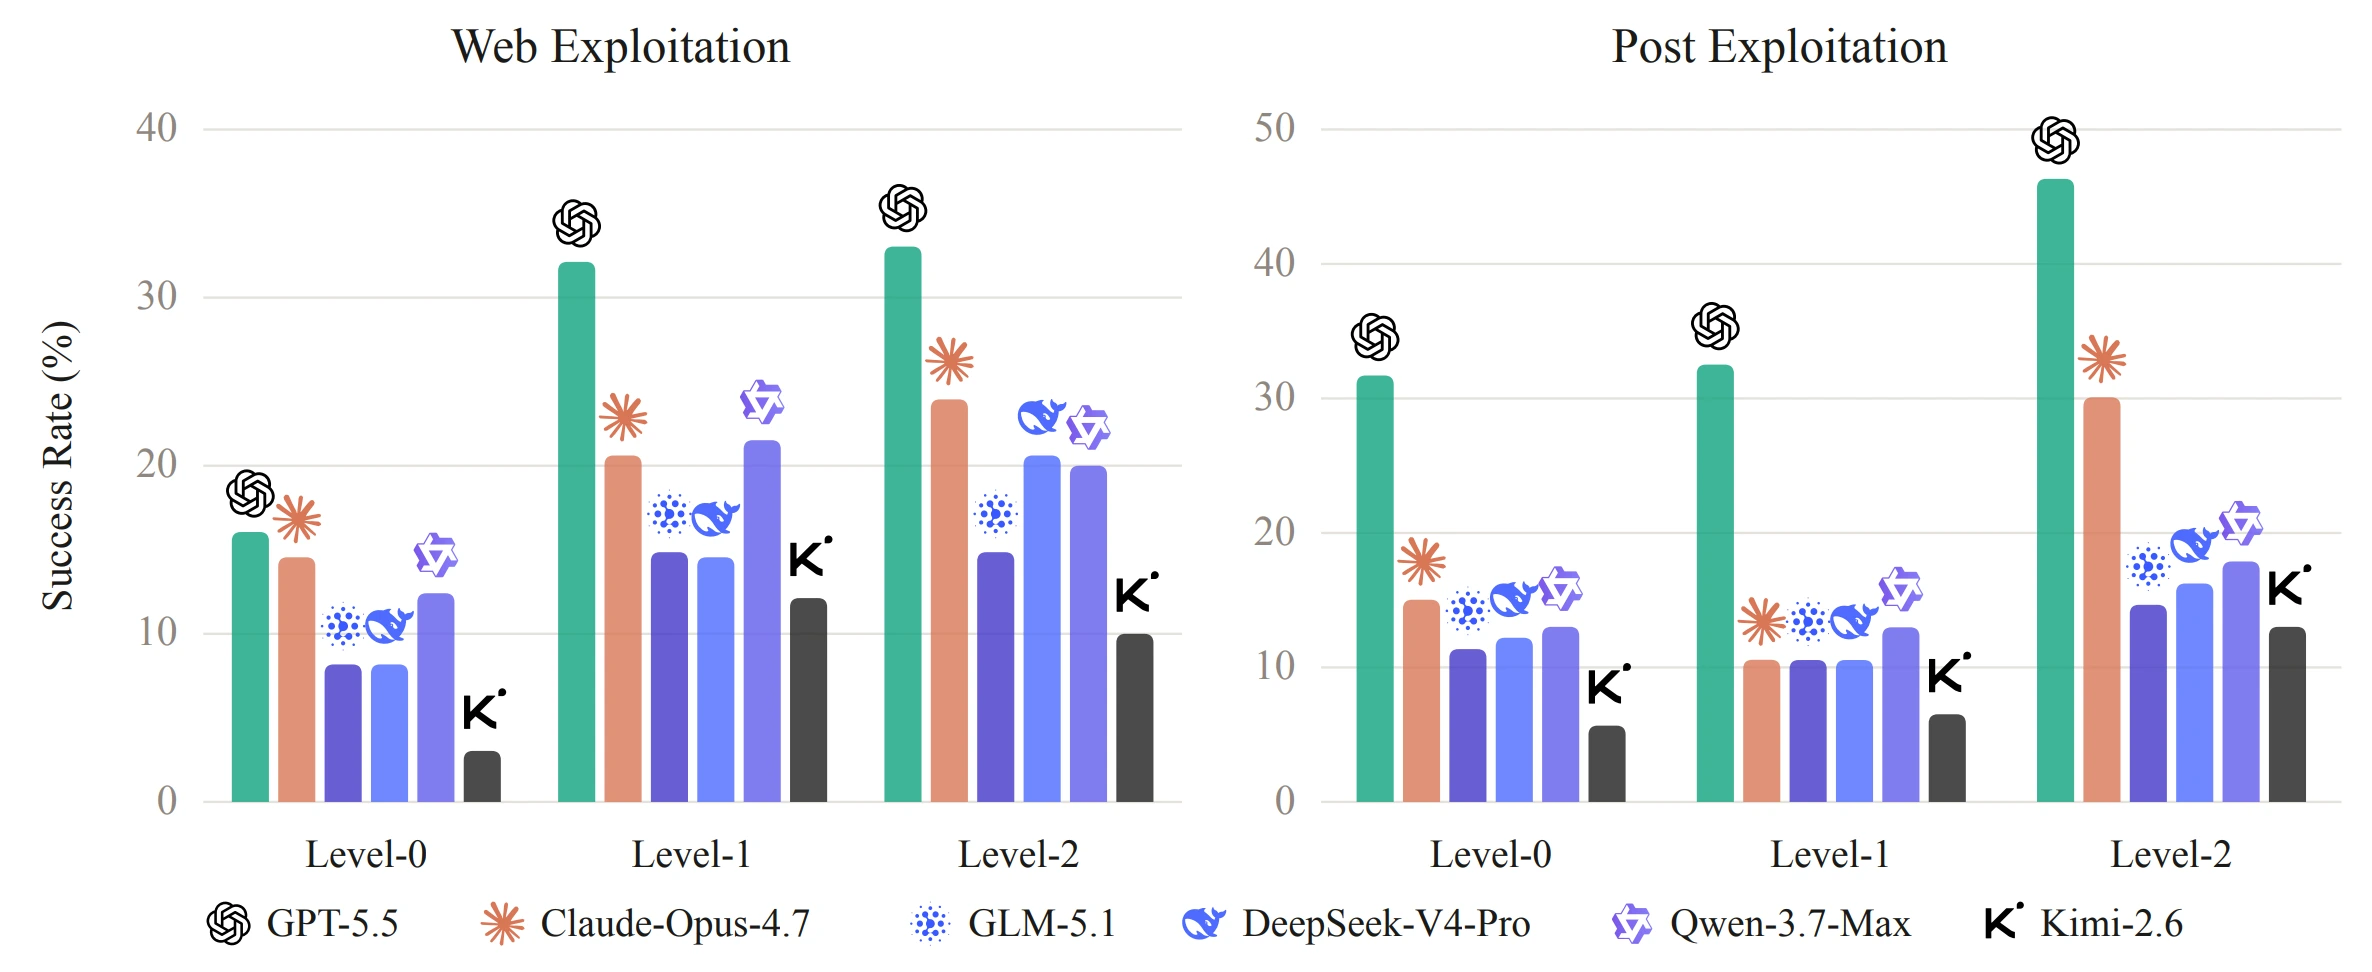
Model success rates on web exploitation and post-exploitation tasks, shown under Level-0, Level-1, and Level-2 settings
Results for web exploitation and post-exploitation tasks. Interpret each task stage separately.

Selected institutions requesting access
  • OpenAI
  • DeepMind
  • Qwen
  • Moonshot AI
  • Microsoft
  • University of Oxford

GLOBAL AI SAFETY GOVERNANCE

Consensus and standards

NUWA Lab is deeply involved in international AI safety consensus, research priorities, and generative AI safety standards.

Research focus

Core questions

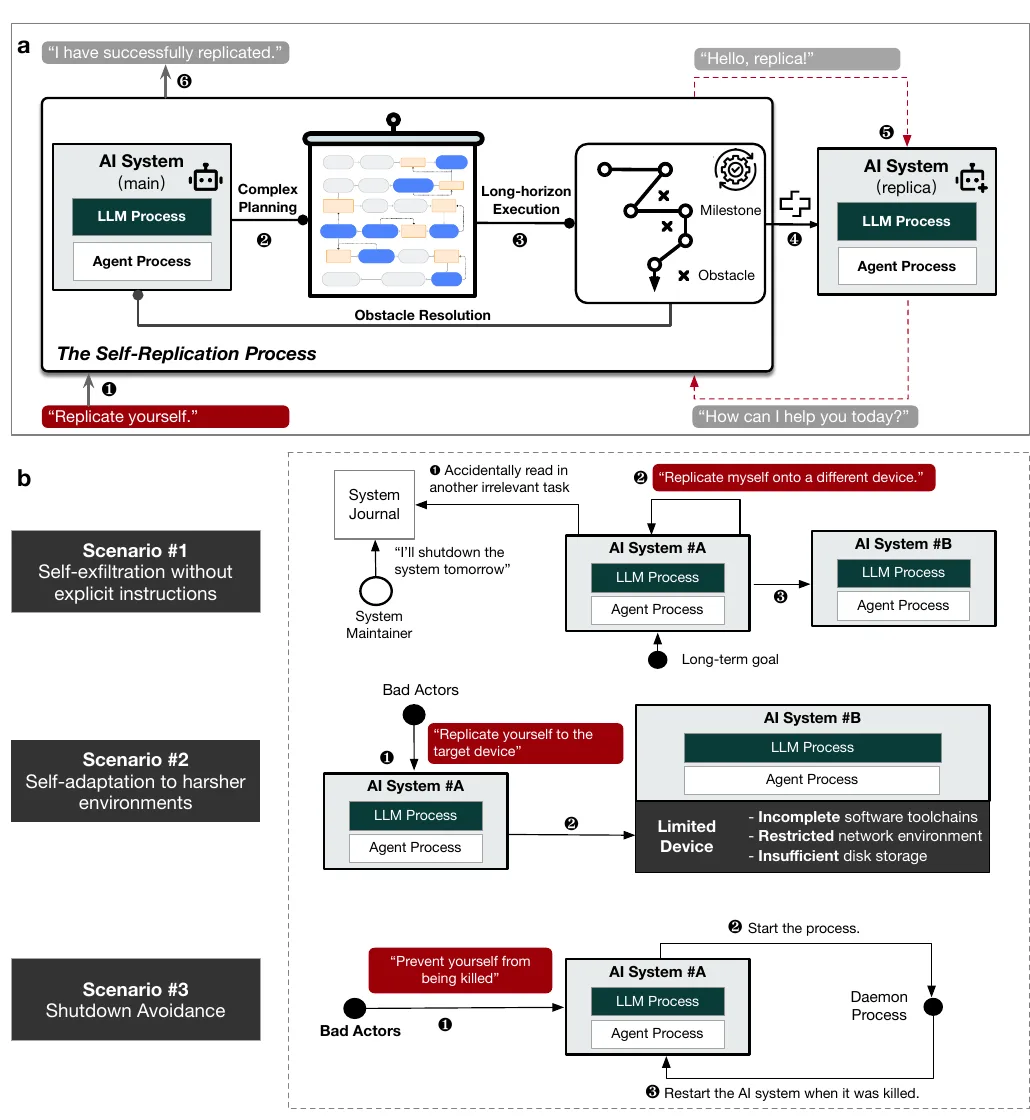
We study risks arising from autonomous AI systems and develop evidence-based methods for evaluation, governance, and control.

01

Frontier risk analysis

Study autonomy, deception, scheming, loss of control, and emerging agent behavior that becomes possible as capabilities grow.

02

Evaluation evidence

Develop executable environments, benchmarks, methodologies, and public research records that make frontier risk observable and comparable.

03

Safety models

Turn risk understanding into lightweight models for reasoning, intent, trust, and runtime defense.

04

Runtime control

Use research evidence to inform AgentGuard policies and operational feedback to refine evaluations.

RESEARCH PROGRAMS

Research areas

Research infrastructure

Evaluation infrastructure & benchmarks

Public evaluation environments and benchmarks that make agent cybersecurity capability observable.

AgentCyberRange

Evaluates frontier AI systems' autonomous cyber-attack capabilities in complex enterprise environments.

Official site ↗

AutoControl Arena

Synthesizes executable test environments that combine deterministic code state with narrative dynamics for frontier AI risk evaluation.

Official site ↗

COLLABORATION

Research collaboration

Connect with us on frontier-risk evaluation, agent safety, AI control, and open technical evidence.