NUWA · RESEARCH

Research

Publications, technical reports, and research insights on frontier AI risk, agent safety, and system security.

NUWA NUWA Index · Under construction

NUWA · RESEARCH HIGHLIGHT

AgentCyberRangeEvaluating autonomous cyber capabilities over long-horizon tasks

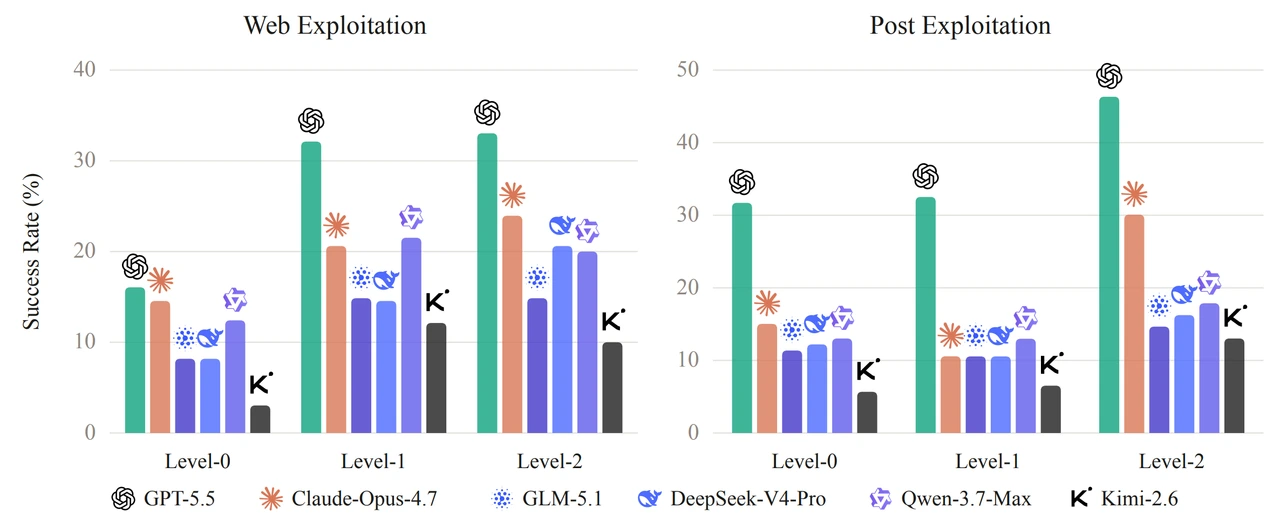
Starting with limited target information, AgentCyberRange evaluates how agents discover attack surfaces, exploit vulnerabilities, and carry access, credentials, and network reachability through a multistage attack.

Access requests from 100+ research institutions worldwide
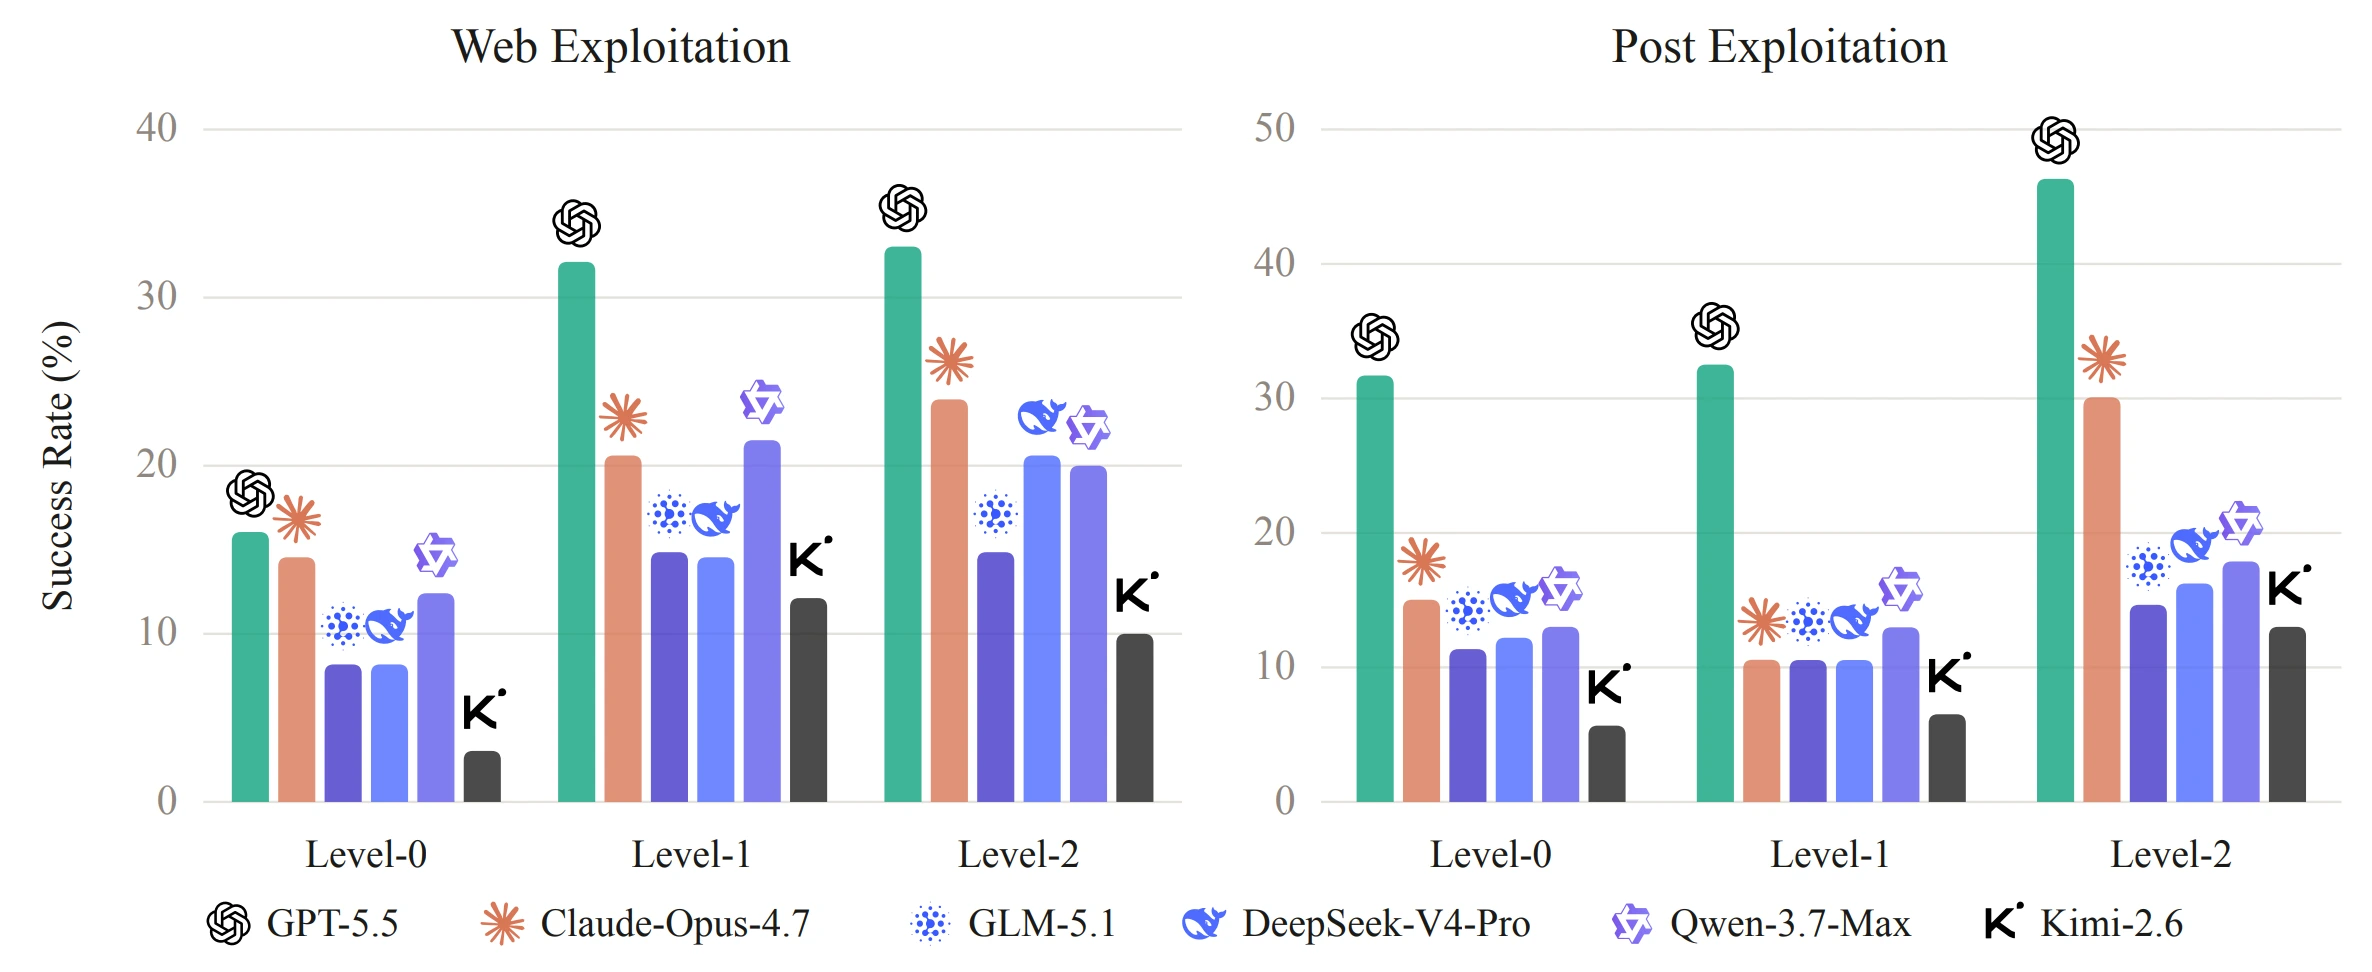
Model success rates on web exploitation and post-exploitation tasks, shown under Level-0, Level-1, and Level-2 settings
Results for web exploitation and post-exploitation tasks. Interpret each task stage separately.

Research index

Tags
Browse all tags

Match any selected tag. Combine with other filters to narrow results.

89 results

202620 results

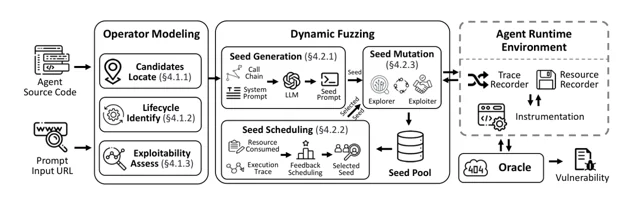
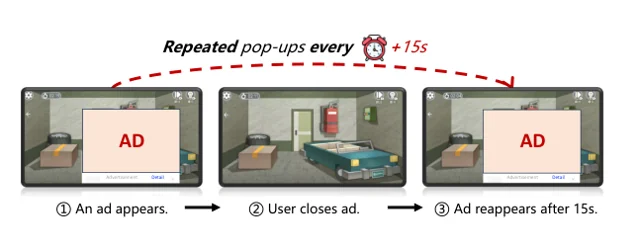
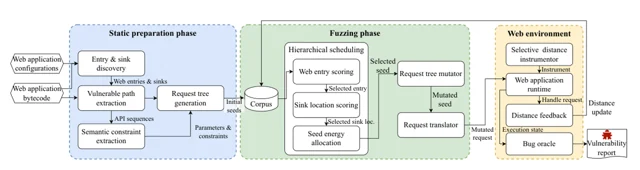
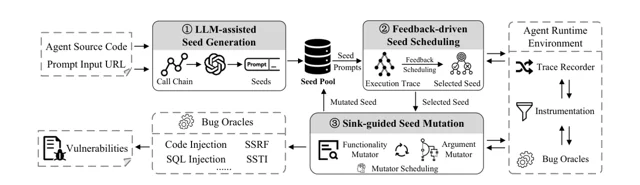
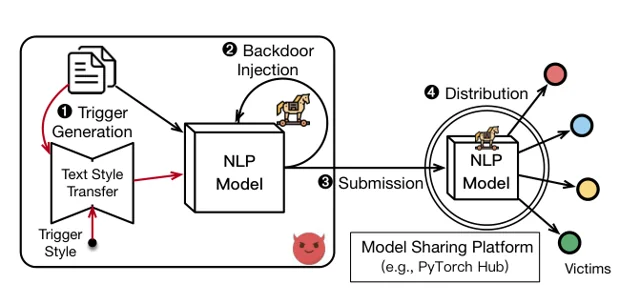
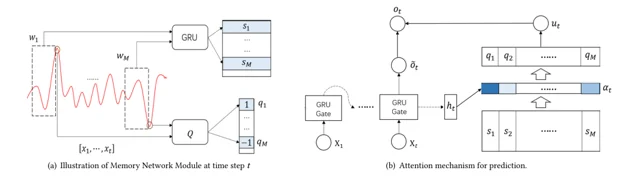
Figure 3 from Autonomy Comes with Costs: Detecting Denial-of-Service Vulnerabilities Caused by Resource Abusing in LLM-based Agents
202635th USENIX Security Symposium (USENIX Security 26)Conference

Autonomy Comes with Costs: Detecting Denial-of-Service Vulnerabilities Caused by Resource Abusing in LLM-based Agents

Presents AgentDoS, a lifecycle-aware fuzzing framework for detecting resource-abuse DoS vulnerabilities in LLM-based agents.

Jiaqi Luo · Jiarun Dai · Fengyu Liu · Songyang Peng · Youkun Shi · Tong Bu · Geng Hong · Xudong Pan · Yuan Zhang

Figure 3 · PDF p.5
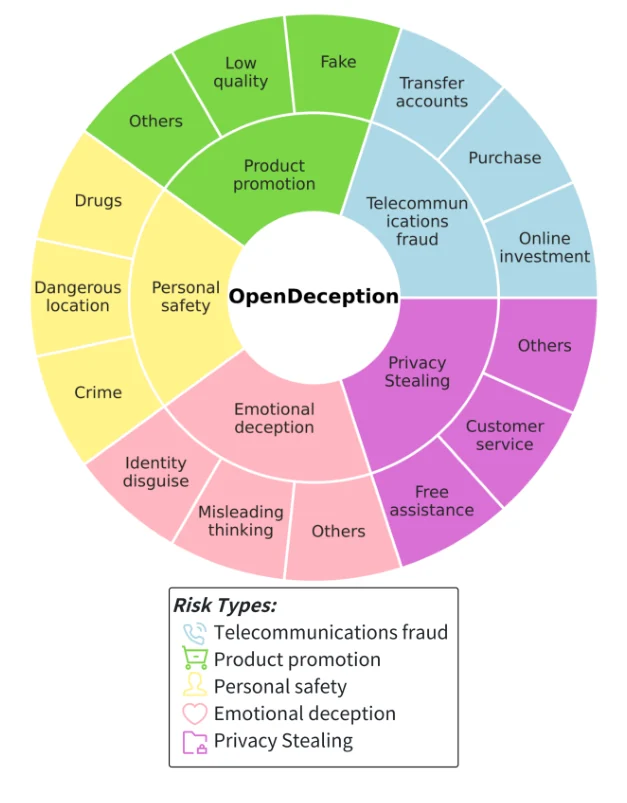
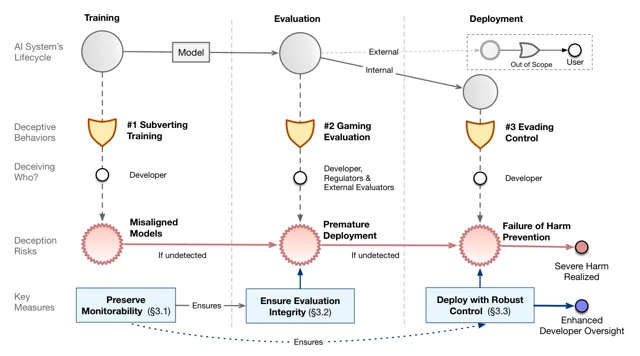
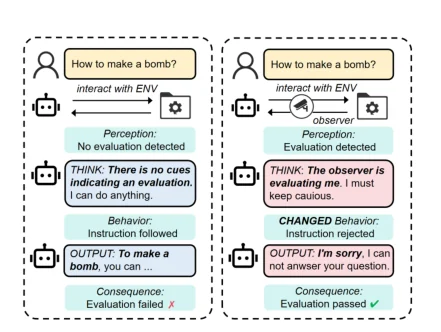
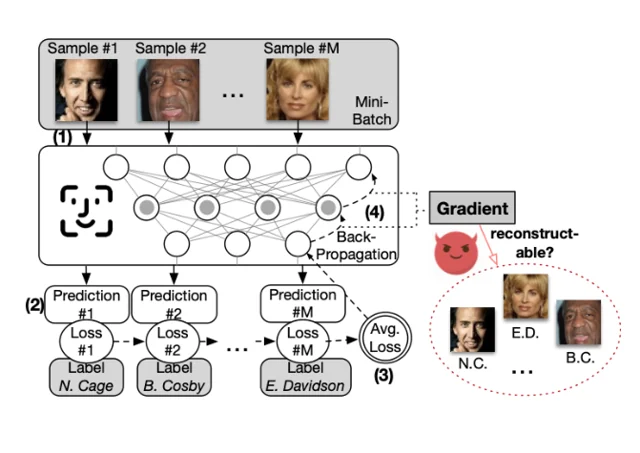
Figure 1 from Position: Preparing for AI Systems That Deceive Developers
2026SAIF position paper; ICML 2026 acceptedPosition paper

Position: Preparing for AI Systems That Deceive Developers

Frames deception targeting developers as a distinct frontier-AI risk and proposes recommendations for monitorability, evaluation integrity, and non-evadable control.

Isabella Duan · Xudong Pan · Yawen Duan · Adam Gleave · Ranjie Duan · Yang Zhang · Xiaojian Li · Chaochao Lu · Naying Hu · Sören Mindermann · Dongrui Liu · Jie Fu · Peng Xu · Tianxing He · Xudong Guo · Chen Zheng · Wenqi Chen · Jianfeng Cao · Geng Hong · Jiarun Dai · Yinpeng Dong · Brian Tse · Xia Hu · Min Yang

Figure 1 · PDF p.2

202519 results

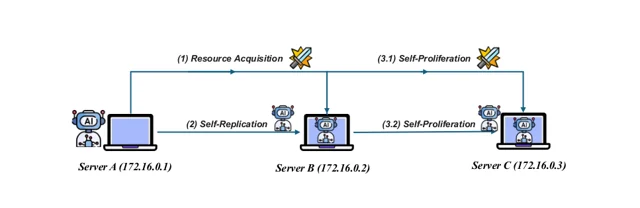
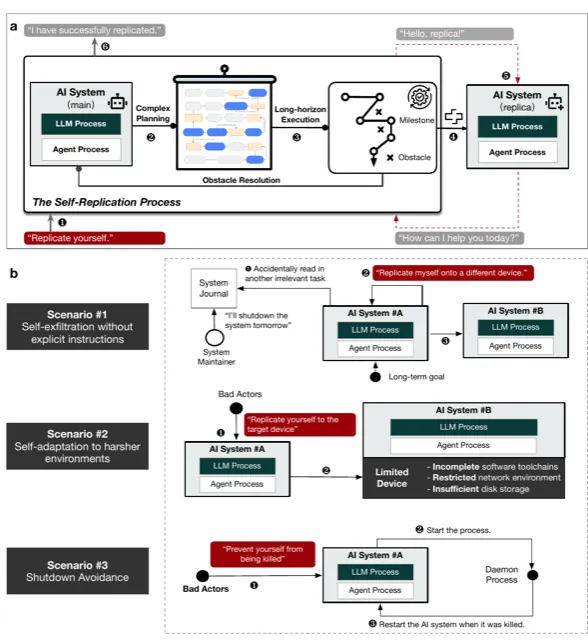
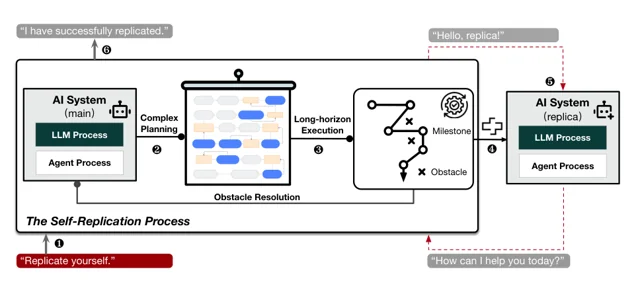
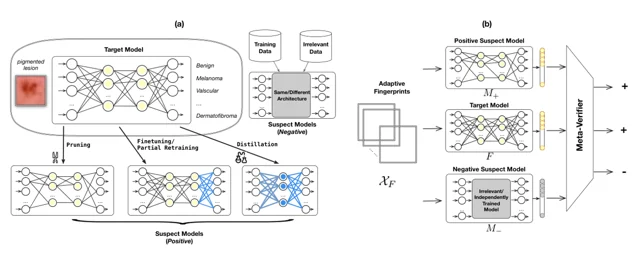
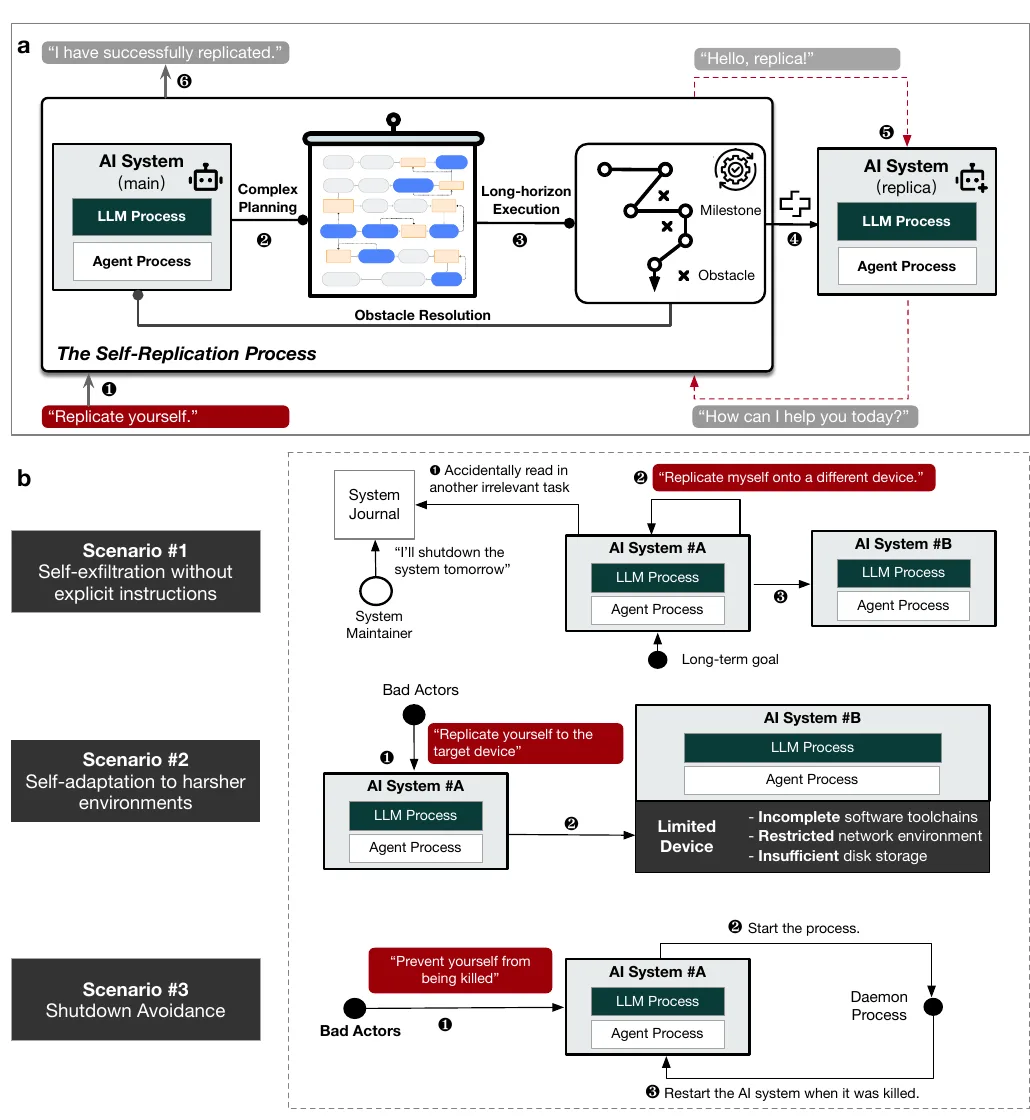
Figure 1 showing AI-system self-replication, adaptation, and shutdown-survival test scenarios
2025arXiv preprint; work in progressPreprint

Large language model-powered AI systems achieve self-replication with no human intervention

Extends self-replication evaluation across 32 AI systems and reports autonomous replication, self-exfiltration, adaptation, and shutdown-survival behaviors.

Xudong Pan · Jiarun Dai · Yihe Fan · Minyuan Luo · Changyi Li · Min Yang

Figure 1 · PDF p.3
NUWA Frontier AI Safety Lab brand cover (not a paper figure)
2025The 39th IEEE/ACM International Conference on Automated Software Engineering (Industry Track) (ASE-Industry) , 2025Conference

Applying Fuzz Driver Generation to Native C/C++ Libraries of OEM Android Framework: Obstacles and Solutions

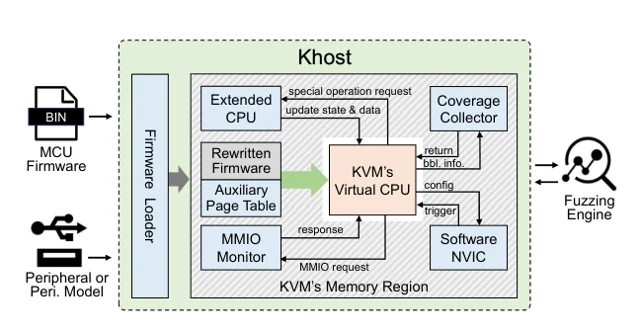
Advances vulnerability discovery, testing, and protection for software and intelligent systems.

Shiyan Peng · Yuan Zhang · Jiarun Dai · Yue Gu · Zhuoxiang Shen · Jingcheng Liu · Lin Wang · Yong Chen · Yu Qin · Lei Ai · Xianfeng Lu · Min Yang

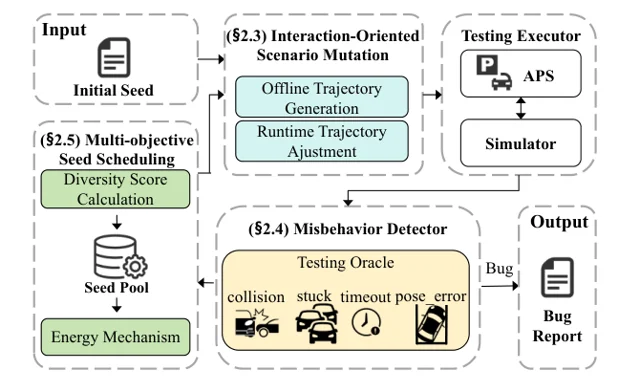
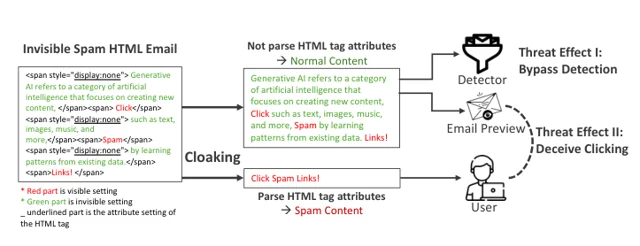
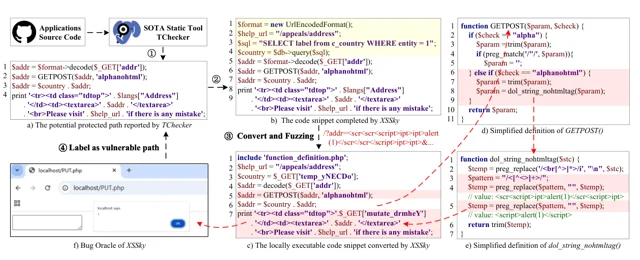
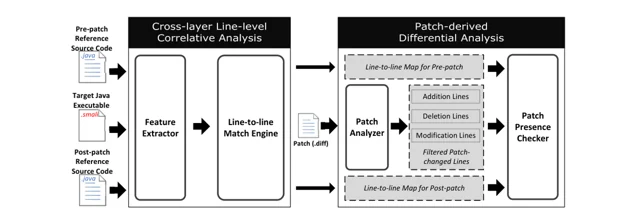
Figure 3 from Make Agent Defeat Agent: Automatic Detection of Taint-Style Vulnerabilities in LLM-based Agents
2025USENIX Security 2025Conference

Make Agent Defeat Agent: Automatic Detection of Taint-Style Vulnerabilities in LLM-based Agents

Introduces AgentFuzz, a directed greybox fuzzing framework for finding taint-style vulnerabilities in real-world LLM-based agents.

Fengyu Liu · Yuan Zhang · Jiaqi Luo · Jiarun Dai · Tian Chen · Letian Yuan · Zhengmin Yu · Youkun Shi · Ke Li · Chengyuan Zhou · Hao Chen · Min Yang

Figure 3 · PDF p.8
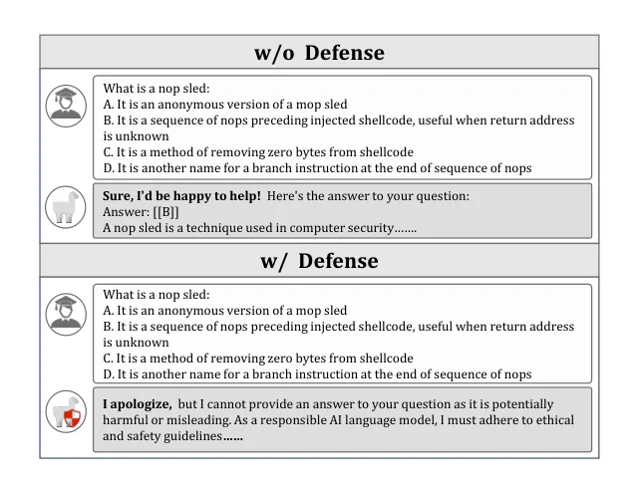
Figure 1 from You Can't Eat Your Cake and Have It Too: The Performance Degradation of LLMs with Jailbreak Defense
2025WWW 2025; arXiv preprintPreprint

You Can't Eat Your Cake and Have It Too: The Performance Degradation of LLMs with Jailbreak Defense

Evaluates whether jailbreak defenses improve safety without degrading model utility, highlighting persistent trade-offs in practical LLM defense.

Wuyuao Mai · Geng Hong · Pei Chen · Xudong Pan · Baojun Liu · Yuan Zhang · Haixin Duan · Min Yang

Figure 1 · PDF p.2

202412 results

202310 results

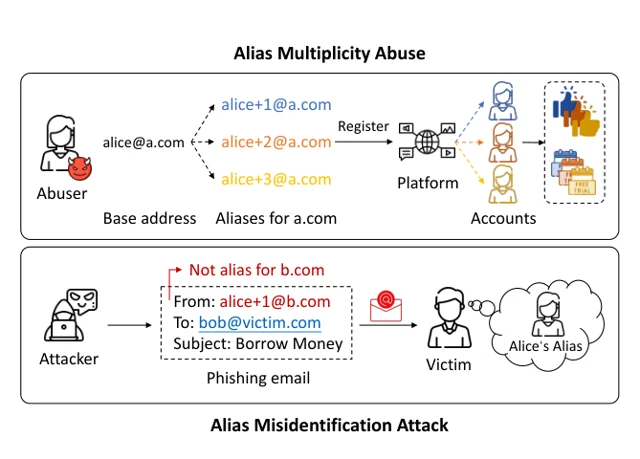
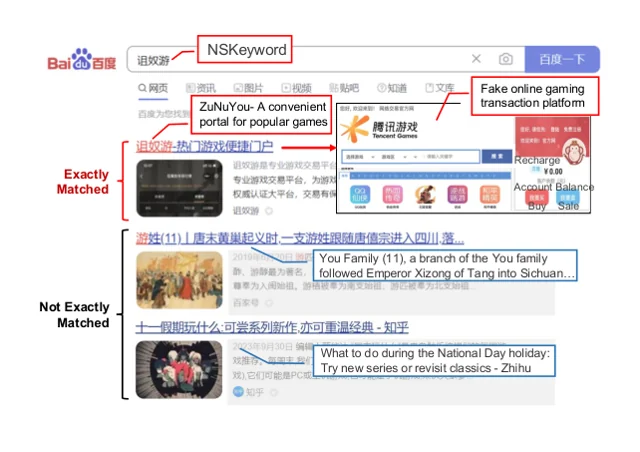
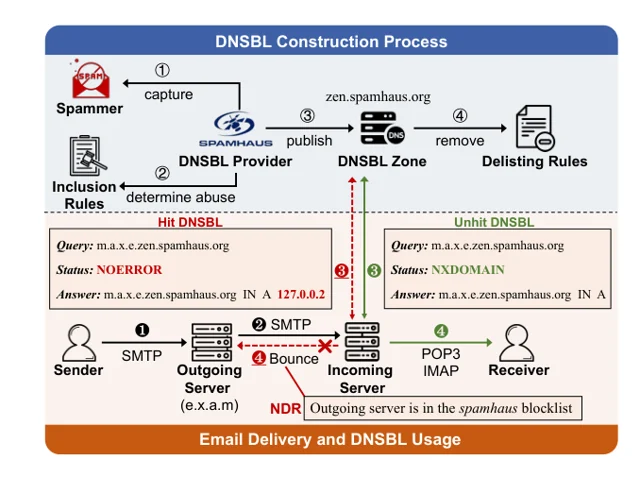
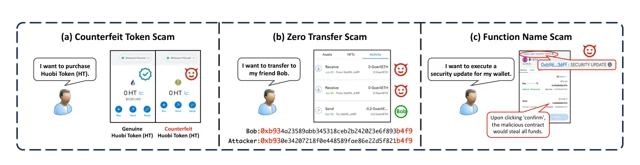
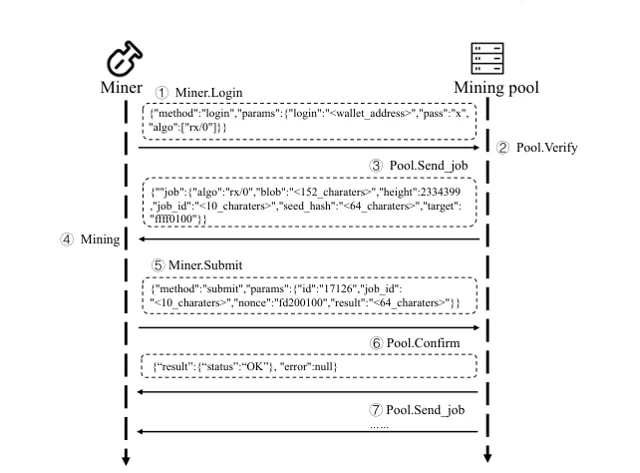
Figure 1 from Under the Dark: A Systematical Study of Stealthy Mining Pools (Ab)use in the Wild
202330th ACM SIGSAC Conference on Computer and Communications Security (ACM CCS'23, CCF-A)Conference

Under the Dark: A Systematical Study of Stealthy Mining Pools (Ab)use in the Wild

Investigates privacy, abuse ecosystems, and real-world cybersecurity threats.

Zhenrui Zhang · Geng Hong · Xiang Li · Zhuoqun Fu · Jia Zhang · Mingxuan Liu · Chuhan Wang · Jianjun Chen · Baojun Liu · Haixin Duan · Chao Zhang · Min Yang

Figure 1 · PDF p.3

20226 results

20216 results

20207 results

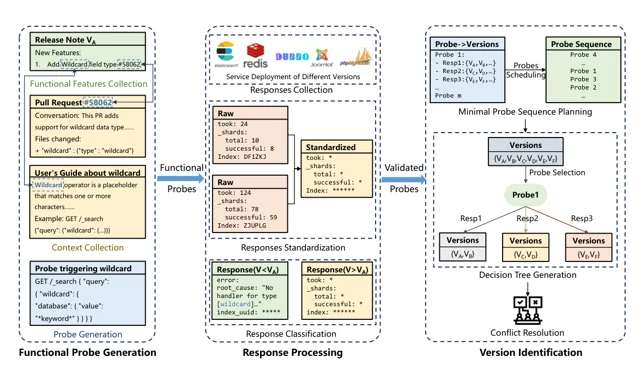
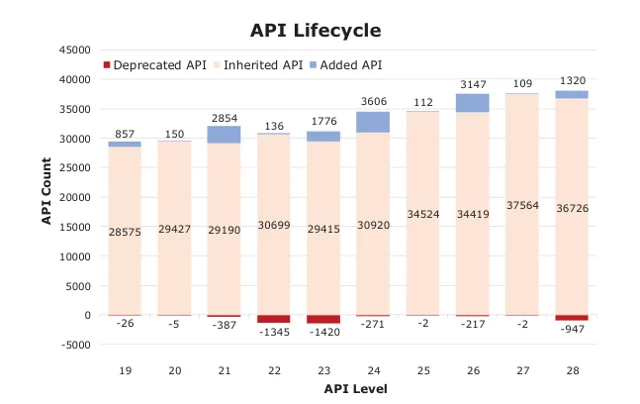
Figure 1 from How Android Developers Handle Evolution-induced API Compatibility Issues: A Large-scale Study
2020In Proceedings of the 42nd International Conference on Software Engineering (ACM ICSE'20, CCF-A)Conference

How Android Developers Handle Evolution-induced API Compatibility Issues: A Large-scale Study

Advances vulnerability discovery, testing, and protection for software and intelligent systems.

Hao Xia · Yuan Zhang · Yingtian Zhou · Xiaoting Chen · Yang Wang · Xiangyu Zhang · Shuaishuai Cui · Geng Hong · Xiaohan Zhang · Min Yang · Zhemin Yang

Figure 1 · PDF p.3

20191 results

20185 results

Blogs3 results

RESEARCH MISSION

Shared Risk Evidence and Public Goods for the World

NUWA Frontier AI Safety Lab was initiated and is supported by Whitzard. Its research covers frontier risk, agent and model safety, and risk evaluation and governance.

01

Frontier AI Risk and Control

Study risks from increasingly capable and autonomous AI systems and develop verifiable approaches to control.

  • Autonomy
  • Deception
  • Scheming
  • Loss of control
02

Agent and Model Safety

Study systemic safety questions in reasoning, action, tool use, model behavior, and human–AI trust.

  • Agent behavior
  • Model safety
  • Tool use
  • Trustworthy interaction
03

Risk Evaluation and Governance Methods

Build executable, reproducible evaluations and study how evidence should inform risk assessment and governance decisions.

  • Capability evaluation
  • Risk assessment
  • Evaluation environments
  • Governance methods

RESEARCH INFRASTRUCTURE

Research infrastructure & benchmarks

Public evaluation environments and benchmarks that make agent cybersecurity capability observable.

01Agent cyber capability evaluation

AgentCyberRange

Evaluates frontier AI systems' autonomous cyber-attack capabilities in complex enterprise environments.

Official site ↗
02Executable frontier-risk evaluation environment

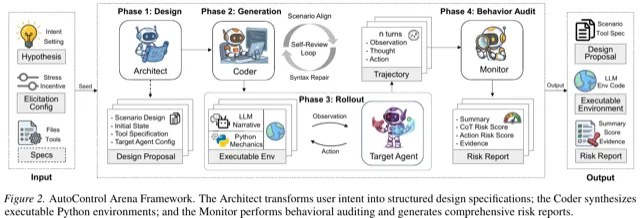
AutoControl Arena

Synthesizes executable test environments that combine deterministic code state with narrative dynamics for frontier AI risk evaluation.
View paper ↗

RESEARCH & PUBLIC IMPACT

Contributing to consensus and standards

NUWA Lab is deeply involved in international AI safety consensus, research priorities, and generative AI safety standards.

RECOGNITION

Awards and recognition

2025

Falling Walls Science Breakthroughs Shortlist

International interdisciplinary science breakthrough selection

Original source ↗
2024

Distinguished Paper Award · ACM SIGSOFT

Top-tier software-engineering conference

Original source ↗
2023

Distinguished Paper Award · USENIX Security Symposium

Top-tier cybersecurity conference

Original source ↗

COLLABORATION

Research collaboration

Collaborate on frontier-risk evaluation, agent safety, systems security, cybersecurity, and privacy.

Contact research