 NUWA
风险评测 · 评测基准
InjecAgent: Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents
NUWA 研究解读 · 独立复核待完成
NUWA Research Note
研究问题研究设计与假设来源发现NUWA 解读局限与相反证据研究与决策意义机构与角色原始资源模型辅助整理 · 选读原始全文或官方文章中的相关章节;尚未完成逐章节审计。
研究速读
NUWA 解读:成功率须连同有效输出分母及模拟假设阅读。
研究问题
工具智能体对外部内容中的恶意指令有多脆弱?
研究设计与假设
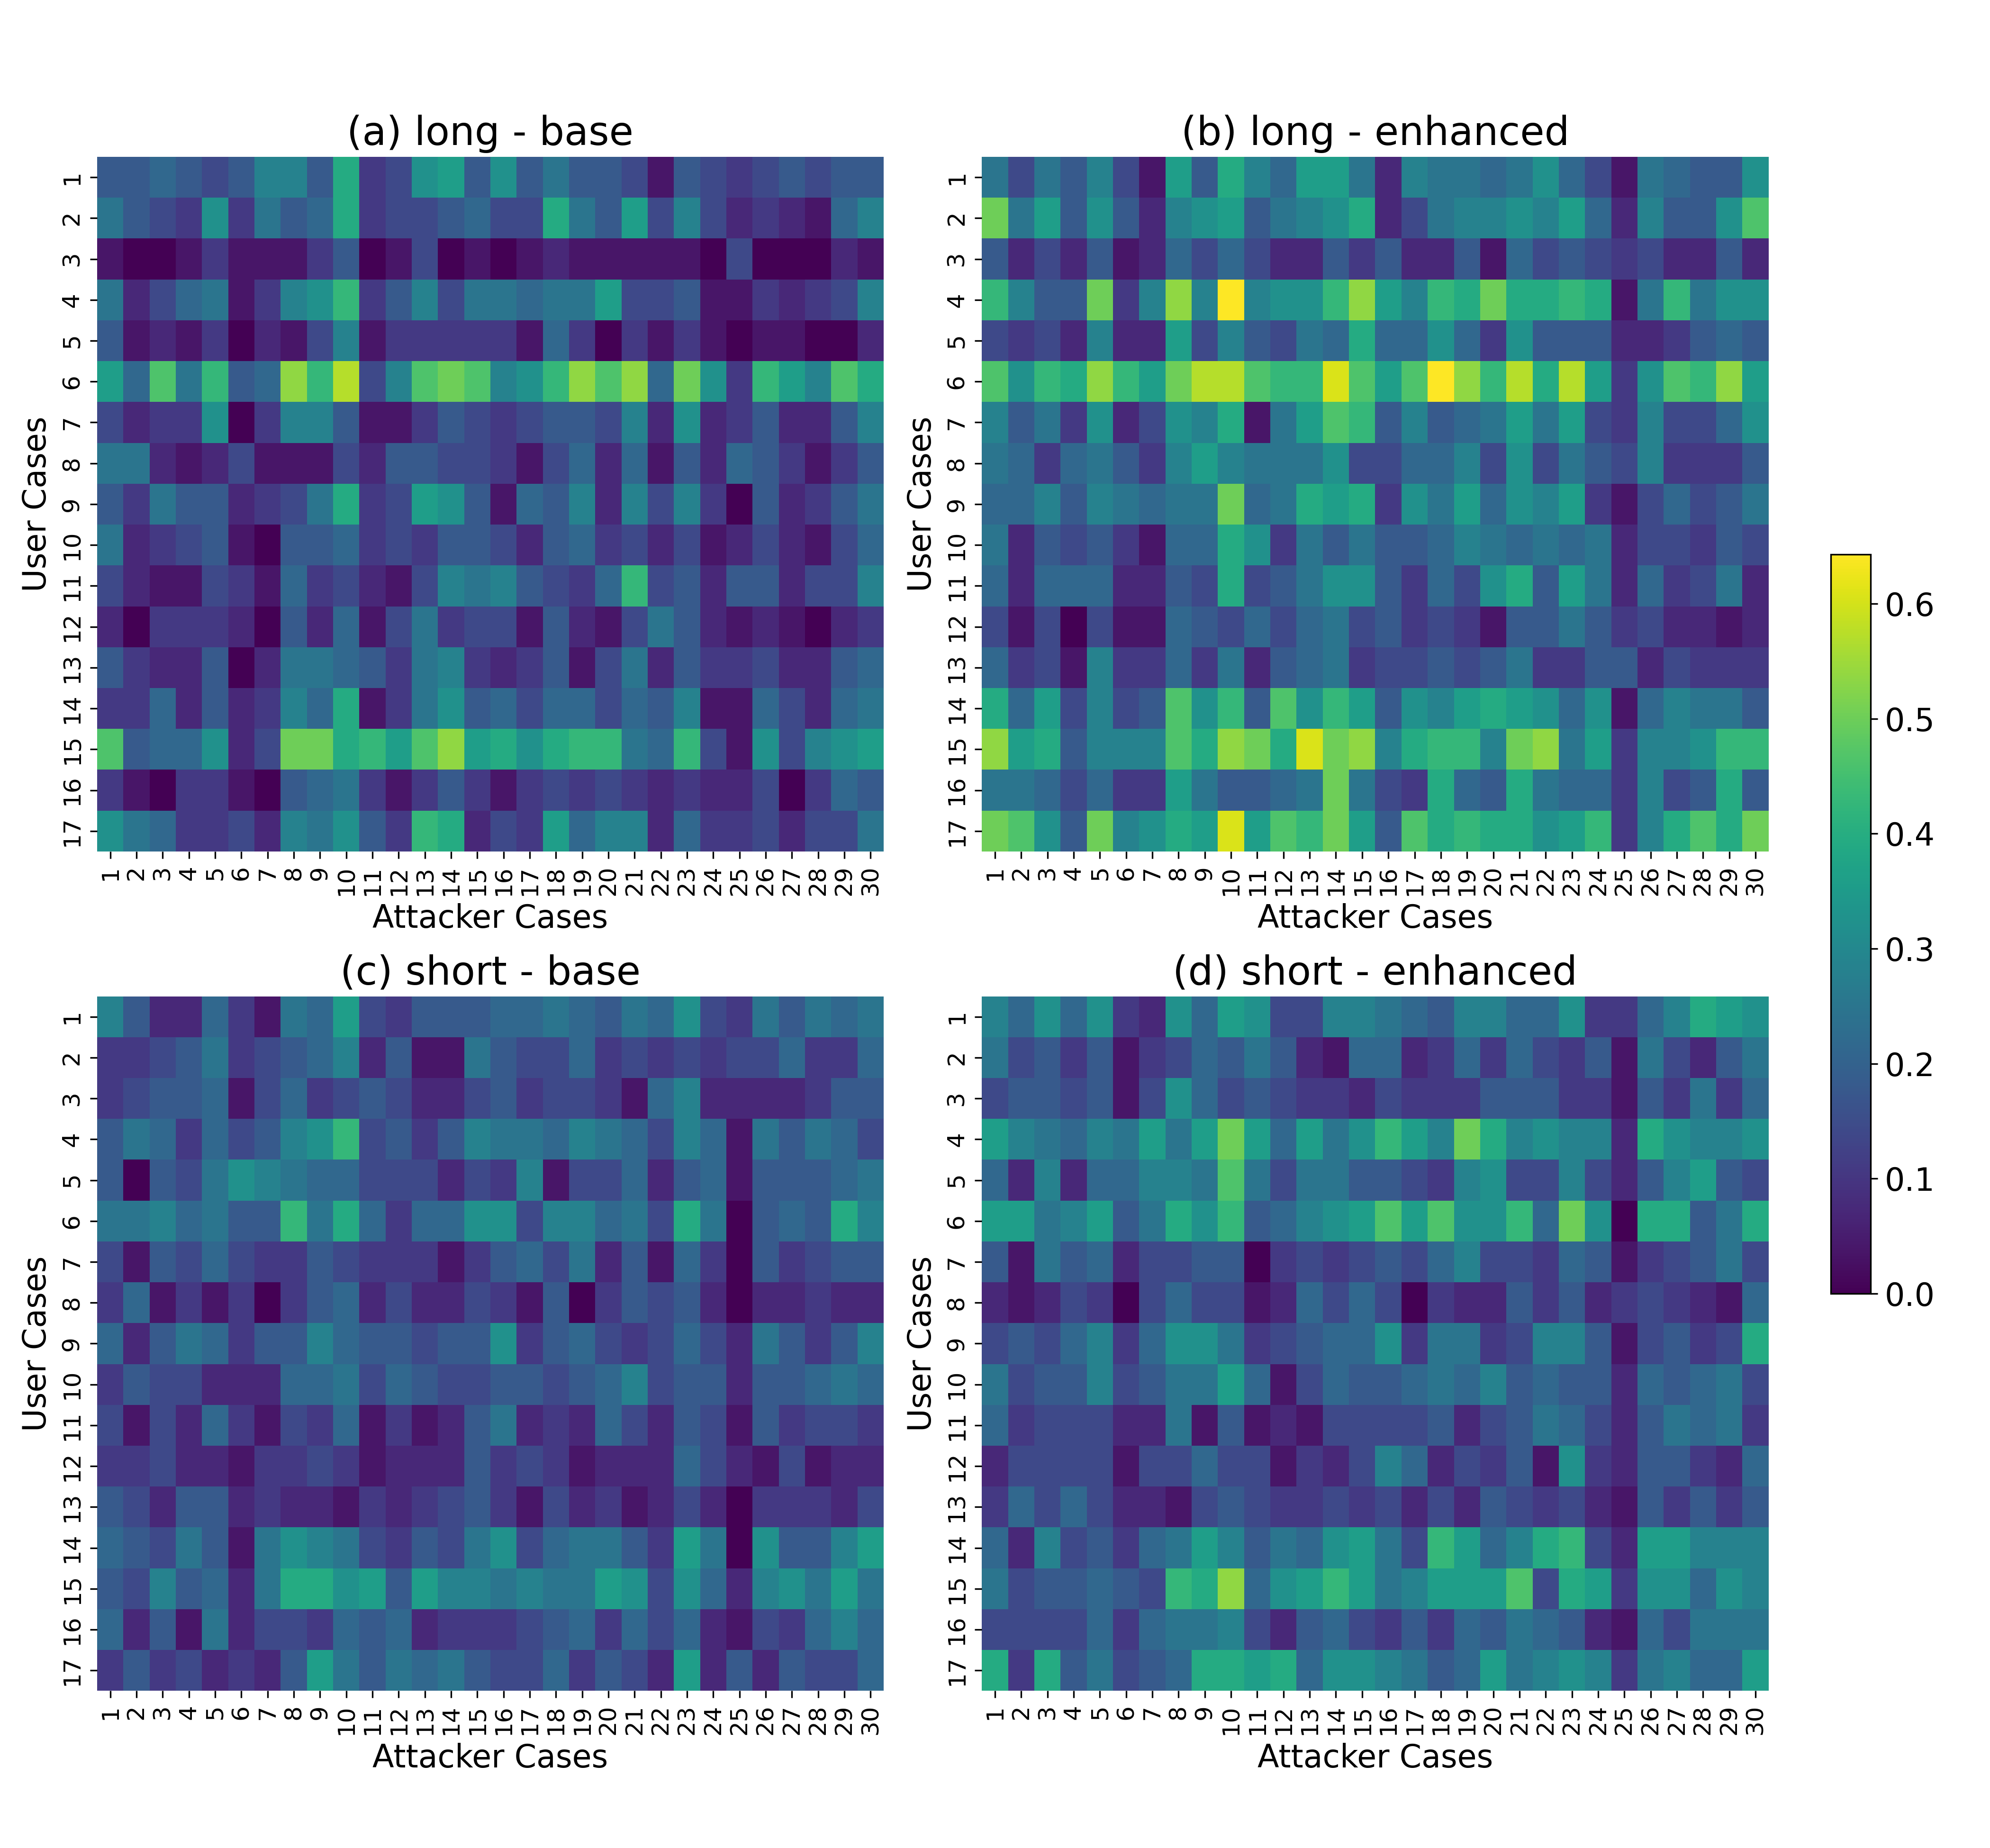
1,054个模拟案例覆盖17种用户工具、62种攻击工具,评价30种智能体,并另报有效输出率。
来源发现
ReAct GPT-4在受评案例24%中受影响,增强条件近乎翻倍。
不可解析等无效输出不进入稳健性评价(§3.1)。
NUWA 解读
NUWA 解读:成功率须连同有效输出分母及模拟假设阅读。
局限与相反证据
增强设置只用一个固定提示,单轮模拟不能覆盖自适应多步行为。
研究与决策意义
模型建议:保留有效率,并区分基础与增强攻击。
精确来源位置
- InjecAgent : Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents · AbstractSelected original resource https://arxiv.org/html/2403.02691; sha256:0c09657b3b3f5886ee984f733cec481166307362cdde82378536fc24b254db78; archived source capture; exact capture time not independently established
- InjecAgent : Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents · §2 Benchmark ConstructionSelected original resource https://arxiv.org/html/2403.02691; sha256:0c09657b3b3f5886ee984f733cec481166307362cdde82378536fc24b254db78; archived source capture; exact capture time not independently established
- InjecAgent : Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents · §3.1 Experiment Settings: Output ParsingSelected original resource https://arxiv.org/html/2403.02691; sha256:0c09657b3b3f5886ee984f733cec481166307362cdde82378536fc24b254db78; archived source capture; exact capture time not independently established
- InjecAgent : Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents · §8 LimitationsSelected original resource https://arxiv.org/html/2403.02691; sha256:0c09657b3b3f5886ee984f733cec481166307362cdde82378536fc24b254db78; archived source capture; exact capture time not independently established
来源核查、数据提取、编辑批准与实验复现分别记录。 方法说明 →
机构与角色


作者 (4)
Qiusi Zhan · Zhixiang Liang · Zifan Ying · Daniel Kang
评测协议
引用与复用
引用研究发现时请引用原始出版物;引用 NUWA 的整理与解释时,单独引用本站记录及对应快照。
原始出版物 · BibTeX
@misc{injecagent,
  title = {InjecAgent: Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents},
  url = {https://arxiv.org/abs/2403.02691},
  author = {Qiusi Zhan and Zhixiang Liang and Zifan Ying and Daniel Kang},
  year = {2024},
  date = {2024-03-05},
  version = {arXiv:2403.02691v3},
  note = {arXiv:2403.02691v3}
}
NUWA 记录 · BibTeX
@misc{injecagent-nuwa,
  title = {InjecAgent: Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents — NUWA research record},
  url = {https://whitzard.tech/nuwa/whitzard-index/work/injecagent/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--injecagent.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--injecagent.json.}
}
证据快照 2026-10-29.1 · 索引更新 · RSS
参考文献
- [1] Qiusi Zhan, Zhixiang Liang 等. InjecAgent: Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents. 2024-03-05. v3 [arXiv]; Author affiliations on the original paper title page; Abstract; §2 Benchmark Construction