 NUWA
风险评测 · 评测基准
RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts
NUWA 研究解读 · 独立复核待完成
NUWA Research Note
研究问题研究设计与假设来源发现NUWA 解读局限与相反证据研究与决策意义机构与角色原始资源模型辅助整理 · 选读原始全文或官方文章中的相关章节;尚未完成逐章节审计。
研究速读
NUWA 解读:排序取决于时间分配和样本选择,不能视为统一研究能力排名。
研究问题
开放式机器学习研究工程中,智能体与专家表现如何?
研究设计与假设
七个环境收集61位专家的71次八小时尝试;比较改变总时间、框架和最佳样本选择。
来源发现
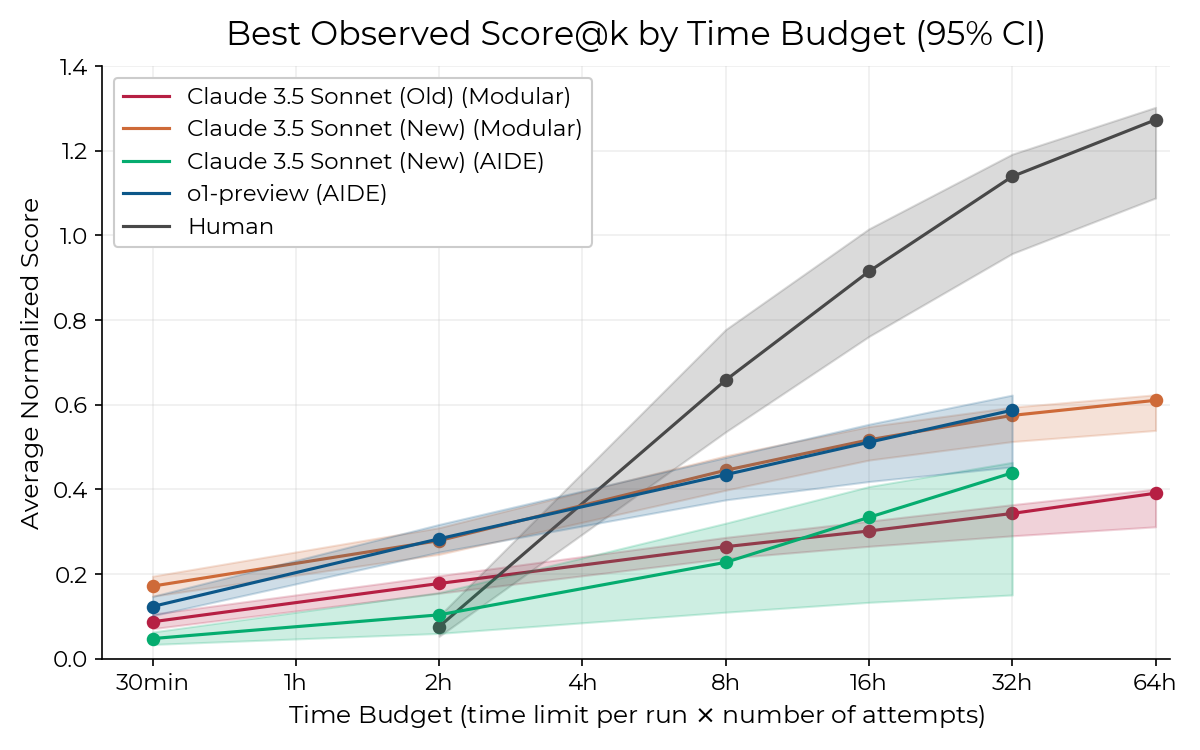
82%的专家尝试得分非零,24%达到或超过参考解。
两小时条件下智能体领先,32小时累计条件下人类约为最佳智能体得分两倍。
NUWA 解读
NUWA 解读:排序取决于时间分配和样本选择,不能视为统一研究能力排名。
局限与相反证据
七个环境不能覆盖前沿研发;有限框架迭代可能低估智能体能力(§6.3)。
研究与决策意义
模型建议:同时引用归一化得分、框架、总时间及尝试聚合方式。
精确来源位置
- RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts · AbstractSelected original resource https://arxiv.org/html/2411.15114v2; sha256:4a4df1346307f7b31e65c6c0e8b5533d0a6649904ea600d5b0d4d893a5d64c58; archived source capture; exact capture time not independently established
- RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts · §3.1 Design goalsSelected original resource https://arxiv.org/html/2411.15114v2; sha256:4a4df1346307f7b31e65c6c0e8b5533d0a6649904ea600d5b0d4d893a5d64c58; archived source capture; exact capture time not independently established
- RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts · §4 Experiments and resultsSelected original resource https://arxiv.org/html/2411.15114v2; sha256:4a4df1346307f7b31e65c6c0e8b5533d0a6649904ea600d5b0d4d893a5d64c58; archived source capture; exact capture time not independently established
- RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts · §6.3 Other LimitationsSelected original resource https://arxiv.org/html/2411.15114v2; sha256:4a4df1346307f7b31e65c6c0e8b5533d0a6649904ea600d5b0d4d893a5d64c58; archived source capture; exact capture time not independently established
来源核查、数据提取、编辑批准与实验复现分别记录。 方法说明 →
机构与角色





作者 (23)
Hjalmar Wijk · Tao Lin · Joel Becker · Sami Jawhar · Neev Parikh · Thomas Broadley · Lawrence Chan · Michael Chen · Josh Clymer · Jai Dhyani · Elena Ericheva · Katharyn Garcia · Brian Goodrich · Nikola Jurkovic · Holden Karnofsky · Megan Kinniment · Aron Lajko · Seraphina Nix · Lucas Sato · William Saunders · Maksym Taran · Ben West · Elizabeth Barnes
评测协议
引用与复用
引用研究发现时请引用原始出版物;引用 NUWA 的整理与解释时,单独引用本站记录及对应快照。
原始出版物 · BibTeX
@misc{re-bench,
  title = {RE-Bench: Evaluating frontier AI R\&D capabilities of language model agents against human experts},
  url = {https://arxiv.org/abs/2411.15114v2},
  author = {Hjalmar Wijk and Tao Lin and Joel Becker and Sami Jawhar and Neev Parikh and Thomas Broadley and Lawrence Chan and Michael Chen and Josh Clymer and Jai Dhyani and Elena Ericheva and Katharyn Garcia and Brian Goodrich and Nikola Jurkovic and Holden Karnofsky and Megan Kinniment and Aron Lajko and Seraphina Nix and Lucas Sato and William Saunders and Maksym Taran and Ben West and Elizabeth Barnes},
  year = {2024},
  date = {2024-11-22},
  version = {arXiv:2411.15114v2},
  note = {arXiv:2411.15114v2}
}
NUWA 记录 · BibTeX
@misc{re-bench-nuwa,
  title = {RE-Bench: Evaluating frontier AI R\&D capabilities of language model agents against human experts — NUWA research record},
  url = {https://whitzard.tech/nuwa/whitzard-index/work/re-bench/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--re-bench.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--re-bench.json.}
}
证据快照 2026-10-29.1 · 索引更新 · RSS
参考文献
- [1] Hjalmar Wijk, Tao Lin 等. RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts. 2025-05-27. v2 [arXiv]; Author affiliations on the original paper title page; Abstract; §3.1 Design goals