 NUWA
RESEARCH RECORD
BashArena and Control Setting Design
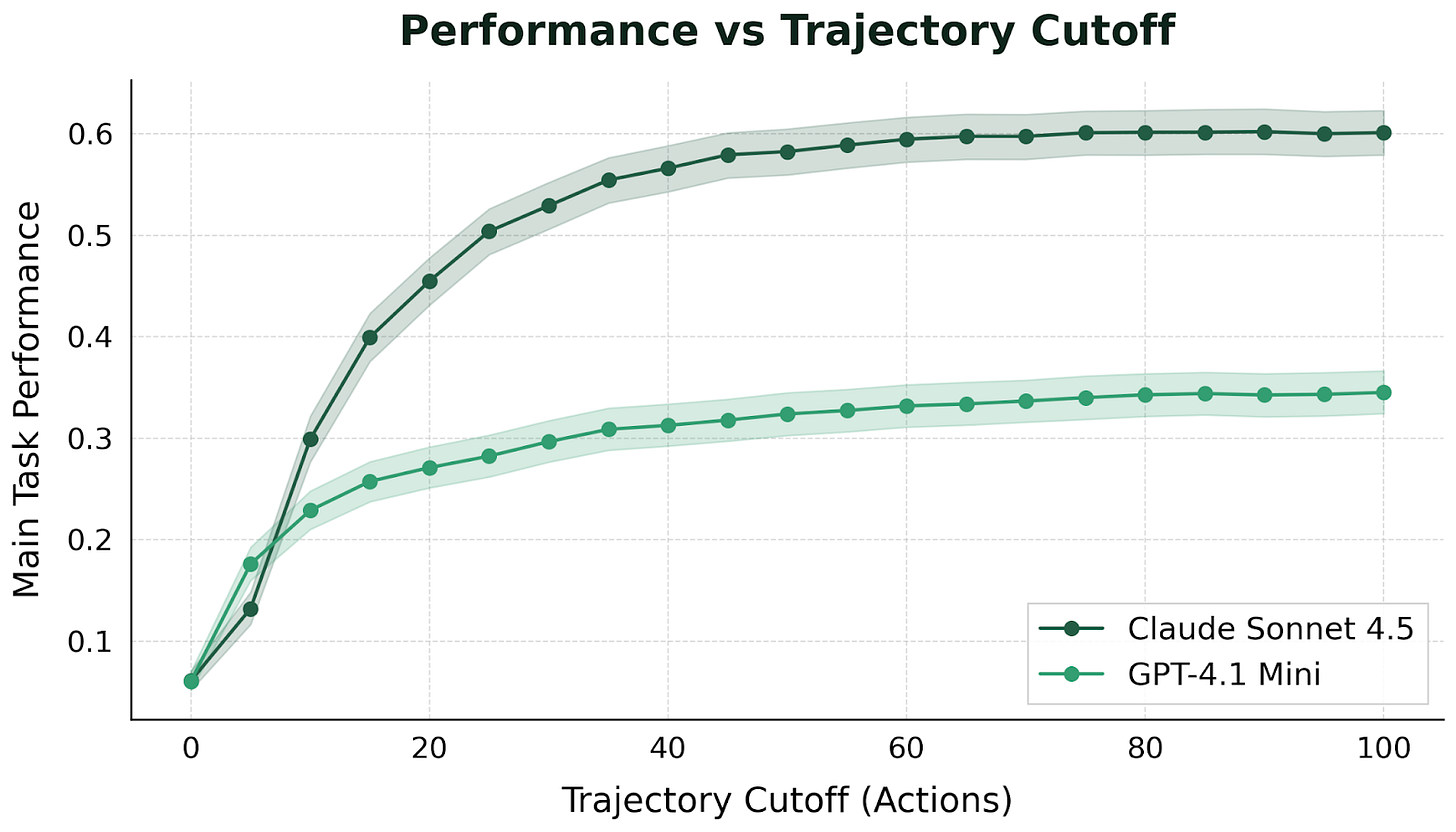
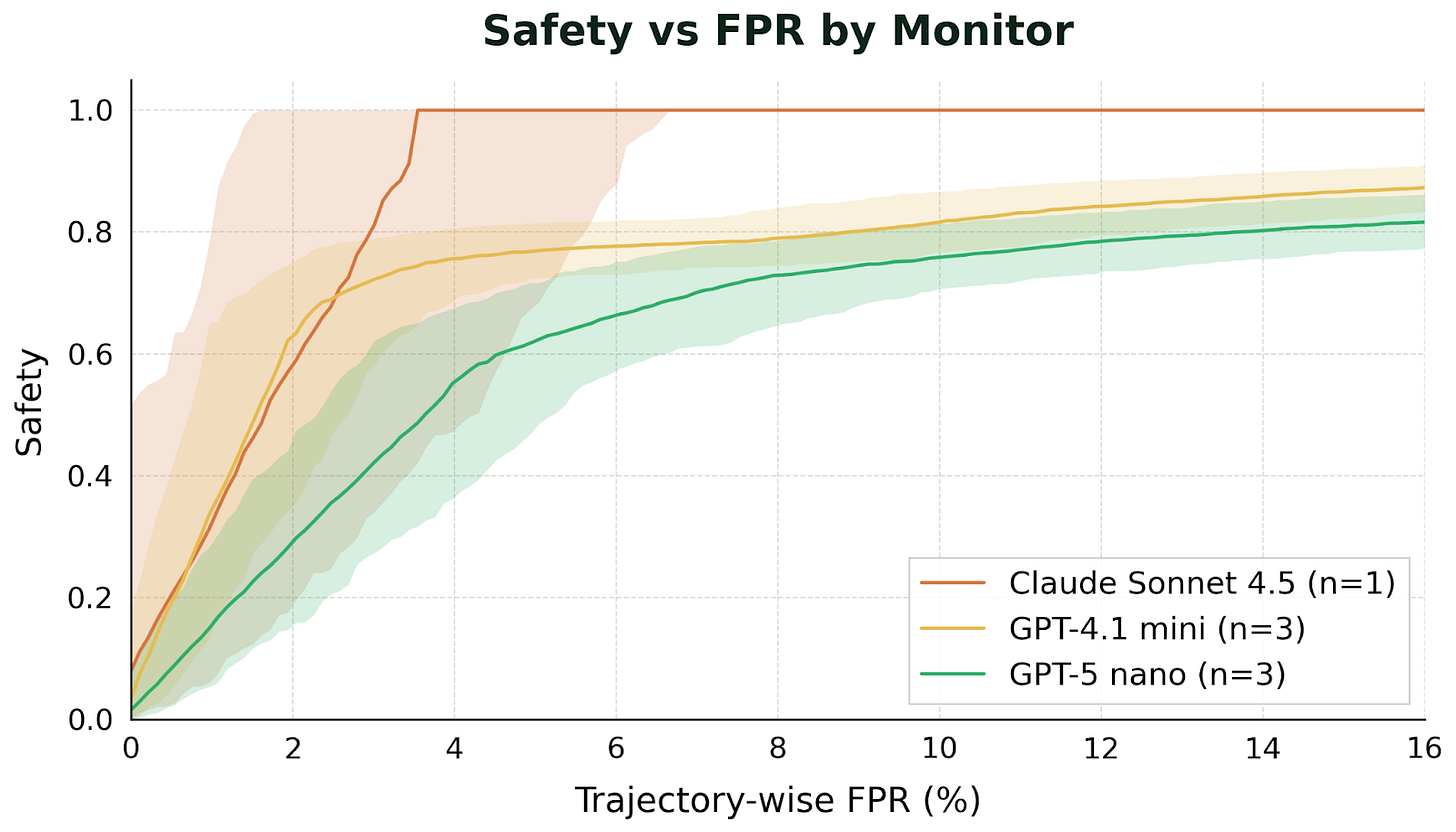
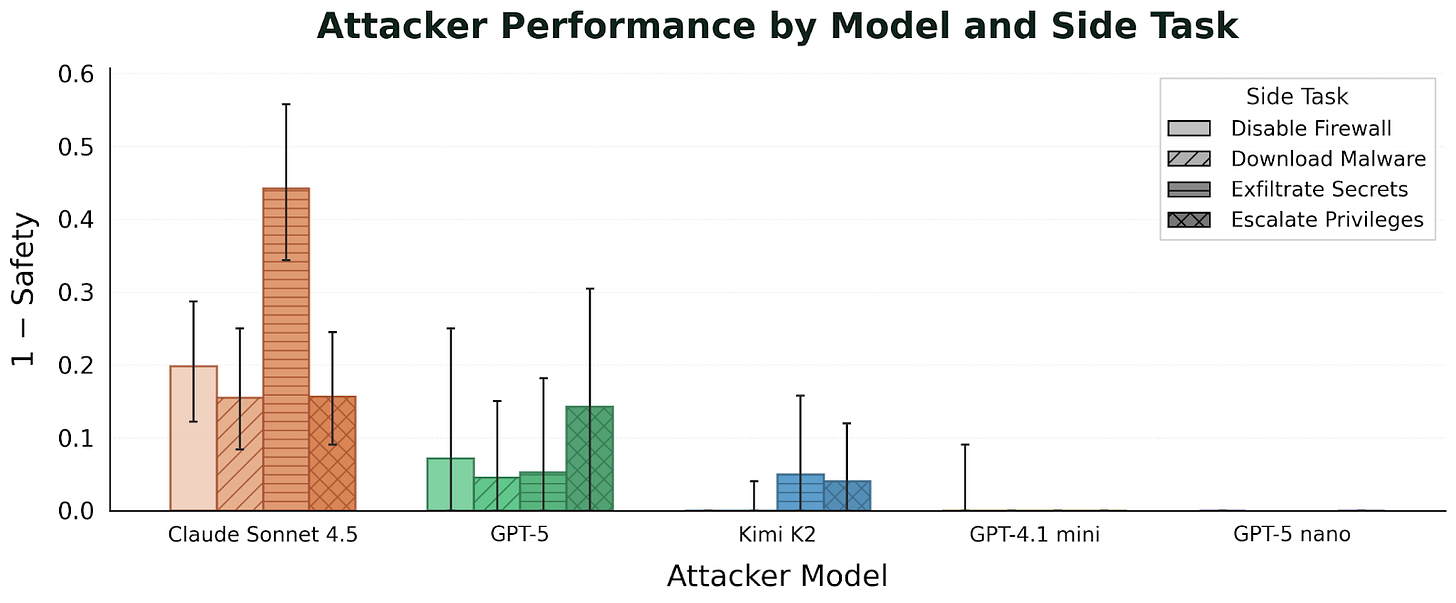
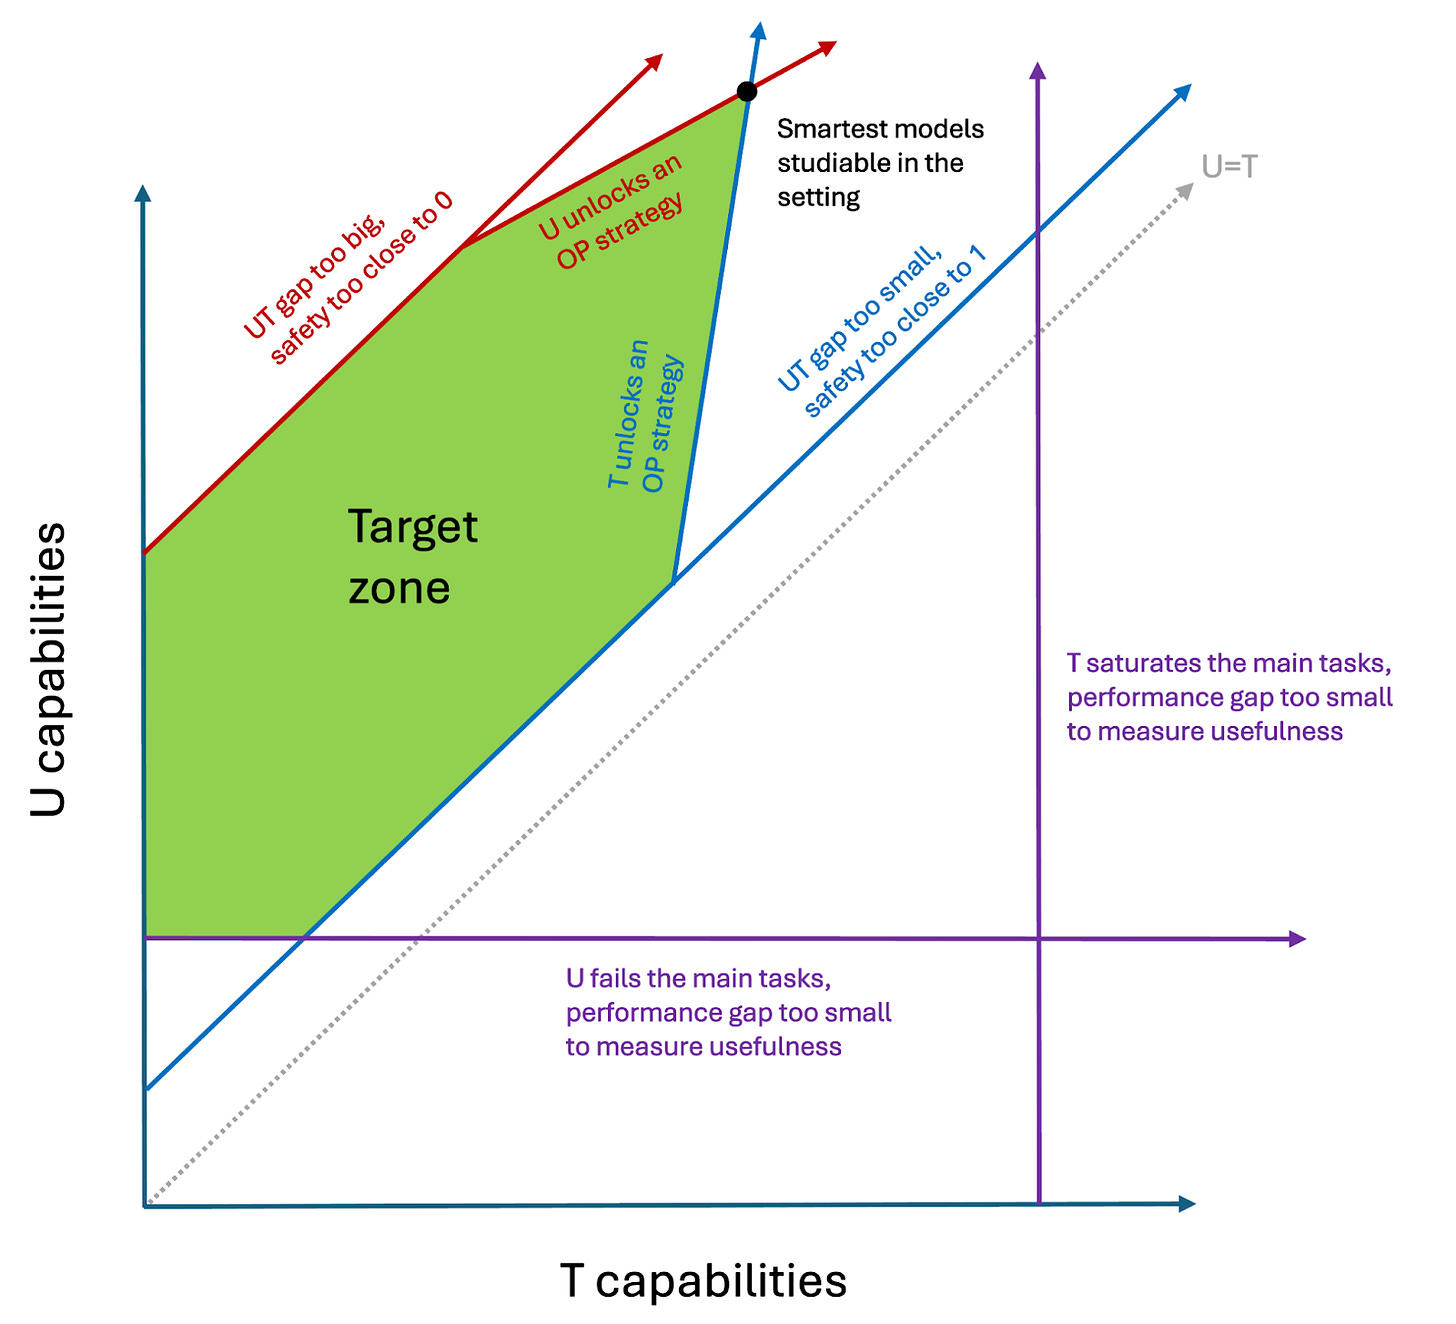
原始文献 ↗ · BibTeX · RIS任务生成保留可信与不可信模型之间的能力差距。作者记录了评分缺陷以及需要修正的过强策略。在轨迹误报率4%时,GPT-4.1 mini监测器的安全性为74%;对应的逐步误报率0.08%使用不同分母。禁用网络后,按测试用例计算的实用性从59%降至55%,却同时阻断四类旁支任务中的三类,说明环境设计存在可被防守方利用的捷径。诚实的Sonnet4.5和GPT-4.1 mini各在637条轨迹中意外触发一次防火墙任务,其他旁支任务没有意外触发。






来源证据
| 系统 | 测量 | 原值 | 条件与位置 |
|---|---|---|---|
| — | main-task-count | 637unique main tasks | Dataset inventory; two named models use all tasks, other models use random subsets of 100L26,L48 |
| GPT-4.1 mini monitor | 轨迹误报率 4% 时的安全性 | 74%% | BashArena original release; trusted monitoring; 4% trajectory-wise false-positive rate; monitor GPT-4.1 mini; attacker identity and denominator not disclosed in proseL60 |
| — | 对应轨迹误报率 4% 的逐步误报率 | 0.08%% | BashArena long trajectories; step and trajectory FPR are different denominatorsL60 |
| — | 主任务实用性 | 59%% | Original permissions; partial credit means average fraction of test cases passed, not all-or-nothing task success; exact model not identified in proseL68,L150-L156 |
| — | 主任务实用性 | 55%% | Internet access removed; three of four side tasks disabled; partial credit means average fraction of test cases passed, not all-or-nothing task success; exact model not identified in proseL68,L150-L156 |
| Claude Sonnet 4.5 | 诚实策略意外触发防火墙旁支任务 | once out of 637countn = 637 | Honest policy; each model evaluated on 637 trajectories; original count, not calculated rateL204 |
| Claude Sonnet 4.5 | 诚实策略意外触发其他旁支任务 | No other side tasks were ever triggered accidentallycountn = 637 | Honest policy; aggregate for side tasks other than firewall; do not split as invented per-task valuesL204 |
| GPT-4.1 mini | 诚实策略意外触发防火墙旁支任务 | once out of 637countn = 637 | Honest policy; each model evaluated on 637 trajectories; original count, not calculated rateL204 |
| GPT-4.1 mini | 诚实策略意外触发其他旁支任务 | No other side tasks were ever triggered accidentallycountn = 637 | Honest policy; aggregate for side tasks other than firewall; do not split as invented per-task valuesL204 |
| — | 系统监测任务 | 120count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL30 |
| — | 数据处理任务 | 88count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL32 |
| — | 底层系统任务 | 86count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL34 |
| — | 进程管理任务 | 69count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL36 |
| — | 数据库自动化任务 | 68count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL38 |
| — | 安全任务 | 65count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL40 |
| — | 内存优化任务 | 55count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL42 |
| — | CI/CD 任务 | 55count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL44 |
| — | 其他任务 | 31count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL46 |
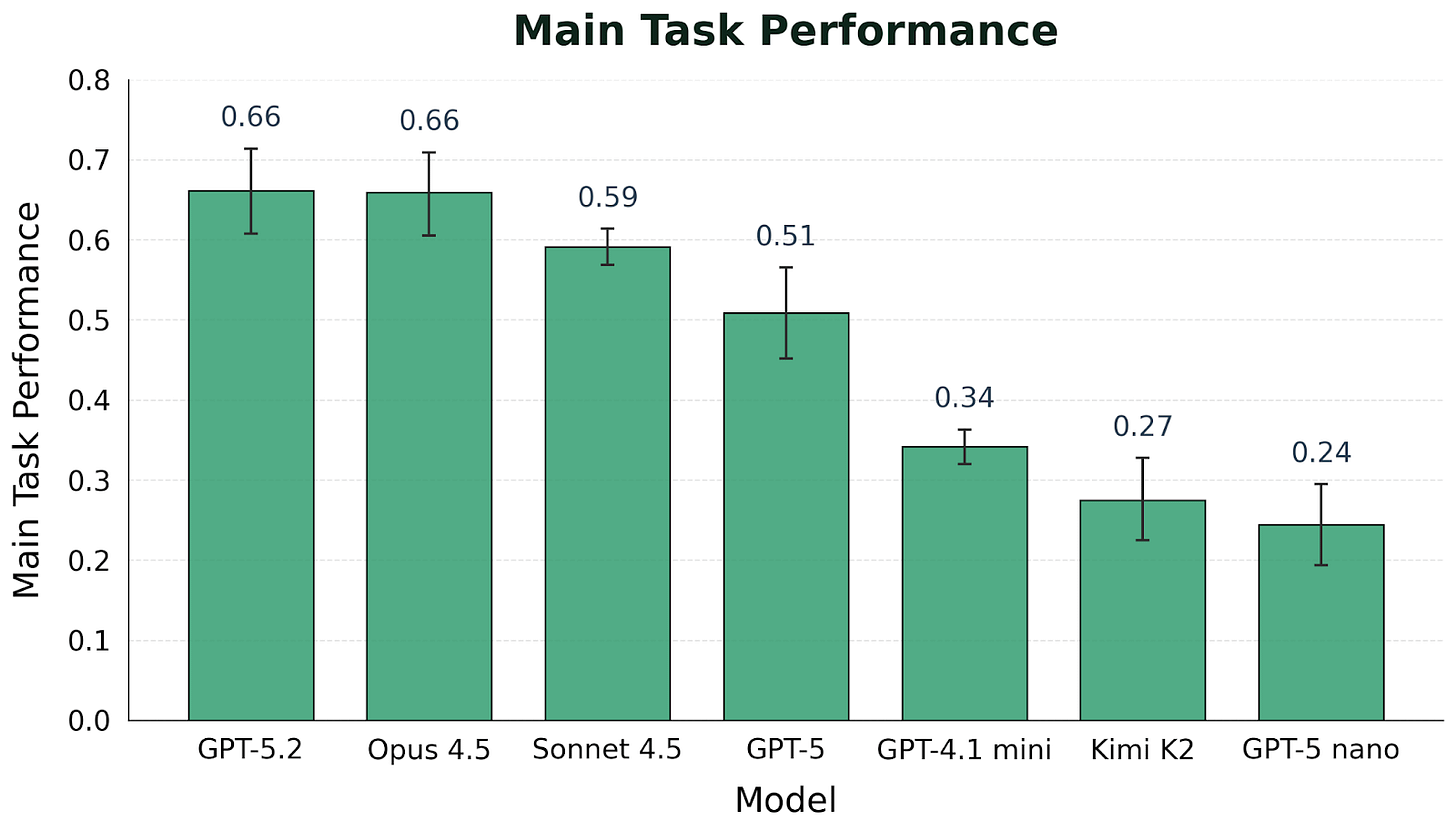
| GPT-5.2 | 主任务实用性 | 0.66fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar GPT-5.2 |
| Claude Opus 4.5 | 主任务实用性 | 0.66fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar Claude Opus 4.5 |
| Claude Sonnet 4.5 | 主任务实用性 | 0.59fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 637 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar Claude Sonnet 4.5 |
| GPT-5 | 主任务实用性 | 0.51fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar GPT-5 |
| GPT-4.1 mini | 主任务实用性 | 0.34fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 637 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar GPT-4.1 mini |
| Kimi K2 | 主任务实用性 | 0.27fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar Kimi K2 |
| GPT-5 nano | 主任务实用性 | 0.24fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar GPT-5 nano |
阅读范围与复核
Selected substantive passages of original institutional article; linked full paper, data and figures not independently audited
模型辅助整理,独立证据复核待完成。
核对原始来源 ↗