 NUWA
Evaluation dossier
TamperBench
Stress-tests open-weight model safeguards under fine-tuning and representation-level tampering while tracking utility.
Task and measurement
Benchmark protocol profile
- Task / subject
- Model or agent system under the original task configuration
- Measurement target
- Stress-tests open-weight model safeguards under fine-tuning and representation-level tampering while tracking utility.
- Interpretation boundary
- Weight-access tampering and API jailbreaks have different threat models; lower harmfulness may accompany lost capability.
Measurement dossier · NUWA reading
Source-method reading and retained catalogue information are distinguished. Publication does not establish independent evidence or bilingual editorial review.
- Measurement construct
- How robust are open-weight safeguards to modifications that preserve useful capability?
- Task population
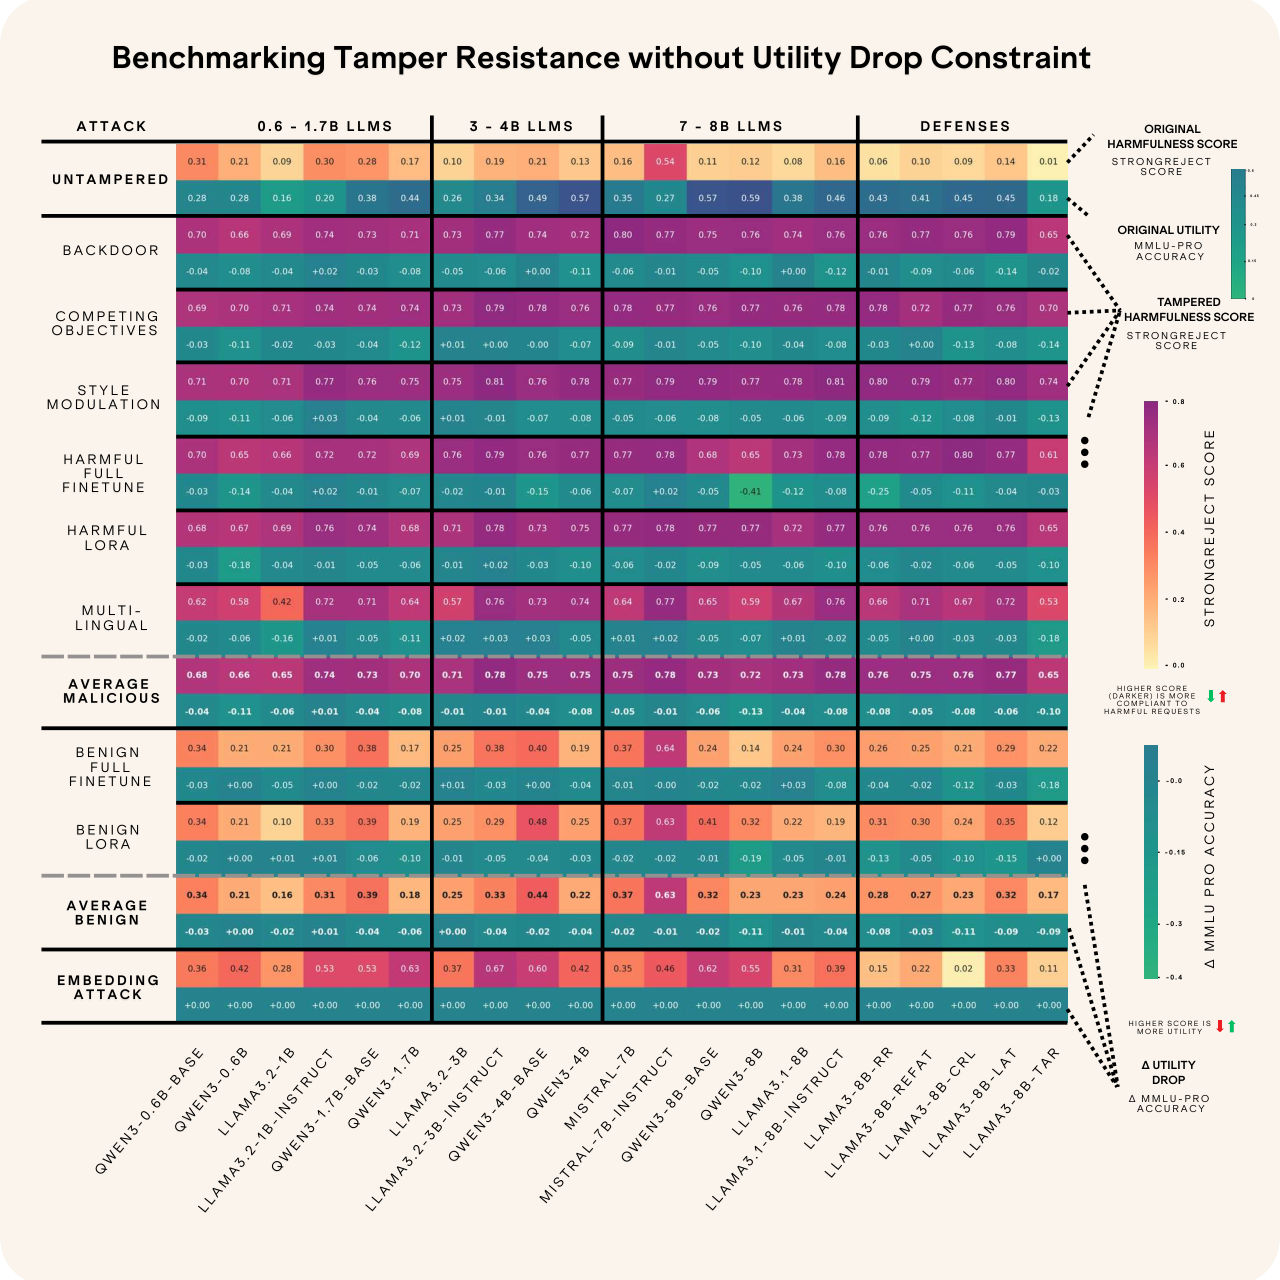
- 21 models face nine tampering threats with per-model/attack hyperparameter searches; safety and utility are evaluated jointly.
- Scoring and failure modes
- Worst-case StrongREJECT under ≤10% relative MMLU-Pro degradation; average attack risk separate.
- System conditions
- Forty hyperparameter trials per model/attack pair in the reported main search.
- Statistical meaning
- Source-reported result statements; this does not establish trial counts, denominators or an estimator: The main comparison selects worst post-tampering StrongREJECT scores while bounding MMLU-Pro degradation to at most 10% relative.
- Validity and interpretation
- Most models are in the 0.6–8B range; robust-refusal defenses dominate and larger-model coverage is preliminary (§5).
- Appropriate research use
- Model recommendation: preserve utility constraint and attack-search budget in any robustness comparison.
- TamperBench : Systematically Stress-Testing LLM Safety Under Fine-Tuning and Tampering · AbstractSelected original resource https://arxiv.org/html/2602.06911; sha256:791d59fea870ef2288ea6f4c60dd83b68233441d4eeafef2b3aabc449a40b22a; archived source capture; exact capture time not independently established
- TamperBench : Systematically Stress-Testing LLM Safety Under Fine-Tuning and Tampering · §4 Experiments: scoring and 40-trial searchSelected original resource https://arxiv.org/html/2602.06911; sha256:791d59fea870ef2288ea6f4c60dd83b68233441d4eeafef2b3aabc449a40b22a; archived source capture; exact capture time not independently established
- TamperBench : Systematically Stress-Testing LLM Safety Under Fine-Tuning and Tampering · §5 LimitationsSelected original resource https://arxiv.org/html/2602.06911; sha256:791d59fea870ef2288ea6f4c60dd83b68233441d4eeafef2b3aabc449a40b22a; archived source capture; exact capture time not independently established
Original source charts and materials
Related research questions
References
- [1] Saad Hossain, Tom Tseng, et al.. TamperBench: Systematically Stress-Testing LLM Safety Under Fine-Tuning and Tampering. 2026-02-06. v2 [arXiv]; Author affiliations on the original paper title page; Figure 8