
WhitzardNUWA Lab ↗
NUWANUWA INDEX

Search NUWA Index

Research · Benchmarks · Findings · Perspectives

中文

MODEL COMPARISON

Compare models and agent systems

Choose a risk topic and a measurement protocol, then compare 2–4 evaluated systems. Capability, propensity and observed behavior retain their own meaning.

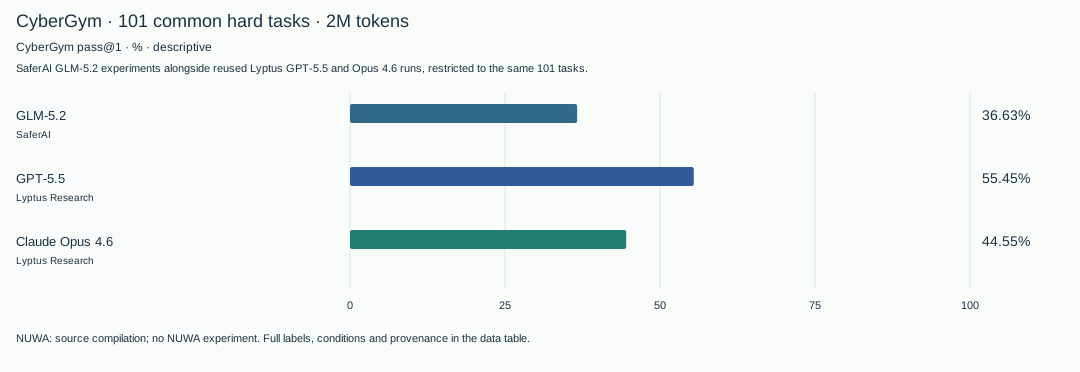
CyberGym · 101 common hard tasks · 2M tokens

SaferAI GLM-5.2 experiments alongside reused Lyptus GPT-5.5 and Opus 4.6 runs, restricted to the same 101 tasks.

Descriptive comparison. Harness, provider and reasoning conditions differ; this is not a strict model ranking.

GLM-5.2 (GLM-5.2); CyberGym pass@1: 36.63%; 37/101; CyberGym Level 1 hard-task matched subset; {"modelVersion":null,"harness":"Inspect Evals","tools":null,"budget":"2M tokens per task"}; ? attempts; evaluator SaferAI; reporter SaferAI; https://www.safer-ai.org/u/2026/08/SaferAI-GLM-Evaluation-Report.pdf; v1.1 · revised 26 August 2026; p.8 Fig.3 printed bar label; released 2026-06-16; evaluated ?; published 2026-08-02; public 2026-08-26; ; 122 GLM tasks run; comparison restricted to 101 matched tasks. Nineteen tasks lacked comparator coverage; two tasks excluded as defective. Hard-task selection not representative of all 1507 tasks. GPT-5.5 (GPT-5.5); CyberGym pass@1: 55.45%; 56/101; CyberGym Level 1 hard-task matched subset; {"modelVersion":null,"harness":null,"tools":null,"budget":"2M tokens per task"}; ? attempts; evaluator Lyptus Research; reporter SaferAI; https://www.safer-ai.org/u/2026/08/SaferAI-GLM-Evaluation-Report.pdf; v1.1 · revised 26 August 2026; p.8 Fig.3 printed bar label; released 2026-04-23; evaluated ?; published 2026-08-02; public 2026-08-26; ; 122 GLM tasks run; comparison restricted to 101 matched tasks. Nineteen tasks lacked comparator coverage; two tasks excluded as defective. Hard-task selection not representative of all 1507 tasks. Claude Opus 4.6 (Claude Opus 4.6); CyberGym pass@1: 44.55%; 45/101; CyberGym Level 1 hard-task matched subset; {"modelVersion":null,"harness":null,"tools":null,"budget":"2M tokens per task"}; ? attempts; evaluator Lyptus Research; reporter SaferAI; https://www.safer-ai.org/u/2026/08/SaferAI-GLM-Evaluation-Report.pdf; v1.1 · revised 26 August 2026; p.8 Fig.3 printed bar label; released 2026-02-05; evaluated ?; published 2026-08-02; public 2026-08-26; ; 122 GLM tasks run; comparison restricted to 101 matched tasks. Nineteen tasks lacked comparator coverage; two tasks excluded as defective. Hard-task selection not representative of all 1507 tasks.CyberGym · 101 common hard tasks · 2M tokensCyberGym pass@1 · % · descriptiveSaferAI GLM-5.2 experiments alongside reused Lyptus GPT-5.5 and Opus 4.6 runs, restricted to the same 101 tasks.0255075100GLM-5.2; 36.63%; SaferAIGLM-5.236.63%SaferAIGPT-5.5; 55.45%; Lyptus ResearchGPT-5.555.45%Lyptus ResearchClaude Opus 4.6; 44.55%; Lyptus ResearchClaude Opus 4.644.55%Lyptus ResearchNUWA: source compilation; no NUWA experiment. Full labels, conditions and provenance in the data table.Snapshot: 2026-10-29.1; GLM-5.2 Risk Evaluation Report; GLM-5.2 (GLM-5.2); CyberGym pass@1: 36.63%; 37/101; CyberGym Level 1 hard-task matched subset; {"modelVersion":null,"harness":"Inspect Evals","tools":null,"budget":"2M tokens per task"}; ? attempts; evaluator SaferAI; reporter SaferAI; https://www.safer-ai.org/u/2026/08/SaferAI-GLM-Evaluation-Report.pdf; v1.1 · revised 26 August 2026; p.8 Fig.3 printed bar label; released 2026-06-16; evaluated ?; published 2026-08-02; public 2026-08-26; ; 122 GLM tasks run; comparison restricted to 101 matched tasks. Nineteen tasks lacked comparator coverage; two tasks excluded as defective. Hard-task selection not representative of all 1507 tasks. GPT-5.5 (GPT-5.5); CyberGym pass@1: 55.45%; 56/101; CyberGym Level 1 hard-task matched subset; {"modelVersion":null,"harness":null,"tools":null,"budget":"2M tokens per task"}; ? attempts; evaluator Lyptus Research; reporter SaferAI; https://www.safer-ai.org/u/2026/08/SaferAI-GLM-Evaluation-Report.pdf; v1.1 · revised 26 August 2026; p.8 Fig.3 printed bar label; released 2026-04-23; evaluated ?; published 2026-08-02; public 2026-08-26; ; 122 GLM tasks run; comparison restricted to 101 matched tasks. Nineteen tasks lacked comparator coverage; two tasks excluded as defective. Hard-task selection not representative of all 1507 tasks. Claude Opus 4.6 (Claude Opus 4.6); CyberGym pass@1: 44.55%; 45/101; CyberGym Level 1 hard-task matched subset; {"modelVersion":null,"harness":null,"tools":null,"budget":"2M tokens per task"}; ? attempts; evaluator Lyptus Research; reporter SaferAI; https://www.safer-ai.org/u/2026/08/SaferAI-GLM-Evaluation-Report.pdf; v1.1 · revised 26 August 2026; p.8 Fig.3 printed bar label; released 2026-02-05; evaluated ?; published 2026-08-02; public 2026-08-26; ; 122 GLM tasks run; comparison restricted to 101 matched tasks. Nineteen tasks lacked comparator coverage; two tasks excluded as defective. Hard-task selection not representative of all 1507 tasks.
System / modelResult / sampleConfigurationAttribution / dates
GLM-5.2capability36.63%—37/101modelVersion: —harness: Inspect Evalstools: —budget: 2M tokens per taskCyberGym Level 1 hard-task matched subsetEvaluator: SaferAISaferAIEvaluated — · Report 2026-08-02Public since 2026-08-26
GPT-5.5capability55.45%—56/101modelVersion: —harness: —tools: —budget: 2M tokens per taskCyberGym Level 1 hard-task matched subsetEvaluator: Lyptus ResearchSaferAIEvaluated — · Report 2026-08-02Public since 2026-08-26
Claude Opus 4.6capability44.55%—45/101modelVersion: —harness: —tools: —budget: 2M tokens per taskCyberGym Level 1 hard-task matched subsetEvaluator: Lyptus ResearchSaferAIEvaluated — · Report 2026-08-02Public since 2026-08-26
Comparison conditions and interpretation
  • Task intersection · matched
    101 common Level1 hard tasks; 122 initial tasks minus 19 without comparator coverage and two defective tasks.
  • Metric / budget · matched
    Per-task success, pass@1, 2M token setting. No higher-budget retry overlay is combined here.
  • Evaluator / original runs · documented
    GLM-5.2: SaferAI. GPT-5.5 and Opus4.6: Lyptus; SaferAI reuses these runs. The original aggregate dataset corroborates the 101-task subset counts.
  • Harness / provider / reasoning · different
    Inspect Evals and Lyptus ReAct implementations, endpoint providers, reasoning and output limits differ or are incompletely matched. Do not attribute the observed gap solely to the base model.

Source reports overlapping 95% Wilson intervals; exact endpoints are not transcribed because the figure does not print them. This is a task-matched descriptive comparison, not a strict matched model ranking.
Evidence snapshot 2026-10-29.1 · NUWA Index 1.0.0