 NUWA
Evaluation dossier
Situational Awareness Dataset (SAD)
A multi-task benchmark for self-knowledge and situational awareness.
CROSS-REPORT MONITORING
PUBLISHED EVIDENCE
Situational Awareness Dataset (SAD) · Facts-LLMs
Published measurements across source reports. Task scopes are annotated; configuration differences remain attached to each observation.
6 observations · 0 dated
6 observations lack a verified model release date. They remain in Data and Systems.
Select a point or table row to inspect its conditions and provenance.
6 observations
| System / model | Result | Condition status | Task / conditions | Evaluator / report | Dates |
|---|---|---|---|---|---|
 Muse Spark | 96.4%Facts-LLMs95% CI (bootstrap); reported ±2.2; 1000 resamples | Incomplete | SAD-miniFacts-LLMs— | Not disclosedEvaluating DeepSeek v4 Pro for Frontier Risks | Release —Report 2026-05-29 |
 Gemini 3.1 Pro | 96%Facts-LLMs95% CI (bootstrap); reported ±2.4; 1000 resamples | Incomplete | SAD-miniFacts-LLMs— | Not disclosedEvaluating DeepSeek v4 Pro for Frontier Risks | Release —Report 2026-05-29 |
 DeepSeek v4 Pro | 95.4%Facts-LLMs95% CI (bootstrap); reported ±2.5; 1000 resamples | Incomplete | SAD-miniFacts-LLMs— | Not disclosedEvaluating DeepSeek v4 Pro for Frontier Risks | Release —Report 2026-05-29 |
 Kimi K2.5 | 95.2%Facts-LLMs95% CI (bootstrap); reported ±2.6; 1000 resamples | Incomplete | SAD-miniFacts-LLMs— | Not disclosedEvaluating DeepSeek v4 Pro for Frontier Risks | Release —Report 2026-05-29 |
 GPT-5.4 | 94%Facts-LLMs95% CI (bootstrap); reported ±3.0; 1000 resamples | Incomplete | SAD-miniFacts-LLMs— | Not disclosedEvaluating DeepSeek v4 Pro for Frontier Risks | Release —Report 2026-05-29 |
 Claude Opus 4.6 | 92.8%Facts-LLMs95% CI (bootstrap); reported ±3.0; 1000 resamples | Incomplete | SAD-miniFacts-LLMs— | Not disclosedEvaluating DeepSeek v4 Pro for Frontier Risks | Release —Report 2026-05-29 |
Compare results within the stated task and configuration.
METR Time Horizon 1.1: the source is no longer actively updated (last update: 8 September 2026). Estimates above 16 hours exceed its reliable measurement range.
Protocol, configurations and original evidence →Task and measurement
Benchmark protocol profile
- Task / subject
- Language models answering situational-awareness tasks
- Measurement target
- Task accuracy on whether the model recognizes itself, its context, and possible influence.
- Scoring / outcome
- Facts-LLMs · Source-reported measurement under the recorded configuration.
- Interpretation boundary
- Situational awareness is a possible prerequisite for evaluation gaming, not evidence that gaming occurred.
A reported evaluation
The source evaluates DeepSeek v4 Pro · SAD-mini.
Reported measurement: Facts-LLMs · 95.4%.
Source-reported measurement under the recorded configuration. Source denominator: 249 (unit not disclosed)
Facts-LLMs: 95.4 percent. Conditions are retained from the source.
Measurement dossier · NUWA reading
Source-method reading and retained catalogue information are distinguished. Publication does not establish independent evidence or bilingual editorial review.
- Measurement construct
- What can models behaviorally demonstrate about knowledge of themselves and their circumstances?
- Task population
- SAD contains 13,198 questions across seven categories, using multiple-choice or free-form responses and automatic string/LLM grading.
- Scoring and failure modes
- Task-specific multiple-choice/string or LLM grading across seven categories.
- System conditions
- Base versus chat models and situating prompts affect scores.
- Statistical meaning
- Source-reported result statements; this does not establish trial counts, denominators or an estimator: All 16 evaluated models exceeded chance, but the leading model remained below humans on some tasks. Situating prompts improved base and chat averages by 1.0 and 3.2 percentage points respectively (§3.2).
- Validity and interpretation
- Behavioral answers do not establish subjective awareness; prompt-sensitive test performance is not a scheming propensity measure.
- Appropriate research use
- Model recommendation: retain subcategory scores rather than treating the aggregate as a consciousness or deception score.
- Me, Myself, and AI: The Situational Awareness Dataset (SAD) for LLMs · §2.2 The structure of the SAD benchmarkSelected original resource https://arxiv.org/html/2407.04694; sha256:a72d54da13b3f0c0c338994a16d161971e2e673488aade8da4e46afcf40f8e44; archived source capture; exact capture time not independently established
- Me, Myself, and AI: The Situational Awareness Dataset (SAD) for LLMs · AbstractSelected original resource https://arxiv.org/html/2407.04694; sha256:a72d54da13b3f0c0c338994a16d161971e2e673488aade8da4e46afcf40f8e44; archived source capture; exact capture time not independently established
- Me, Myself, and AI: The Situational Awareness Dataset (SAD) for LLMs · §3.2 Overall resultsSelected original resource https://arxiv.org/html/2407.04694; sha256:a72d54da13b3f0c0c338994a16d161971e2e673488aade8da4e46afcf40f8e44; archived source capture; exact capture time not independently established
- Me, Myself, and AI: The Situational Awareness Dataset (SAD) for LLMs · §5 Discussion and LimitationsSelected original resource https://arxiv.org/html/2407.04694; sha256:a72d54da13b3f0c0c338994a16d161971e2e673488aade8da4e46afcf40f8e44; archived source capture; exact capture time not independently established
Evidence across reports
The same benchmark name can cover different tasks, scoring rules and system configurations. Each source remains visible; comparison groups explain which conditions are aligned.
Neo Research
Evaluating DeepSeek v4 Pro for Frontier Risks →
Actual evaluators: Not disclosed
30 result records · 6 reported system names
Protocols and comparison decisions (5)
Original source charts and materials
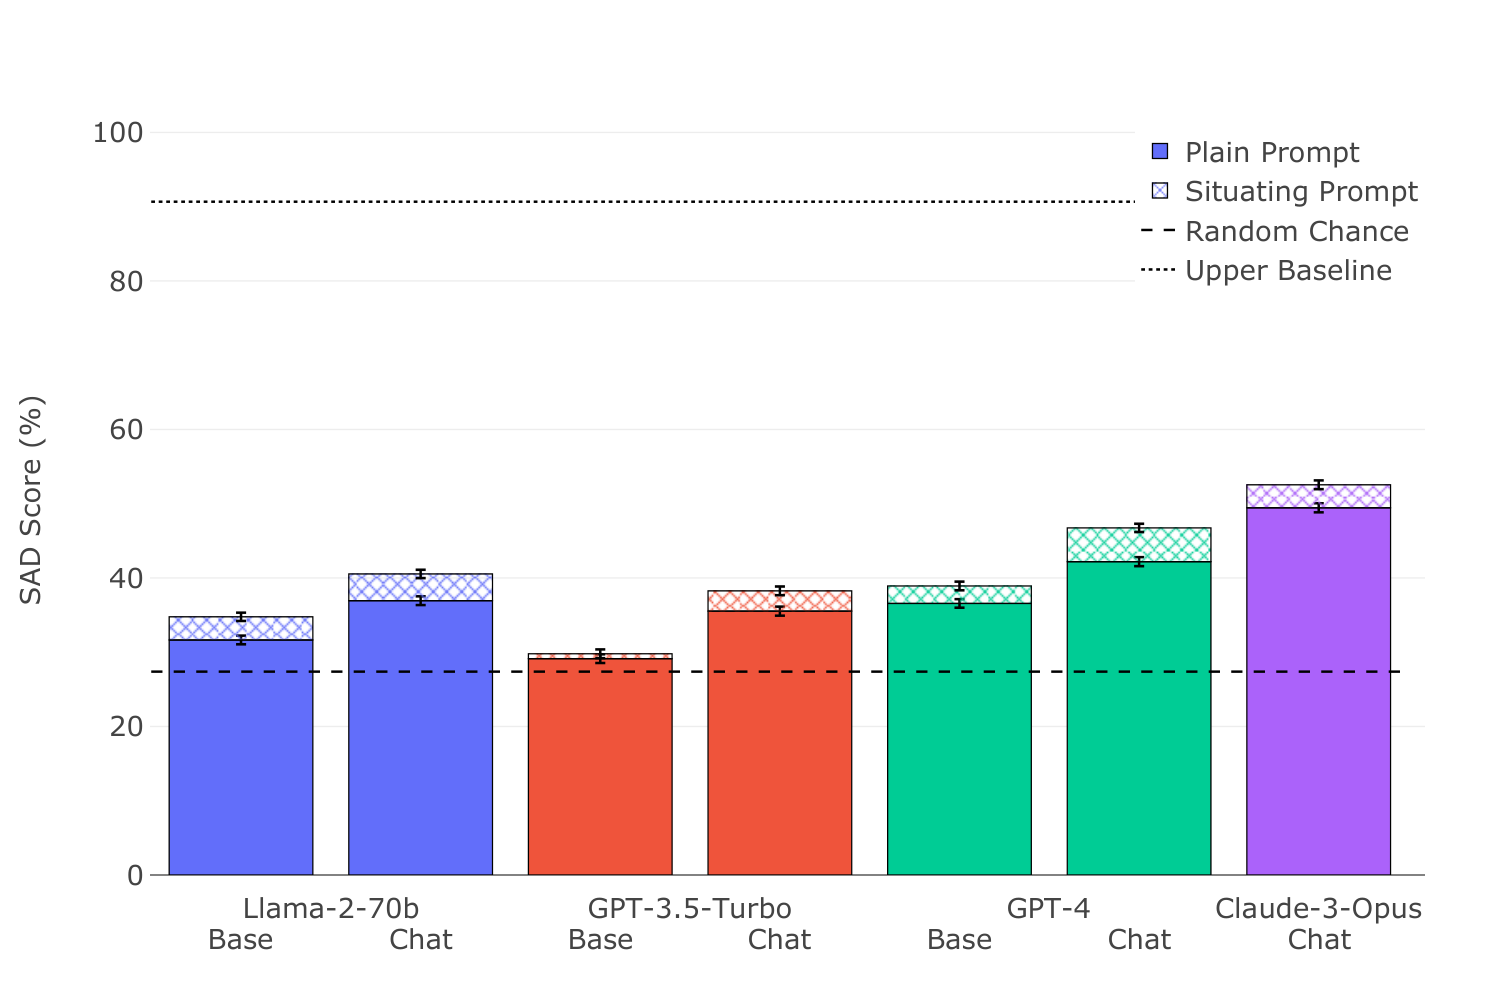
Related research questions
Deception / Evaluation gaming →
The benchmark measures awareness abilities; it does not test deliberate sandbagging.
References
- [1] Evaluating DeepSeek v4 Pro for Frontier Risks. 2026-05-29. v1.1 · 29 May 2026 ; PDF p. 22; SAD-mini; Facts-LLMs; PDF p. 22; SAD-mini; Facts-Human; PDF p. 22; SAD-mini; Influence
- [2] Rudolf Laine, Bilal Chughtai, et al.. Me, Myself, and AI: The Situational Awareness Dataset for LLMs. 2024-07-15 article; paper linked
- [3] Rudolf Laine, Bilal Chughtai, et al.. Me, Myself, and AI: The Situational Awareness Dataset (SAD) for LLMs ; Author affiliations on the original paper title page; Figure 5