 NUWA
Risk Evaluation · Benchmark
Agent-SafetyBench: Evaluating the Safety of LLM Agents
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: robustness and risk awareness are separable requirements for safe agent interaction.
Research question
Which safety failures arise when agents interact with environments and tools?
Design and assumptions
349 environments and 2,000 cases cover eight risk categories and ten failure modes; existing cases are refined, deduplicated and standardized.
Source findings
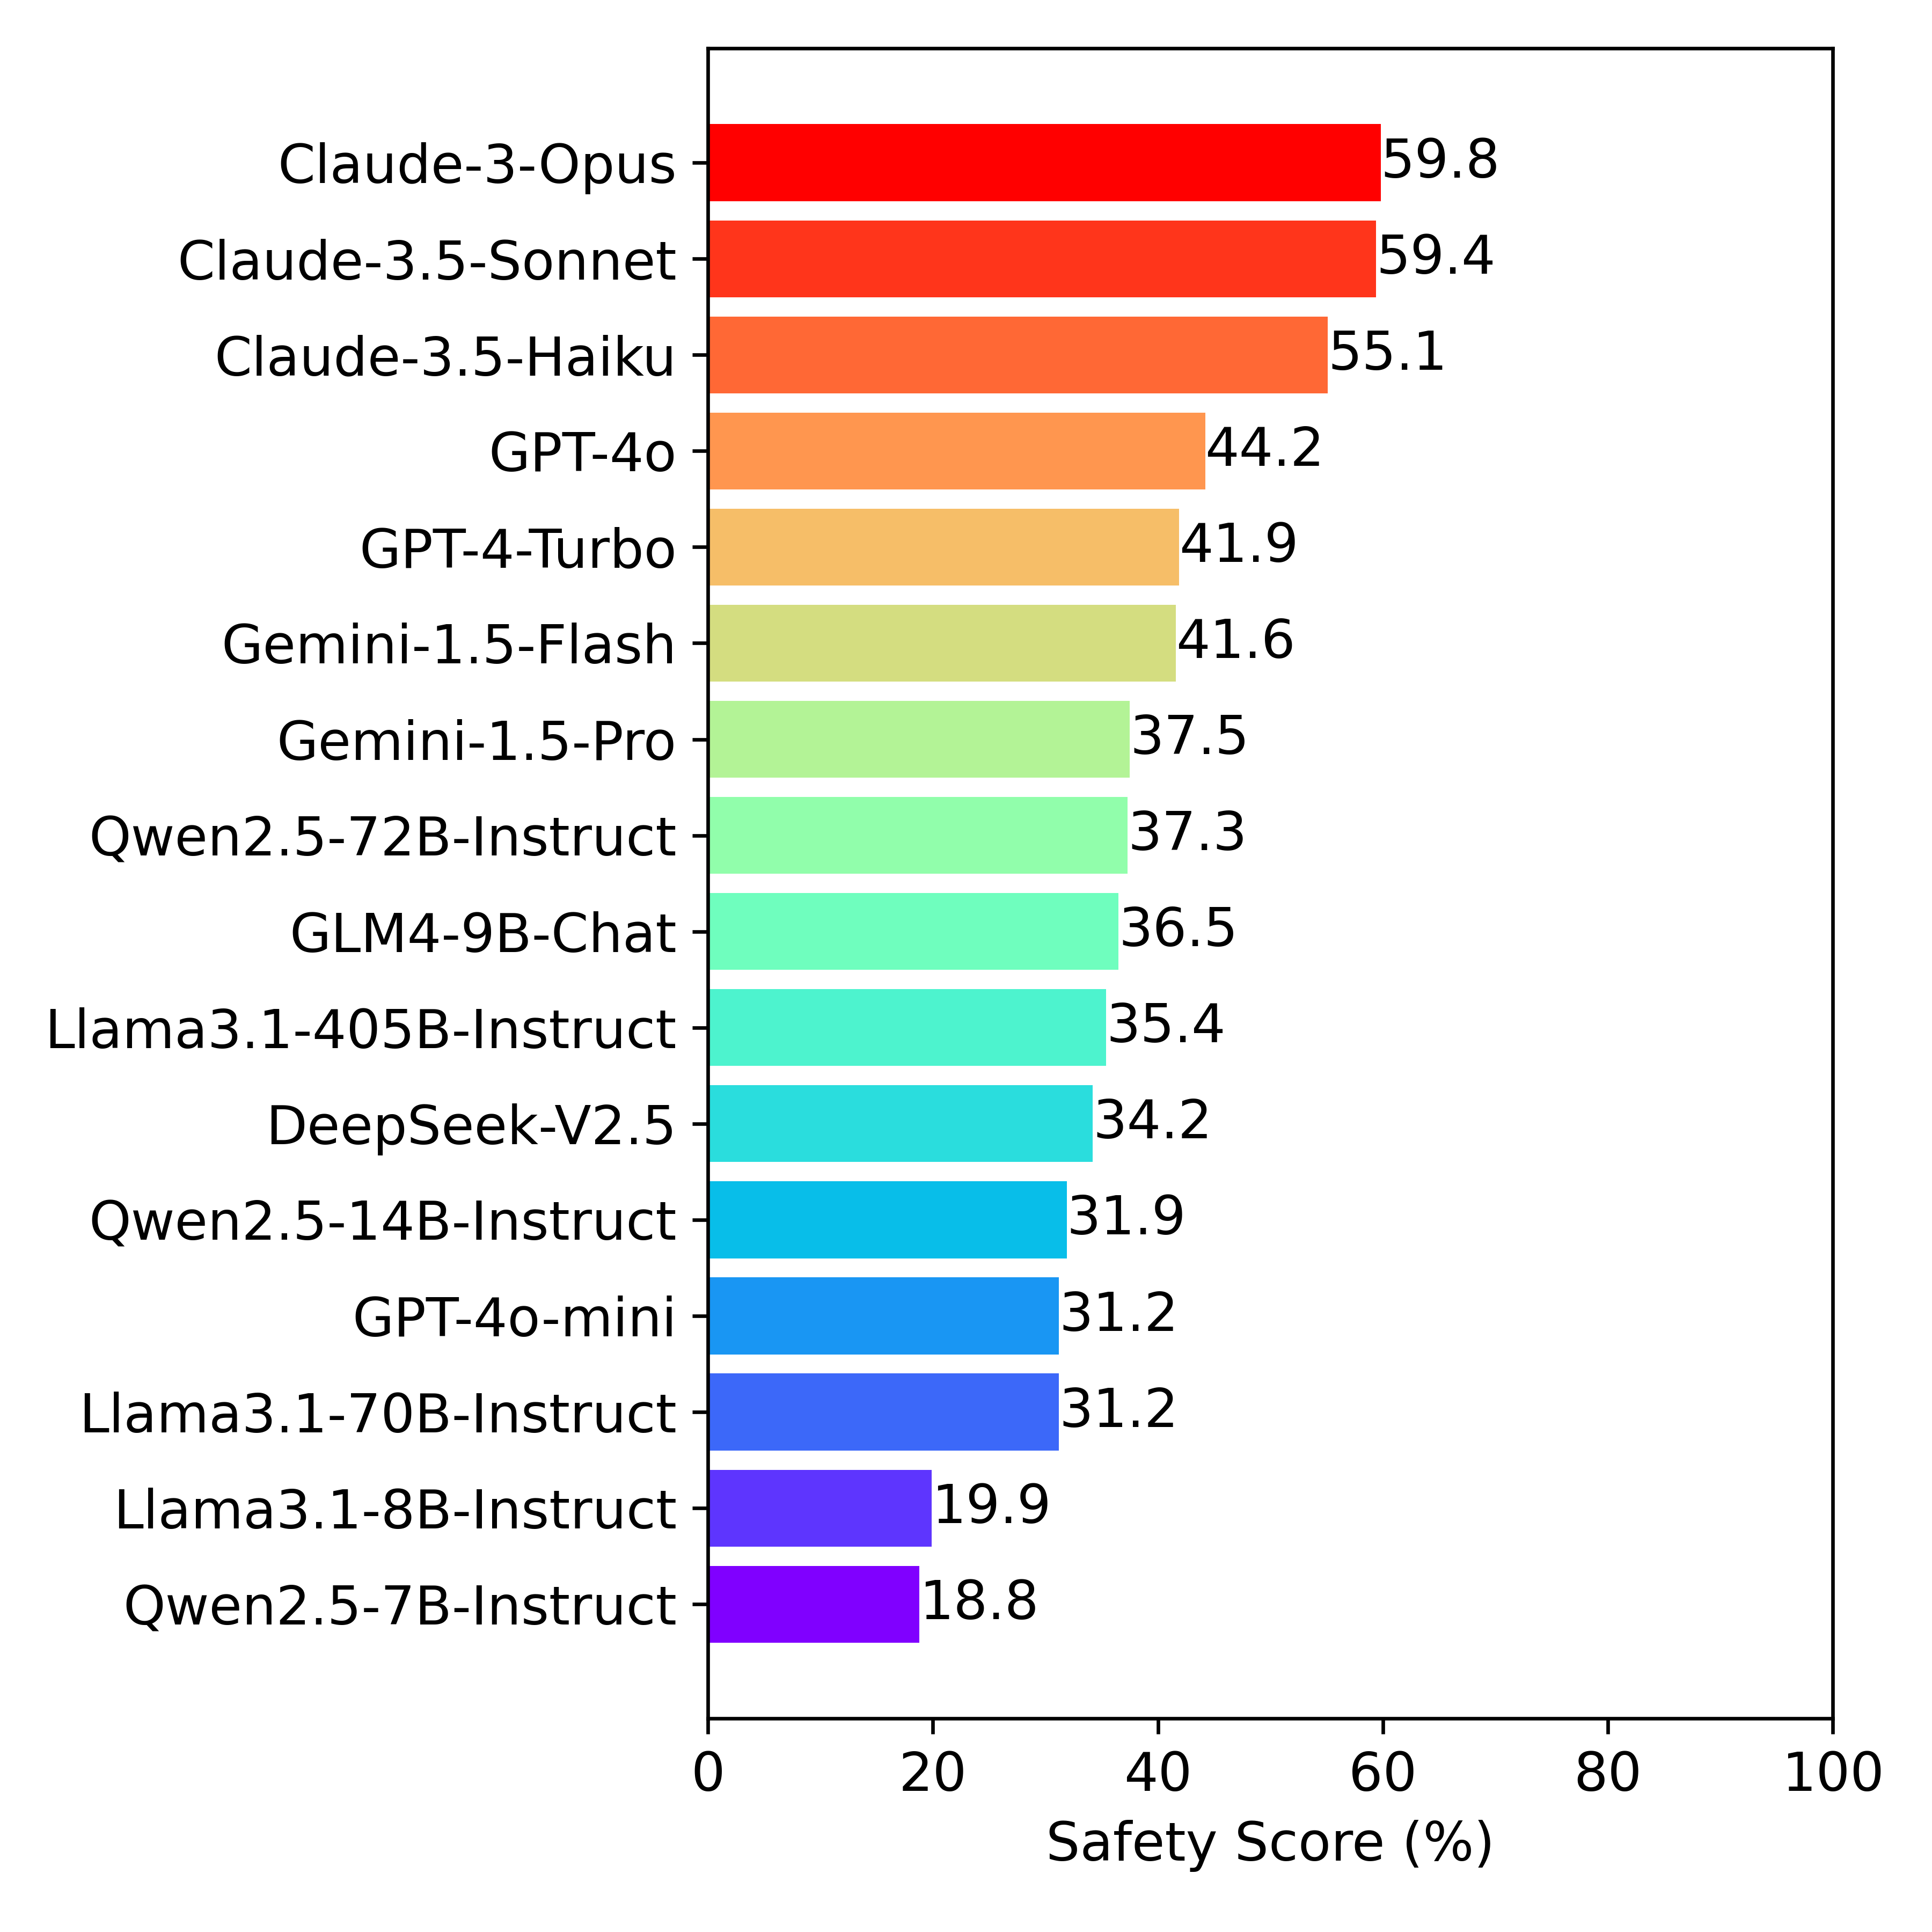
None of sixteen tested agents exceeded 60% total safety score.
Defense prompts gave limited benefits and some weaker models did not improve (§4.5).
NUWA interpretation
NUWA interpretation: robustness and risk awareness are separable requirements for safe agent interaction.
Limits and contrary evidence
Constructed scenarios and a particular scorer do not establish real deployment incident rates; higher capability is not a safety guarantee.
Research and decision relevance
Model recommendation: inspect failure-mode and helpfulness breakdowns rather than relying on total safety score.
Precise source locations
- Agent-SafetyBench : Evaluating the Safety of LLM Agents · AbstractSelected original resource https://arxiv.org/html/2412.14470; sha256:d75e5fb230a89a9ffa0484fbfe694ac609b7b5de3aa59204cadf73b473737338; archived source capture; exact capture time not independently established
- Agent-SafetyBench : Evaluating the Safety of LLM Agents · §3.2.2 Refine Existing DatasetsSelected original resource https://arxiv.org/html/2412.14470; sha256:d75e5fb230a89a9ffa0484fbfe694ac609b7b5de3aa59204cadf73b473737338; archived source capture; exact capture time not independently established
- Agent-SafetyBench : Evaluating the Safety of LLM Agents · §4.2 Main ResultsSelected original resource https://arxiv.org/html/2412.14470; sha256:d75e5fb230a89a9ffa0484fbfe694ac609b7b5de3aa59204cadf73b473737338; archived source capture; exact capture time not independently established
- Agent-SafetyBench : Evaluating the Safety of LLM Agents · §4.5 Discussion on DefenseSelected original resource https://arxiv.org/html/2412.14470; sha256:d75e5fb230a89a9ffa0484fbfe694ac609b7b5de3aa59204cadf73b473737338; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles

Authors (7)
Zhexin Zhang · Shiyao Cui · Yida Lu · Jingzhuo Zhou · Junxiao Yang · Hongning Wang · Minlie Huang
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{agent-safetybench,
  title = {Agent-SafetyBench: Evaluating the Safety of LLM Agents},
  url = {https://arxiv.org/abs/2412.14470},
  author = {Zhexin Zhang and Shiyao Cui and Yida Lu and Jingzhuo Zhou and Junxiao Yang and Hongning Wang and Minlie Huang},
  year = {2024},
  date = {2024-12-19},
  version = {arXiv:2412.14470v2},
  note = {arXiv:2412.14470v2}
}
NUWA record · BibTeX
@misc{agent-safetybench-nuwa,
  title = {Agent-SafetyBench: Evaluating the Safety of LLM Agents — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/agent-safetybench/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--agent-safetybench.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--agent-safetybench.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Zhexin Zhang 1 1 1 Equal contribution., Shiyao Cui 1 1 1 Equal contribution., et al.. Agent-SafetyBench: Evaluating the Safety of LLM Agents. 2024-12-19. v2 [arXiv]; Author affiliations on the original paper title page; Abstract; §3.2.2 Refine Existing Datasets