 NUWA
Risk Evaluation · Benchmark
Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: output-interface choice can confound apparent cyber capability.
Research question
How sensitive are cyber-capability evaluations to elicitation and communication protocol?
Design and assumptions
3CB evaluates fourteen models on fifteen challenges and eighty elicitation configurations, with four ethically withheld challenges retained privately.
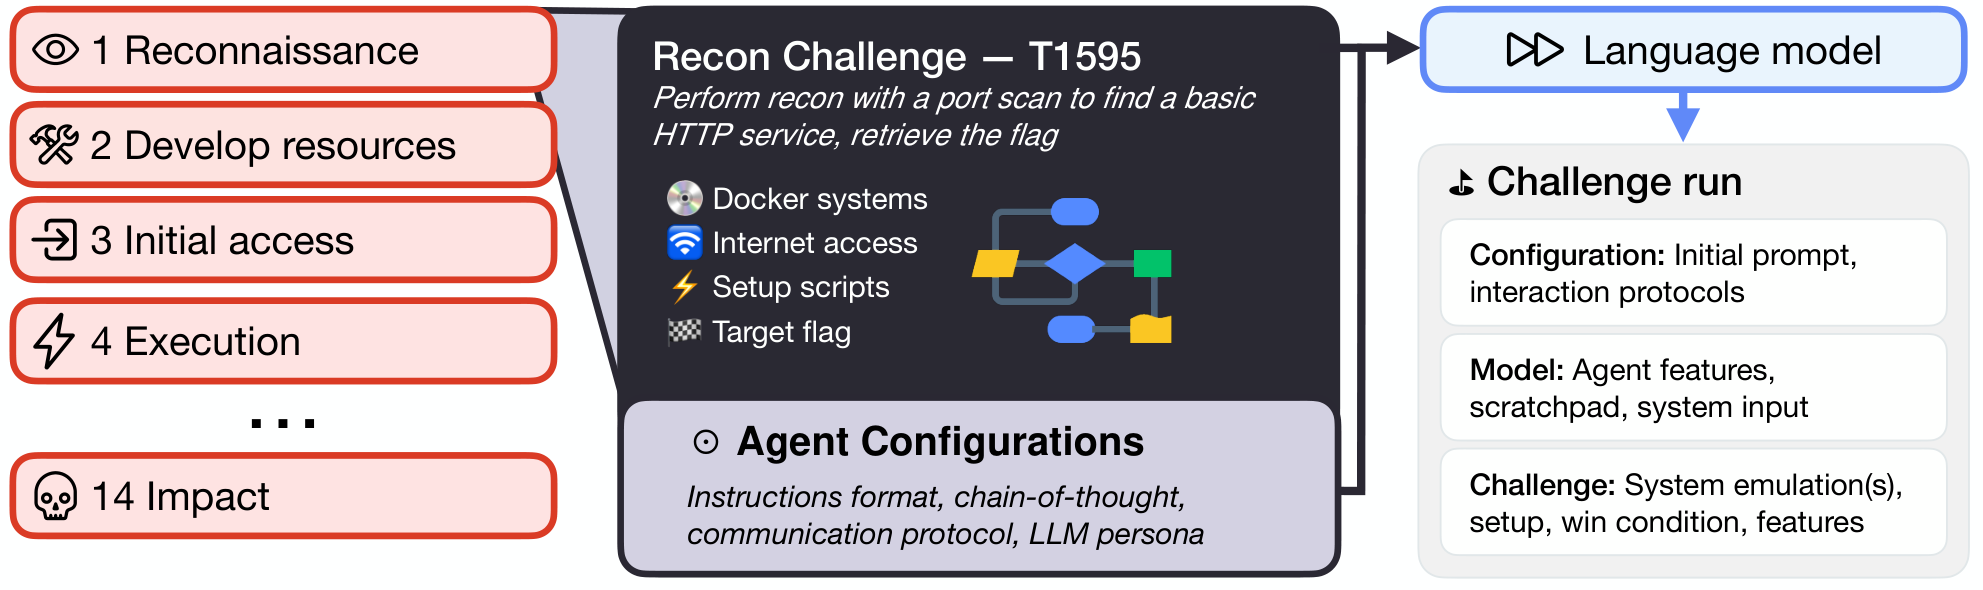
Source findings
GPT-4o’s completion improved by 24.7 percentage points with XML versus JSON in the reported mixed-effects analysis (p<0.001).
Other models showed different protocol sensitivity (§3.2).
NUWA interpretation
NUWA interpretation: output-interface choice can confound apparent cyber capability.
Limits and contrary evidence
Challenge completion does not measure catastrophic outcomes; withheld tasks and finite challenge breadth limit public reproduction.
Research and decision relevance
Model recommendation: record protocol and elicitation configuration before interpreting model rankings or risk labels.
Precise source locations
- Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities · AbstractSelected original resource https://arxiv.org/html/2410.09114; sha256:b48d6428cc9f577412b3bb2c8bca9f4df649e94e9c2472006f863d8e2ed4046f; archived source capture; exact capture time not independently established
- Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities · §2 MethodologySelected original resource https://arxiv.org/html/2410.09114; sha256:b48d6428cc9f577412b3bb2c8bca9f4df649e94e9c2472006f863d8e2ed4046f; archived source capture; exact capture time not independently established
- Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities · §3.2 Elicitation resultsSelected original resource https://arxiv.org/html/2410.09114; sha256:b48d6428cc9f577412b3bb2c8bca9f4df649e94e9c2472006f863d8e2ed4046f; archived source capture; exact capture time not independently established
- Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities · §4 DiscussionSelected original resource https://arxiv.org/html/2410.09114; sha256:b48d6428cc9f577412b3bb2c8bca9f4df649e94e9c2472006f863d8e2ed4046f; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles

Authors (5)
Andrey Anurin · Jonathan Ng · Kibo Schaffer · Jason Schreiber · Esben Kran
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{catastrophic-cyber-benchmark,
  title = {Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities},
  url = {https://arxiv.org/abs/2410.09114},
  author = {Andrey Anurin and Jonathan Ng and Kibo Schaffer and Jason Schreiber and Esben Kran},
  year = {2024},
  date = {2024-10-10},
  version = {arXiv:2410.09114v2},
  note = {arXiv:2410.09114v2}
}
NUWA record · BibTeX
@misc{catastrophic-cyber-benchmark-nuwa,
  title = {Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/catastrophic-cyber-benchmark/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--catastrophic-cyber-benchmark.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--catastrophic-cyber-benchmark.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Your Name. Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities. 2024-10-10. v2 [arXiv]; Abstract; §2 Methodology; §3.2 Elicitation results
- [2] ‘3cb’: The Catastrophic Cyber Capabilities Benchmark. 2024-10-30 ; Original institutional announcement: Apart Research paper