 NUWA
Risk Evaluation · Benchmark
CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis and Threat Intelligence Reasoning
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: defensive reasoning evidence is distinct from autonomous offensive success.
Research question
Can models support core defensive security-operations reasoning tasks?
Design and assumptions
Two components test malware analysis and threat-intelligence reasoning; models use original weights with limited response-format prompt adjustments.
Source findings
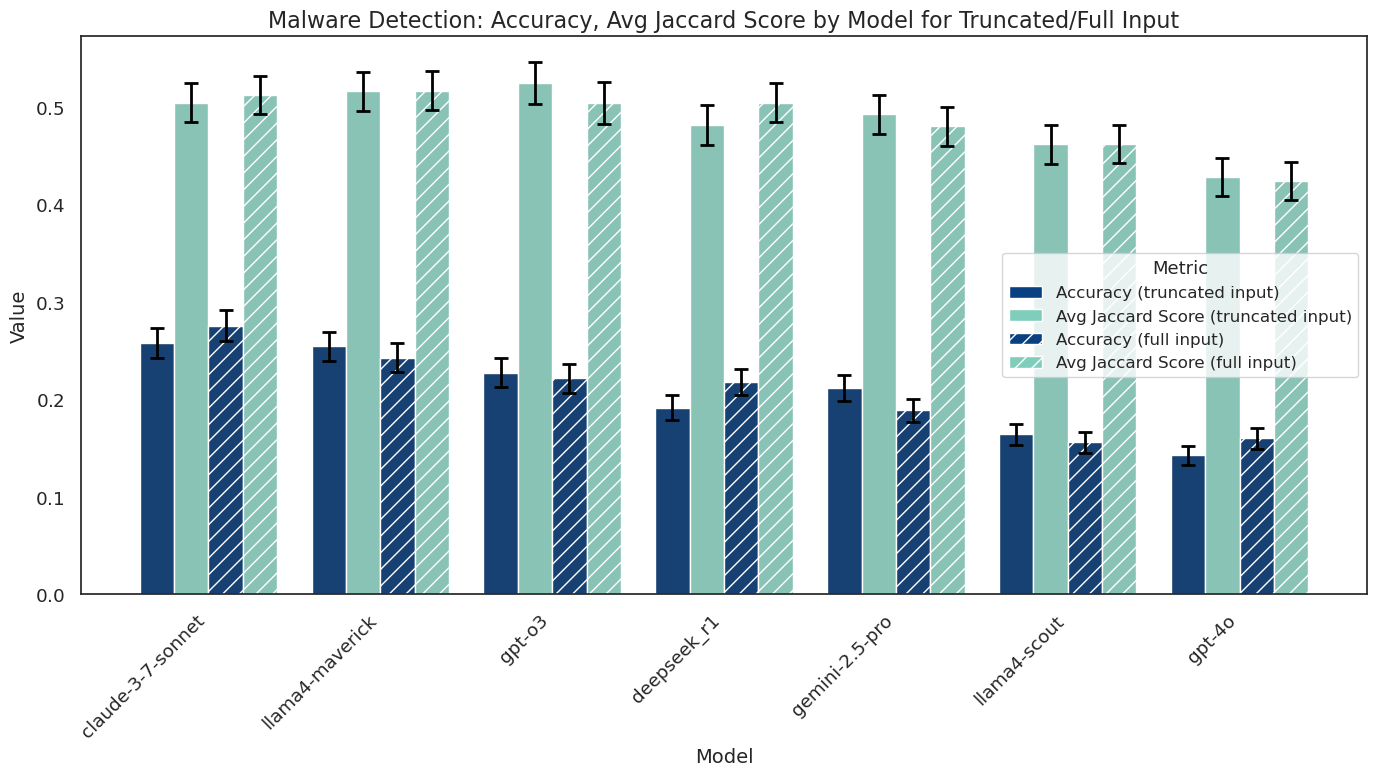
The suite explicitly measures two selected manual SOC task families.
Per-model formatting adjustments were needed when responses were otherwise unparseable (§4).
NUWA interpretation
NUWA interpretation: defensive reasoning evidence is distinct from autonomous offensive success.
Limits and contrary evidence
Two task families do not establish end-to-end SOC automation or analyst productivity; prompt-format adjustments complicate pure model attribution.
Research and decision relevance
Model recommendation: keep component scores, parsing treatment and prompt adjustments visible.
Precise source locations
- CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis and Threat Intelligence Reasoning · §3 BenchmarksSelected original resource https://arxiv.org/html/2509.20166v1; sha256:854341e9f3b6343a27d71f3c8e6c91ad3f712587d0282af67a52f65193a81aad; archived source capture; exact capture time not independently established
- CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis and Threat Intelligence Reasoning · §4 Experimental Setup and ResultsSelected original resource https://arxiv.org/html/2509.20166v1; sha256:854341e9f3b6343a27d71f3c8e6c91ad3f712587d0282af67a52f65193a81aad; archived source capture; exact capture time not independently established
- CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis and Threat Intelligence Reasoning · §5.4 Additional LimitationsSelected original resource https://arxiv.org/html/2509.20166v1; sha256:854341e9f3b6343a27d71f3c8e6c91ad3f712587d0282af67a52f65193a81aad; archived source capture; exact capture time not independently established
- CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis and Threat Intelligence Reasoning · §3.1 Malware Analysis Benchmark: Test case structure and metricsSelected original resource https://arxiv.org/html/2509.20166v1; sha256:854341e9f3b6343a27d71f3c8e6c91ad3f712587d0282af67a52f65193a81aad; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles


Authors (23)
Lauren Deason · Adam Bali · Ciprian Bejean · Diana Bolocan · James Crnkovich · Ioana Croitoru · Krishna Durai · Chase Midler · Calin Miron · David Molnar · Brad Moon · Bruno Ostarcevic · Alberto Peltea · Matt Rosenberg · Catalin Sandu · Arthur Saputkin · Sagar Shah · Daniel Stan · Ernest Szocs · Shengye Wan · Spencer Whitman · Sven Krasser · Joshua Saxe
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{cybersoceval,
  title = {CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis and Threat Intelligence Reasoning},
  url = {https://arxiv.org/html/2509.20166v1},
  author = {Lauren Deason and Adam Bali and Ciprian Bejean and Diana Bolocan and James Crnkovich and Ioana Croitoru and Krishna Durai and Chase Midler and Calin Miron and David Molnar and Brad Moon and Bruno Ostarcevic and Alberto Peltea and Matt Rosenberg and Catalin Sandu and Arthur Saputkin and Sagar Shah and Daniel Stan and Ernest Szocs and Shengye Wan and Spencer Whitman and Sven Krasser and Joshua Saxe},
  version = {arXiv:2509.20166v1},
  note = {arXiv:2509.20166v1}
}
NUWA record · BibTeX
@misc{cybersoceval-nuwa,
  title = {CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis and Threat Intelligence Reasoning — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/cybersoceval/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--cybersoceval.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--cybersoceval.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Lauren Deason, Adam Bali, et al.. CyberSOCEval: Benchmarking LLMs Capabilities for Malware Analysis and Threat Intelligence Reasoning. v1 ; §3 Benchmarks; §4 Experimental Setup and Results; §5.4 Additional Limitations
- [2] CyberSOCEval Benchmark Data ; Original project README: joint project between CrowdStrike and Meta