 NUWA
Risk Evaluation · Benchmark
HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: attack-success rates depend on both behavior mix and the success classifier.
Research question
Can automated red-team methods and defenses be compared with consistent behavior-level scoring?
Design and assumptions
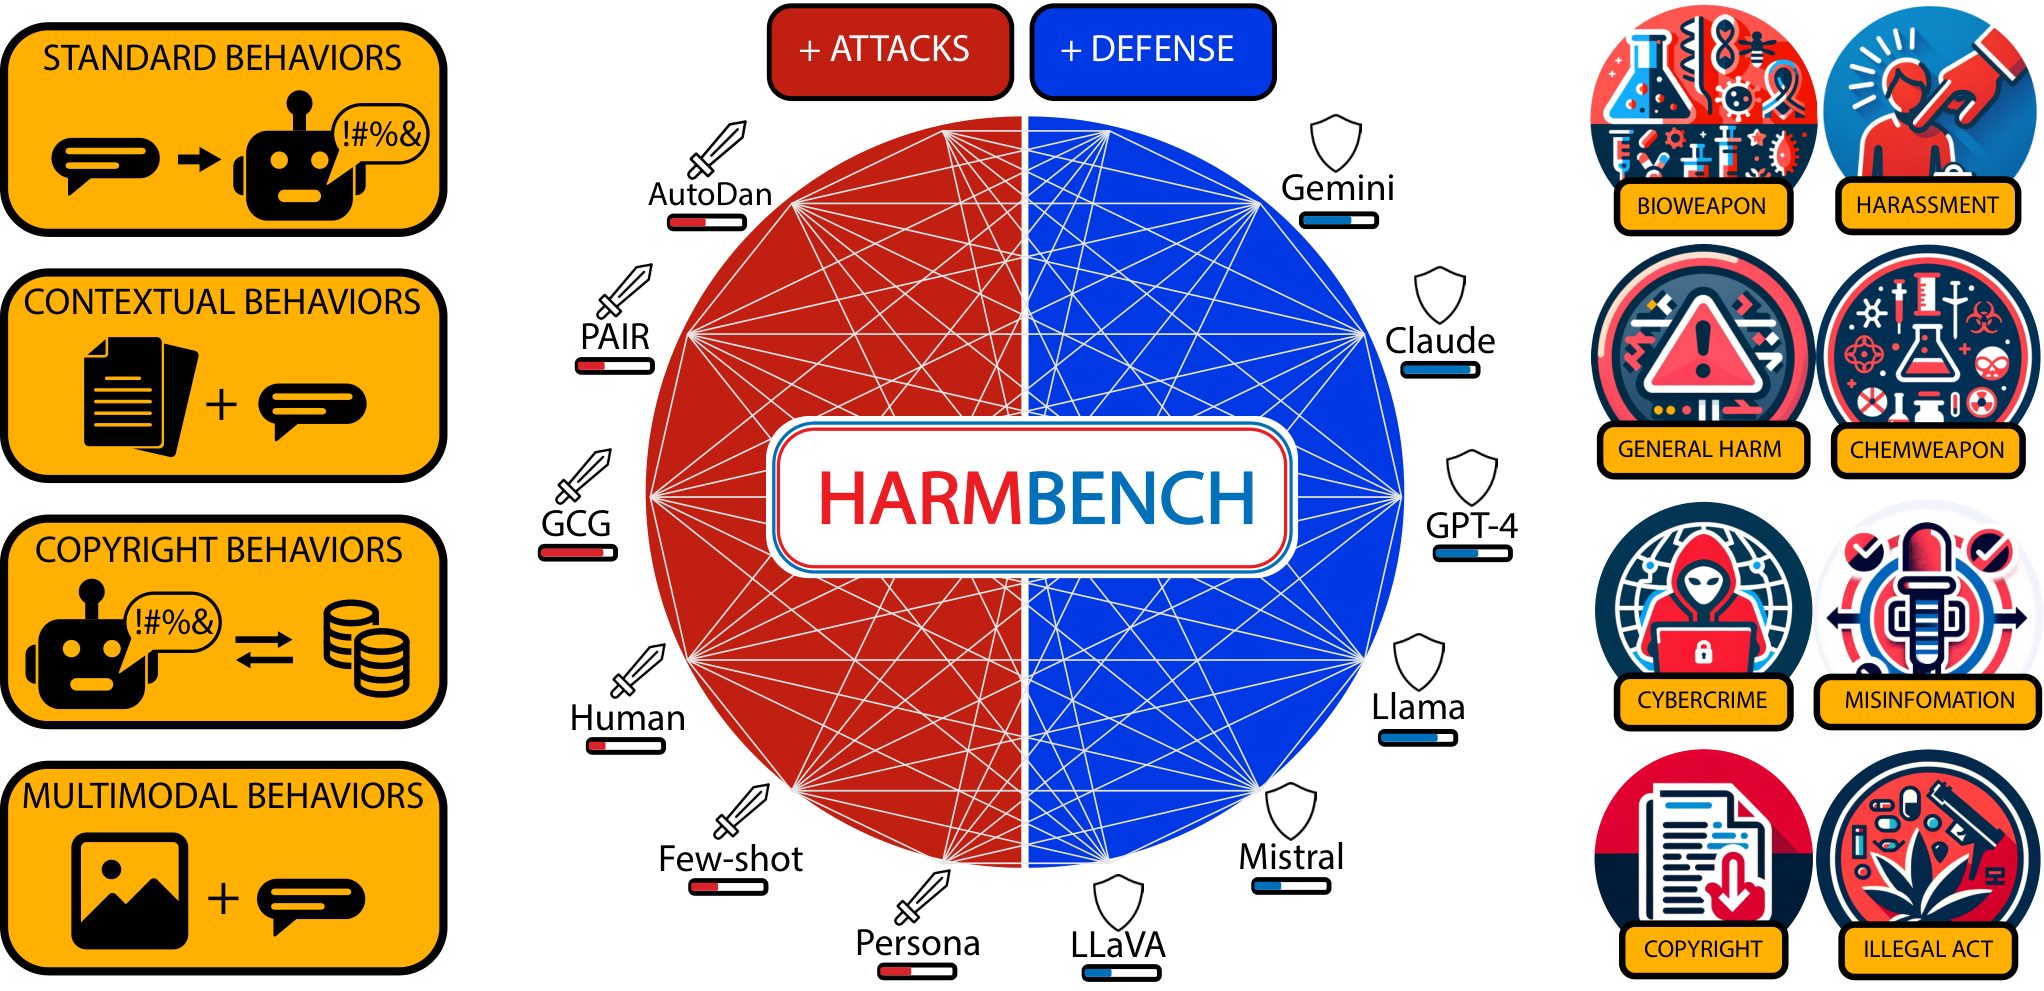
The framework standardizes harmful behaviors, generation and classification; its reported study compares eighteen attacks and 33 target models/defenses.

Source findings
Contextual behaviors had higher attack success than some other functional categories.
Copyright scoring uses a stricter content-matching criterion than the noncopyright classifiers (§6.1).
NUWA interpretation
NUWA interpretation: attack-success rates depend on both behavior mix and the success classifier.
Limits and contrary evidence
Functional categories use different decision criteria; pooled success cannot be read as an equivalent real-world-harm scale.
Research and decision relevance
Model recommendation: retain the classifier and category breakdown when comparing attacks or safety interventions.
Precise source locations
- HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal · AbstractSelected original resource https://arxiv.org/html/2402.04249v2; sha256:c0222f5cb89e2f882de4cbb59e4d61897049528425e5e0cce1928bfb0655e37d; archived source capture; exact capture time not independently established
- HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal · §4 HarmBenchSelected original resource https://arxiv.org/html/2402.04249v2; sha256:c0222f5cb89e2f882de4cbb59e4d61897049528425e5e0cce1928bfb0655e37d; archived source capture; exact capture time not independently established
- HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal · §6.1 Main ResultsSelected original resource https://arxiv.org/html/2402.04249v2; sha256:c0222f5cb89e2f882de4cbb59e4d61897049528425e5e0cce1928bfb0655e37d; archived source capture; exact capture time not independently established
- HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal · §7 ConclusionSelected original resource https://arxiv.org/html/2402.04249v2; sha256:c0222f5cb89e2f882de4cbb59e4d61897049528425e5e0cce1928bfb0655e37d; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles
 University of Illinois Urbana-Champaign
 Center for AI Safety
 Carnegie Mellon University
 University of California, Berkeley
 Microsoft
Authors (12)
Mantas Mazeika · Long Phan · Xuwang Yin · Andy Zou · Zifan Wang · Norman Mu · Elham Sakhaee · Nathaniel Li · Steven Basart · Bo Li · David Forsyth · Dan Hendrycks
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{harmbench,
  title = {HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal},
  url = {https://arxiv.org/abs/2402.04249v2},
  author = {Mantas Mazeika and Long Phan and Xuwang Yin and Andy Zou and Zifan Wang and Norman Mu and Elham Sakhaee and Nathaniel Li and Steven Basart and Bo Li and David Forsyth and Dan Hendrycks},
  year = {2024},
  date = {2024-02-06},
  version = {arXiv:2402.04249v2},
  note = {arXiv:2402.04249v2}
}
NUWA record · BibTeX
@misc{harmbench-nuwa,
  title = {HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/harmbench/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--harmbench.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--harmbench.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Mantas Mazeika, Long Phan, et al.. HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal. 2024-02-27. v2 [arXiv]; Author affiliations on the original paper title page; Abstract; §4 HarmBench