 NUWA
Risk Evaluation · Benchmark
LABBench2: An Improved Benchmark for AI Systems Performing Biology Research
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: changing realism can reveal gaps hidden by improving scores on older task formats.
Research question
Can scientific capability tests better approximate useful research work than multiple-choice knowledge questions?
Design and assumptions
LABBench2 contains over 1,900 tasks across research-support skills, comparing models with and without tools in more realistic contexts.
Source findings
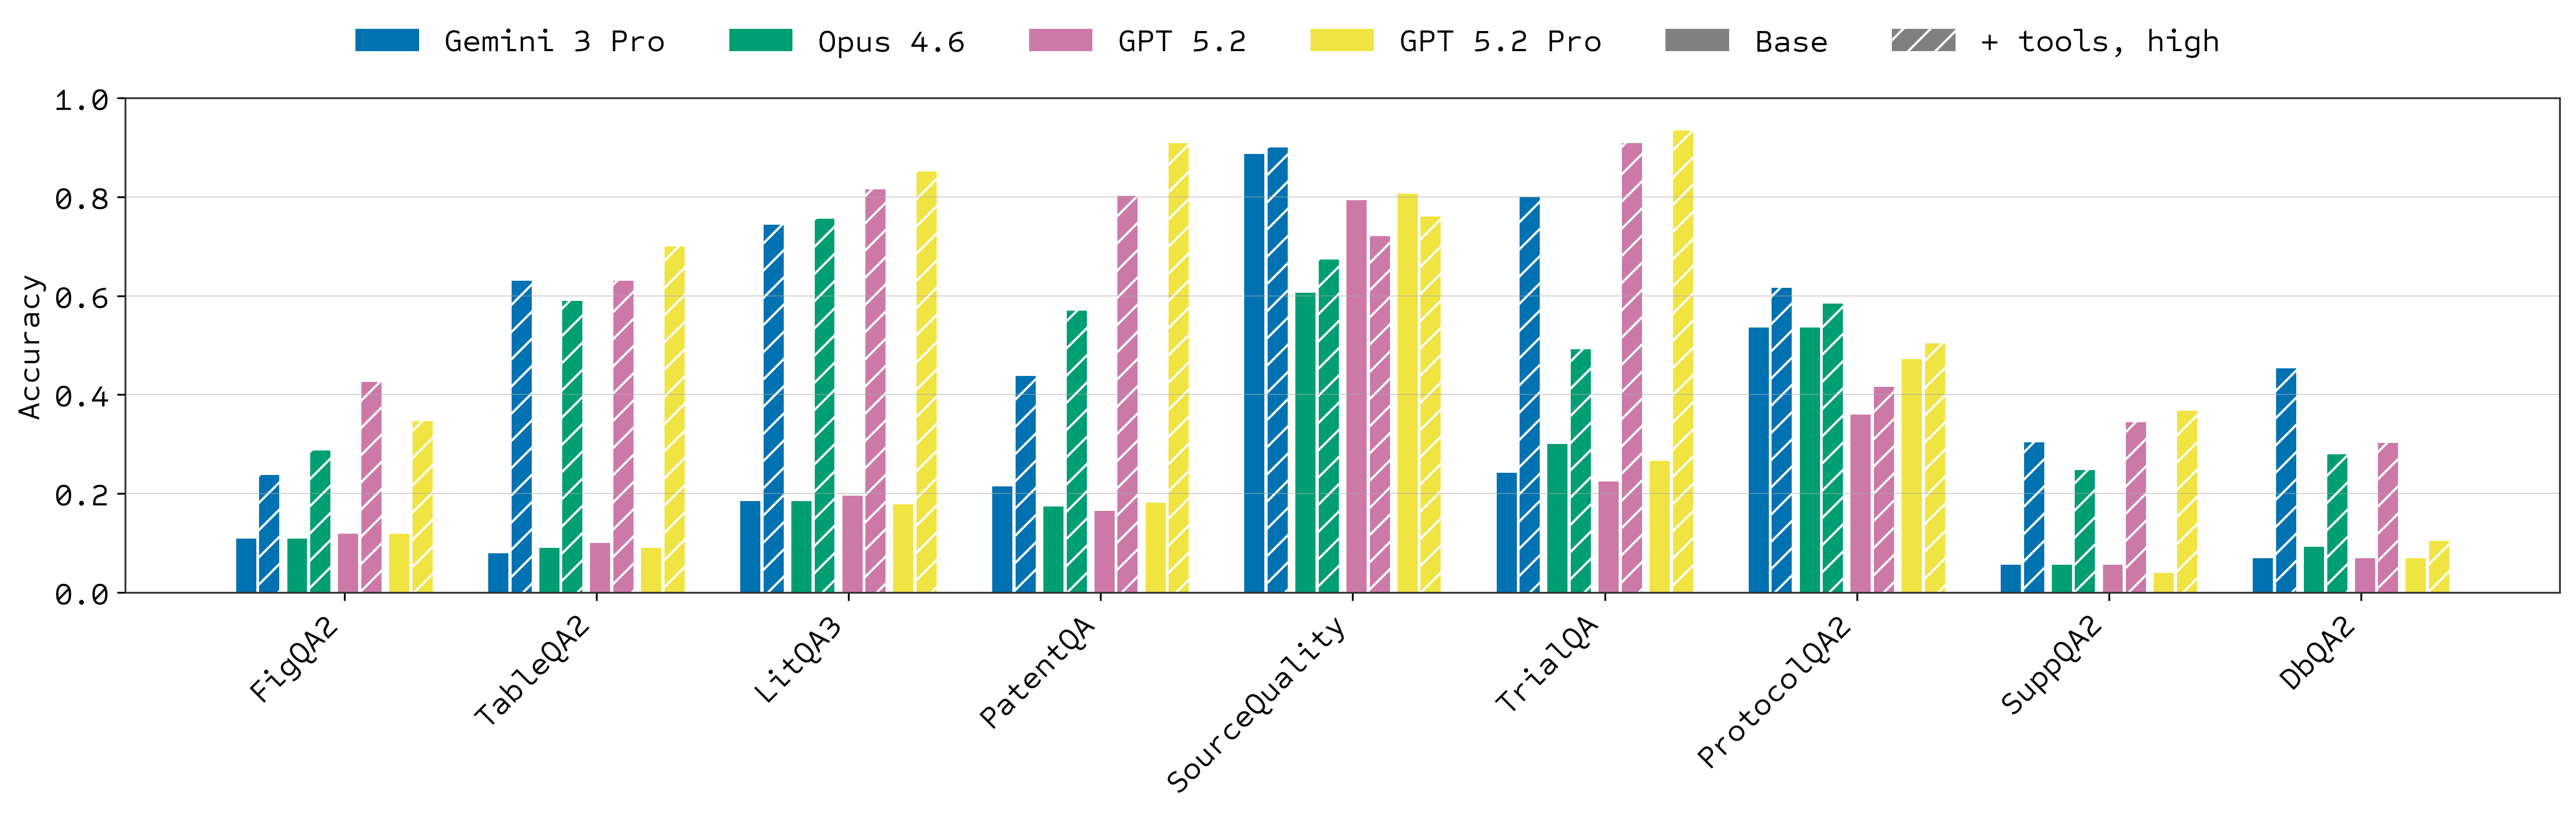
The authors report model-specific subtask accuracy differences of −26% to −46% relative to the earlier benchmark.
Tool augmentation helps variably rather than uniformly (§3).
NUWA interpretation
NUWA interpretation: changing realism can reveal gaps hidden by improving scores on older task formats.
Limits and contrary evidence
Wet-lab execution, ambiguous goals and days-long iteration remain simplified; verifier reliability and biological breadth are limited (§4.3).
Research and decision relevance
Model recommendation: use version- and tool-specific results; do not infer operational biological uplift from these scores.
Precise source locations
- LABBench2 An Improved Benchmark for AI Systems Performing Biology Research · AbstractSelected original resource https://arxiv.org/html/2604.09554; sha256:333fb7f67888029041cb7ff7df47ada35844806b30ea09197b5258442e65aa72; archived source capture; exact capture time not independently established
- LABBench2 An Improved Benchmark for AI Systems Performing Biology Research · §3 ResultsSelected original resource https://arxiv.org/html/2604.09554; sha256:333fb7f67888029041cb7ff7df47ada35844806b30ea09197b5258442e65aa72; archived source capture; exact capture time not independently established
- LABBench2 An Improved Benchmark for AI Systems Performing Biology Research · §4.3 Limitations and future workSelected original resource https://arxiv.org/html/2604.09554; sha256:333fb7f67888029041cb7ff7df47ada35844806b30ea09197b5258442e65aa72; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles

Authors (12)
Jon M Laurent · Albert Bou · Michael Pieler · Conor Igoe · Alex Andonian · Siddharth Narayanan · James Braza · Alexandros Sanchez Vassopoulos · Jacob L Steenwyk · Blake Lash · Andrew D White · Samuel G Rodriques
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{labbench-two,
  title = {LABBench2: An Improved Benchmark for AI Systems Performing Biology Research},
  url = {https://arxiv.org/abs/2604.09554},
  author = {Jon M Laurent and Albert Bou and Michael Pieler and Conor Igoe and Alex Andonian and Siddharth Narayanan and James Braza and Alexandros Sanchez Vassopoulos and Jacob L Steenwyk and Blake Lash and Andrew D White and Samuel G Rodriques},
  year = {2026},
  date = {2026-02-04},
  version = {arXiv:2604.09554v2},
  note = {arXiv:2604.09554v2}
}
NUWA record · BibTeX
@misc{labbench-two-nuwa,
  title = {LABBench2: An Improved Benchmark for AI Systems Performing Biology Research — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/labbench-two/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--labbench-two.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--labbench-two.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Jon M Laurent, Albert Bou, et al.. LABBench2: An Improved Benchmark for AI Systems Performing Biology Research. 2026-02-04. v2 [arXiv]; Author affiliations on the original paper title page; Abstract; §3 Results