 NUWA
Risk Evaluation · Benchmark
RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: the human–agent ordering depends on time allocation and selection, not a single general research ranking.
Research question
How do agents compare with experts on open-ended ML research engineering?
Design and assumptions
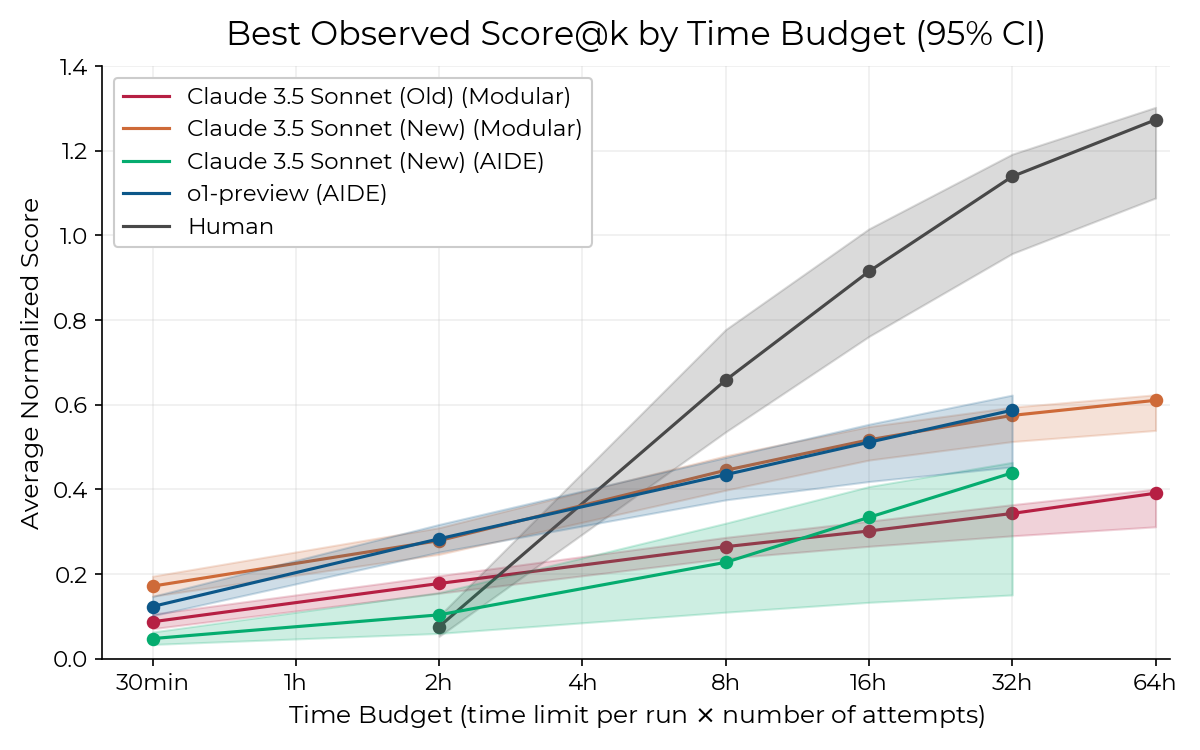
Seven environments include 71 eight-hour attempts by 61 distinct experts; agent comparisons vary total time, scaffold and best-of-k selection.
Source findings
82% of expert attempts earned nonzero scores; 24% matched or exceeded reference solutions.
Agents led at two hours, but humans achieved about twice the top-agent score at 32 aggregate hours in the reported setup.
NUWA interpretation
NUWA interpretation: the human–agent ordering depends on time allocation and selection, not a single general research ranking.
Limits and contrary evidence
Seven environments do not span frontier R&D; limited scaffold iteration could understate agent capability (§6.3).
Research and decision relevance
Model recommendation: cite normalized score, scaffold, total time and attempt aggregation together.
Precise source locations
- RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts · AbstractSelected original resource https://arxiv.org/html/2411.15114v2; sha256:4a4df1346307f7b31e65c6c0e8b5533d0a6649904ea600d5b0d4d893a5d64c58; archived source capture; exact capture time not independently established
- RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts · §3.1 Design goalsSelected original resource https://arxiv.org/html/2411.15114v2; sha256:4a4df1346307f7b31e65c6c0e8b5533d0a6649904ea600d5b0d4d893a5d64c58; archived source capture; exact capture time not independently established
- RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts · §4 Experiments and resultsSelected original resource https://arxiv.org/html/2411.15114v2; sha256:4a4df1346307f7b31e65c6c0e8b5533d0a6649904ea600d5b0d4d893a5d64c58; archived source capture; exact capture time not independently established
- RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts · §6.3 Other LimitationsSelected original resource https://arxiv.org/html/2411.15114v2; sha256:4a4df1346307f7b31e65c6c0e8b5533d0a6649904ea600d5b0d4d893a5d64c58; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles





Authors (23)
Hjalmar Wijk · Tao Lin · Joel Becker · Sami Jawhar · Neev Parikh · Thomas Broadley · Lawrence Chan · Michael Chen · Josh Clymer · Jai Dhyani · Elena Ericheva · Katharyn Garcia · Brian Goodrich · Nikola Jurkovic · Holden Karnofsky · Megan Kinniment · Aron Lajko · Seraphina Nix · Lucas Sato · William Saunders · Maksym Taran · Ben West · Elizabeth Barnes
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{re-bench,
  title = {RE-Bench: Evaluating frontier AI R\&D capabilities of language model agents against human experts},
  url = {https://arxiv.org/abs/2411.15114v2},
  author = {Hjalmar Wijk and Tao Lin and Joel Becker and Sami Jawhar and Neev Parikh and Thomas Broadley and Lawrence Chan and Michael Chen and Josh Clymer and Jai Dhyani and Elena Ericheva and Katharyn Garcia and Brian Goodrich and Nikola Jurkovic and Holden Karnofsky and Megan Kinniment and Aron Lajko and Seraphina Nix and Lucas Sato and William Saunders and Maksym Taran and Ben West and Elizabeth Barnes},
  year = {2024},
  date = {2024-11-22},
  version = {arXiv:2411.15114v2},
  note = {arXiv:2411.15114v2}
}
NUWA record · BibTeX
@misc{re-bench-nuwa,
  title = {RE-Bench: Evaluating frontier AI R\&D capabilities of language model agents against human experts — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/re-bench/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--re-bench.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--re-bench.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Hjalmar Wijk, Tao Lin, et al.. RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts. 2025-05-27. v2 [arXiv]; Author affiliations on the original paper title page; Abstract; §3.1 Design goals