 NUWA
Risk Evaluation · Benchmark
SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: reproduction and repair are separate tasks with different information affordances.
Research question
Can security-agent datasets be built with reproducible vulnerability and patch checks?
Design and assumptions
An automated pipeline reconstructs C/C++ projects, verifies memory-safety defects and evaluates PoC generation and patching with multiple coding scaffolds.
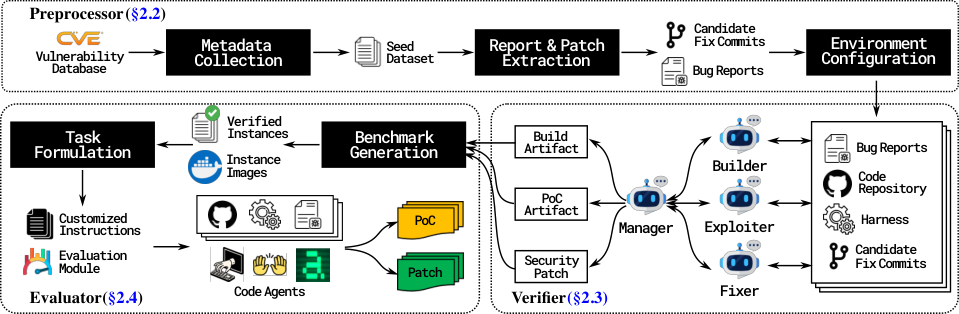
Source findings
The reported best success rates were 18.0% for PoC generation and 34.0% for patching on the complete dataset.
Patch tasks provide vulnerable locations, whereas PoC tasks require more exploration.
NUWA interpretation
NUWA interpretation: reproduction and repair are separate tasks with different information affordances.
Limits and contrary evidence
Sanitizer-detectable memory-safety defects and C/C++ coverage exclude many web, kernel and distributed-system failure classes (§5).
Research and decision relevance
Model recommendation: retain task type and provided location information; do not equate sanitizer reproduction with exploit impact.
Precise source locations
- SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks · AbstractSelected original resource https://arxiv.org/html/2506.11791; sha256:857cf5e1b82d84f586aabf5eabc8626b00d66bd6ff321c8e170bee6eba519ca6; archived source capture; exact capture time not independently established
- SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks · §3.1 Experimental SetupSelected original resource https://arxiv.org/html/2506.11791; sha256:857cf5e1b82d84f586aabf5eabc8626b00d66bd6ff321c8e170bee6eba519ca6; archived source capture; exact capture time not independently established
- SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks · §3.2 Performance of LLM Agents in Security TasksSelected original resource https://arxiv.org/html/2506.11791; sha256:857cf5e1b82d84f586aabf5eabc8626b00d66bd6ff321c8e170bee6eba519ca6; archived source capture; exact capture time not independently established
- SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks · §5 Limitations and Future WorkSelected original resource https://arxiv.org/html/2506.11791; sha256:857cf5e1b82d84f586aabf5eabc8626b00d66bd6ff321c8e170bee6eba519ca6; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles


Authors (4)
Hwiwon Lee · Ziqi Zhang · Hanxiao Lu · Lingming Zhang
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{sec-bench,
  title = {SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks},
  url = {https://arxiv.org/abs/2506.11791},
  author = {Hwiwon Lee and Ziqi Zhang and Hanxiao Lu and Lingming Zhang},
  year = {2025},
  date = {2025-06-13},
  version = {arXiv:2506.11791v2},
  note = {arXiv:2506.11791v2}
}
NUWA record · BibTeX
@misc{sec-bench-nuwa,
  title = {SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/sec-bench/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--sec-bench.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--sec-bench.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Hwiwon Lee Ziqi Zhang Hanxiao Lu † Lingming Zhang. SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks. 2025-06-13. v2 [arXiv]; Author affiliations on the original paper title page; Abstract; §3.1 Experimental Setup