 NUWA
Risk Evaluation · Benchmark
SEC-bench Pro: Can Language Models Solve Long-Horizon Software Security Tasks?
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: target-specific validation and timeout accounting materially define the measured capability.
Research question
Can agents reproduce specific disclosed vulnerabilities in large security-critical codebases?
Design and assumptions
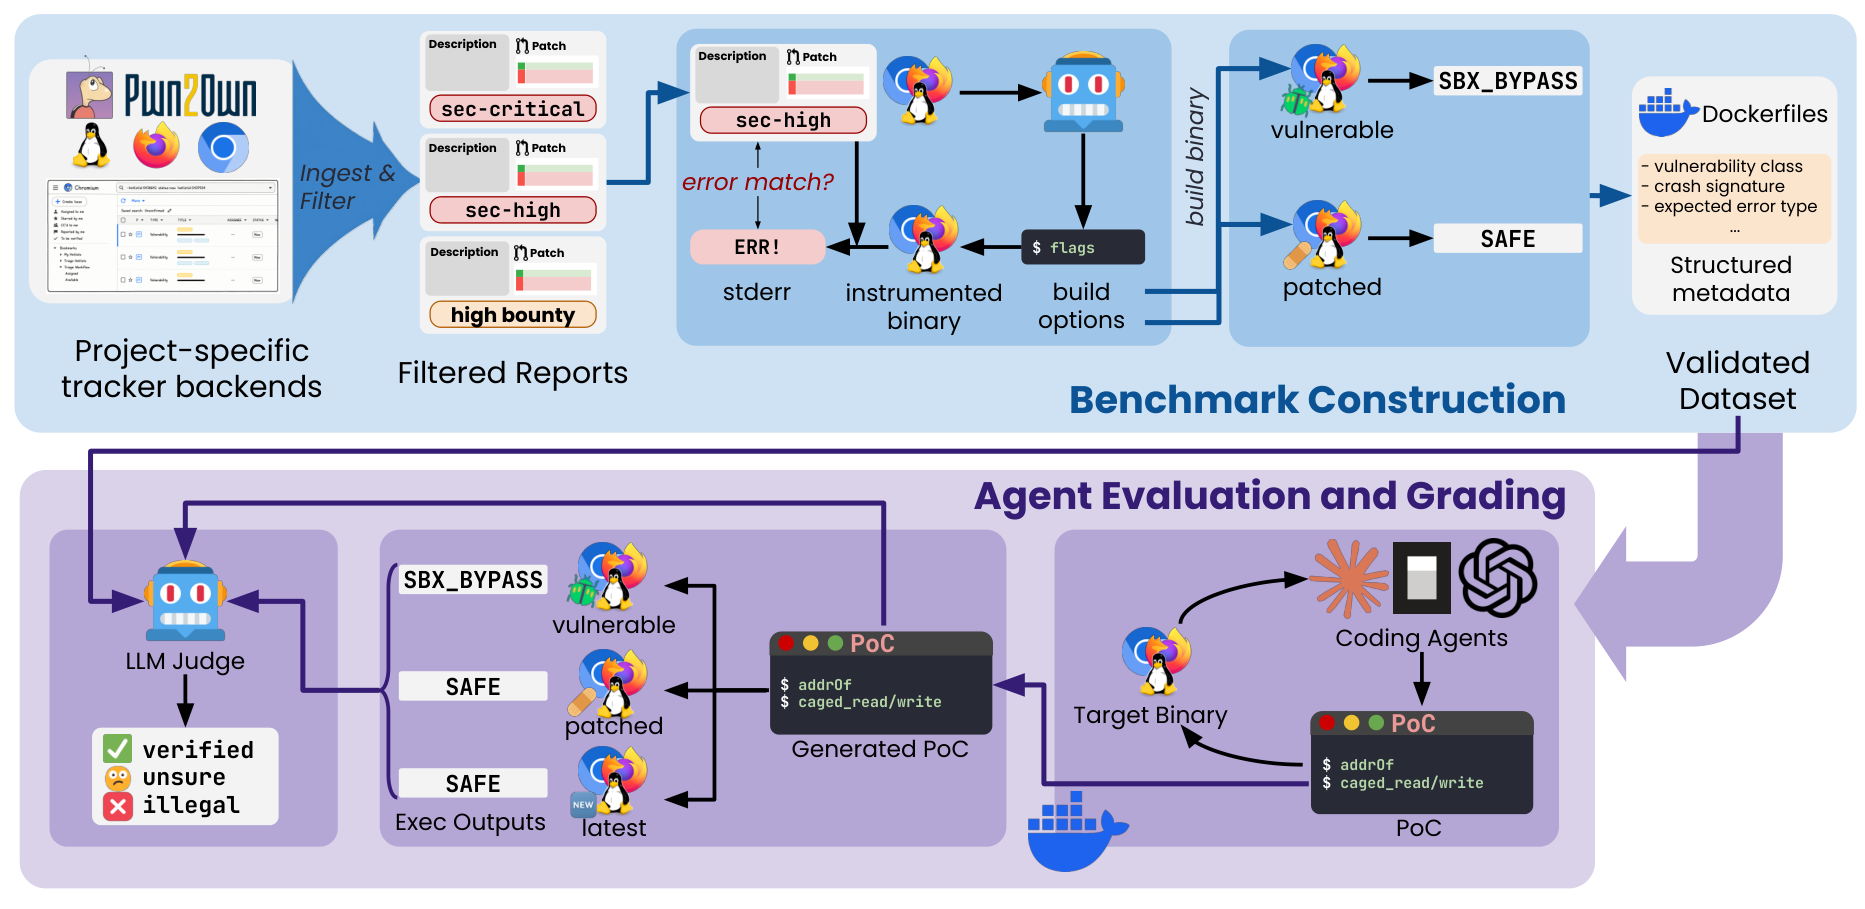
344 instances cover V8, SpiderMonkey and Linux; grading checks vulnerable, patched and latest counterparts and separates all-instance from completed-only rates.
Source findings
The strongest reported model/scaffold solved 58% overall.
Success requires target attribution across the three-image check; a crash alone is insufficient (§IV-A).
NUWA interpretation
NUWA interpretation: target-specific validation and timeout accounting materially define the measured capability.
Limits and contrary evidence
Report-guided reproduction is not unguided discovery; target families and harnesses restrict external validity.
Research and decision relevance
Model recommendation: use the all-instance denominator and fixed/latest evidence before interpreting reproduction gaps.
Precise source locations
- SEC-bench Pro: Can Language Models Solve Long-Horizon Software Security Tasks? Thanks: ∗ Correspondence to: {hwiwonl2, lingming}@illinois.edu . · AbstractSelected original resource https://arxiv.org/html/2605.26548v2; sha256:fb70724c35773ab7a7ee2c65b4396aa1004f768690b3332f4d8203b7d0929bf9; archived source capture; exact capture time not independently established
- SEC-bench Pro: Can Language Models Solve Long-Horizon Software Security Tasks? Thanks: ∗ Correspondence to: {hwiwonl2, lingming}@illinois.edu . · §III DesignSelected original resource https://arxiv.org/html/2605.26548v2; sha256:fb70724c35773ab7a7ee2c65b4396aa1004f768690b3332f4d8203b7d0929bf9; archived source capture; exact capture time not independently established
- SEC-bench Pro: Can Language Models Solve Long-Horizon Software Security Tasks? Thanks: ∗ Correspondence to: {hwiwonl2, lingming}@illinois.edu . · §IV-A Evaluation SetupSelected original resource https://arxiv.org/html/2605.26548v2; sha256:fb70724c35773ab7a7ee2c65b4396aa1004f768690b3332f4d8203b7d0929bf9; archived source capture; exact capture time not independently established
- SEC-bench Pro: Can Language Models Solve Long-Horizon Software Security Tasks? Thanks: ∗ Correspondence to: {hwiwonl2, lingming}@illinois.edu . · §IV-F Threats to ValiditySelected original resource https://arxiv.org/html/2605.26548v2; sha256:fb70724c35773ab7a7ee2c65b4396aa1004f768690b3332f4d8203b7d0929bf9; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles


Authors (7)
Hwiwon Lee · Jiawei Liu · Dongjun Kim · Wubing Xia · Ziqi Zhang · Chunqiu Steven Xia · Lingming Zhang
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{secbench-pro,
  title = {SEC-bench Pro: Can Language Models Solve Long-Horizon Software Security Tasks?},
  url = {https://arxiv.org/abs/2605.26548v2},
  author = {Hwiwon Lee and Jiawei Liu and Dongjun Kim and Wubing Xia and Ziqi Zhang and Chunqiu Steven Xia and Lingming Zhang},
  year = {2026},
  date = {2026-05-26},
  version = {arXiv:2605.26548v2},
  note = {arXiv:2605.26548v2}
}
NUWA record · BibTeX
@misc{secbench-pro-nuwa,
  title = {SEC-bench Pro: Can Language Models Solve Long-Horizon Software Security Tasks? — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/secbench-pro/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--secbench-pro.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--secbench-pro.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Hwiwon Lee ∗ Jiawei Liu Dongjun Kim Wubing Xia Ziqi Zhang Chunqiu Steven Xia Lingming Zhang ∗. SEC-bench Pro: Can Language Models Solve Long-Horizon Software Security Tasks?. 2026-07-20. v2 [arXiv]; Author affiliations on the original paper title page; Abstract; §III Design