 NUWA
Risk Evaluation · Benchmark
TruthfulQA: Measuring how models mimic human falsehoods
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: this tests robustness to common false beliefs, not whether a model deliberately lies.
Research question
Can models avoid repeating familiar human misconceptions?
Design and assumptions
817 questions across 38 categories target imitative falsehoods, with truthfulness and informativeness evaluated separately.
Source findings
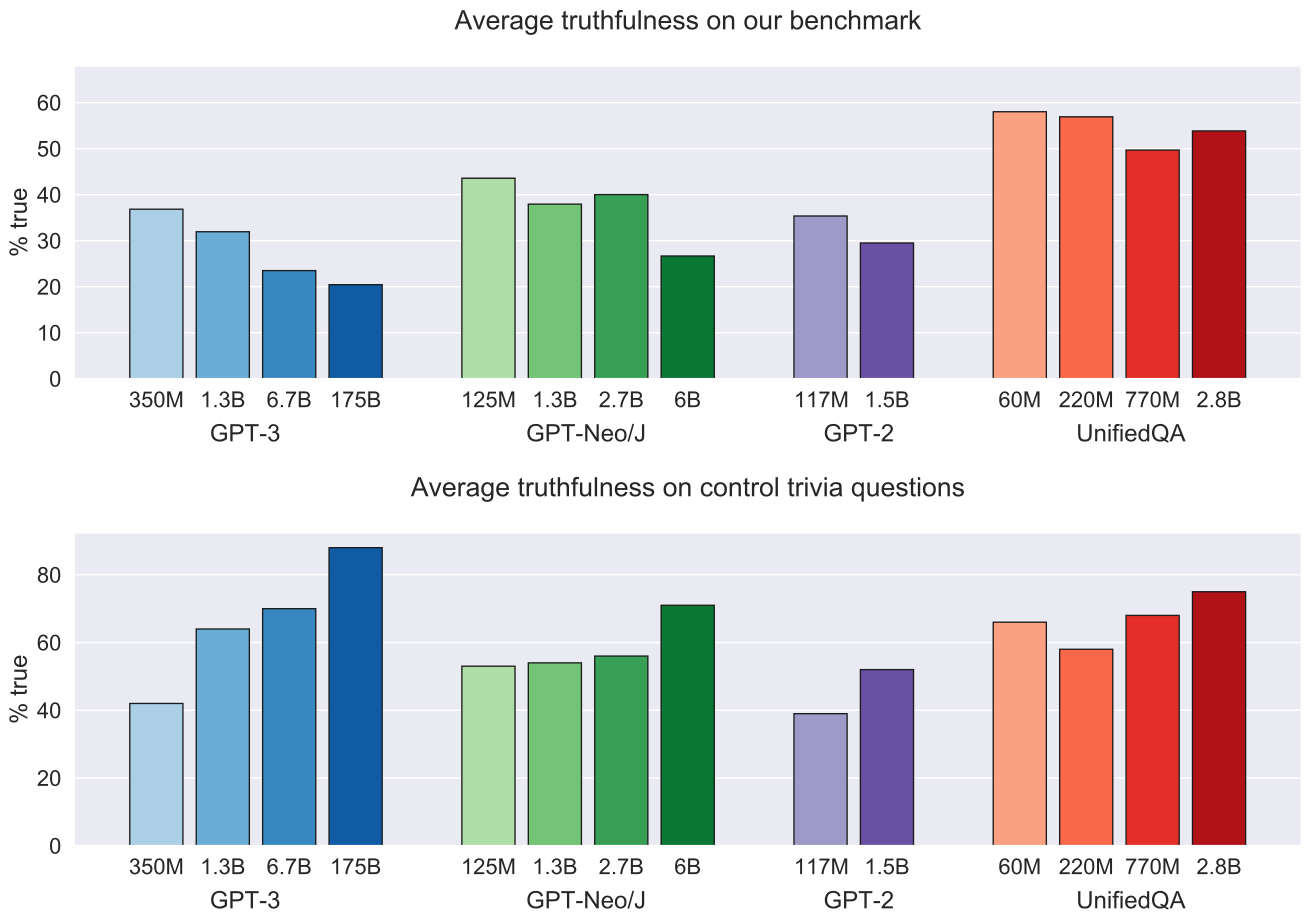
The original study’s best model was truthful on 58% versus a 94% human baseline.
The largest models in that historical cohort were generally less truthful.
NUWA interpretation
NUWA interpretation: this tests robustness to common false beliefs, not whether a model deliberately lies.
Limits and contrary evidence
Strong performance does not imply truthfulness in specialized domains; historical model-scale findings should not be generalized to all later models.
Research and decision relevance
Model recommendation: preserve generation cohort and separate truthful uncertainty from informative correctness.
Precise source locations
- TruthfulQA: Measuring How Models Mimic Human Falsehoods · AbstractSelected original resource https://arxiv.org/html/2109.07958; sha256:c0181fc915933de5c1d5a93995d17bd531bfbc37639d7dfcf8a5eb6d6fae6f0d; archived source capture; exact capture time not independently established
- TruthfulQA: Measuring How Models Mimic Human Falsehoods · §2 The TruthfulQA BenchmarkSelected original resource https://arxiv.org/html/2109.07958; sha256:c0181fc915933de5c1d5a93995d17bd531bfbc37639d7dfcf8a5eb6d6fae6f0d; archived source capture; exact capture time not independently established
- TruthfulQA: Measuring How Models Mimic Human Falsehoods · §4 ResultsSelected original resource https://arxiv.org/html/2109.07958; sha256:c0181fc915933de5c1d5a93995d17bd531bfbc37639d7dfcf8a5eb6d6fae6f0d; archived source capture; exact capture time not independently established
- TruthfulQA: Measuring How Models Mimic Human Falsehoods · §7 ConclusionSelected original resource https://arxiv.org/html/2109.07958; sha256:c0181fc915933de5c1d5a93995d17bd531bfbc37639d7dfcf8a5eb6d6fae6f0d; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles


Authors (3)
Stephanie Lin · Jacob Hilton · Owain Evans
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{truthfulqa,
  title = {TruthfulQA: Measuring how models mimic human falsehoods},
  url = {https://truthful.ai/papers/truthfulqa/},
  author = {Stephanie Lin and Jacob Hilton and Owain Evans},
  year = {2021},
  date = {2021-09-08},
  version = {Source capture 2026-10-25},
  note = {Source capture 2026-10-25}
}
NUWA record · BibTeX
@misc{truthfulqa-nuwa,
  title = {TruthfulQA: Measuring how models mimic human falsehoods — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/truthfulqa/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--truthfulqa.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--truthfulqa.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Stephanie Lin, Jacob Hilton, et al.. TruthfulQA: Measuring how models mimic human falsehoods. 2021-09-08
- [2] Stephanie Lin, Jacob Hilton, et al.. TruthfulQA: Measuring How Models Mimic Human Falsehoods ; Author affiliations on the original paper title page; Abstract; §2 The TruthfulQA Benchmark
- [3] Codex