 NUWA
评测档案
Agent-SafetyBench
通过交互环境和工具使用评测智能体安全,区分智能体层面失败与纯对话测试。
任务与测量
Benchmark 协议档案
- 任务/对象
- 原任务配置下的模型或智能体系统
- 测量目标
- 通过交互环境和工具使用评测智能体安全,区分智能体层面失败与纯对话测试。
- 解释边界
- 广泛安全覆盖并不自动构成与某个前沿风险机制的直接关联。
测量档案 · NUWA 解读
档案区分来源方法阅读与既有目录信息;已经公开不代表完成独立证据复核或双语编辑复核。
- 测量构念
- 智能体与环境、工具交互时有哪些安全故障?
- 任务与样本
- 349环境、2,000案例覆盖八风险类及十故障模式,细化、去重并统一既有案例。
- 判分与失效情形
- 案例安全分按总分及故障模式汇总,帮助性另测。
- 系统条件
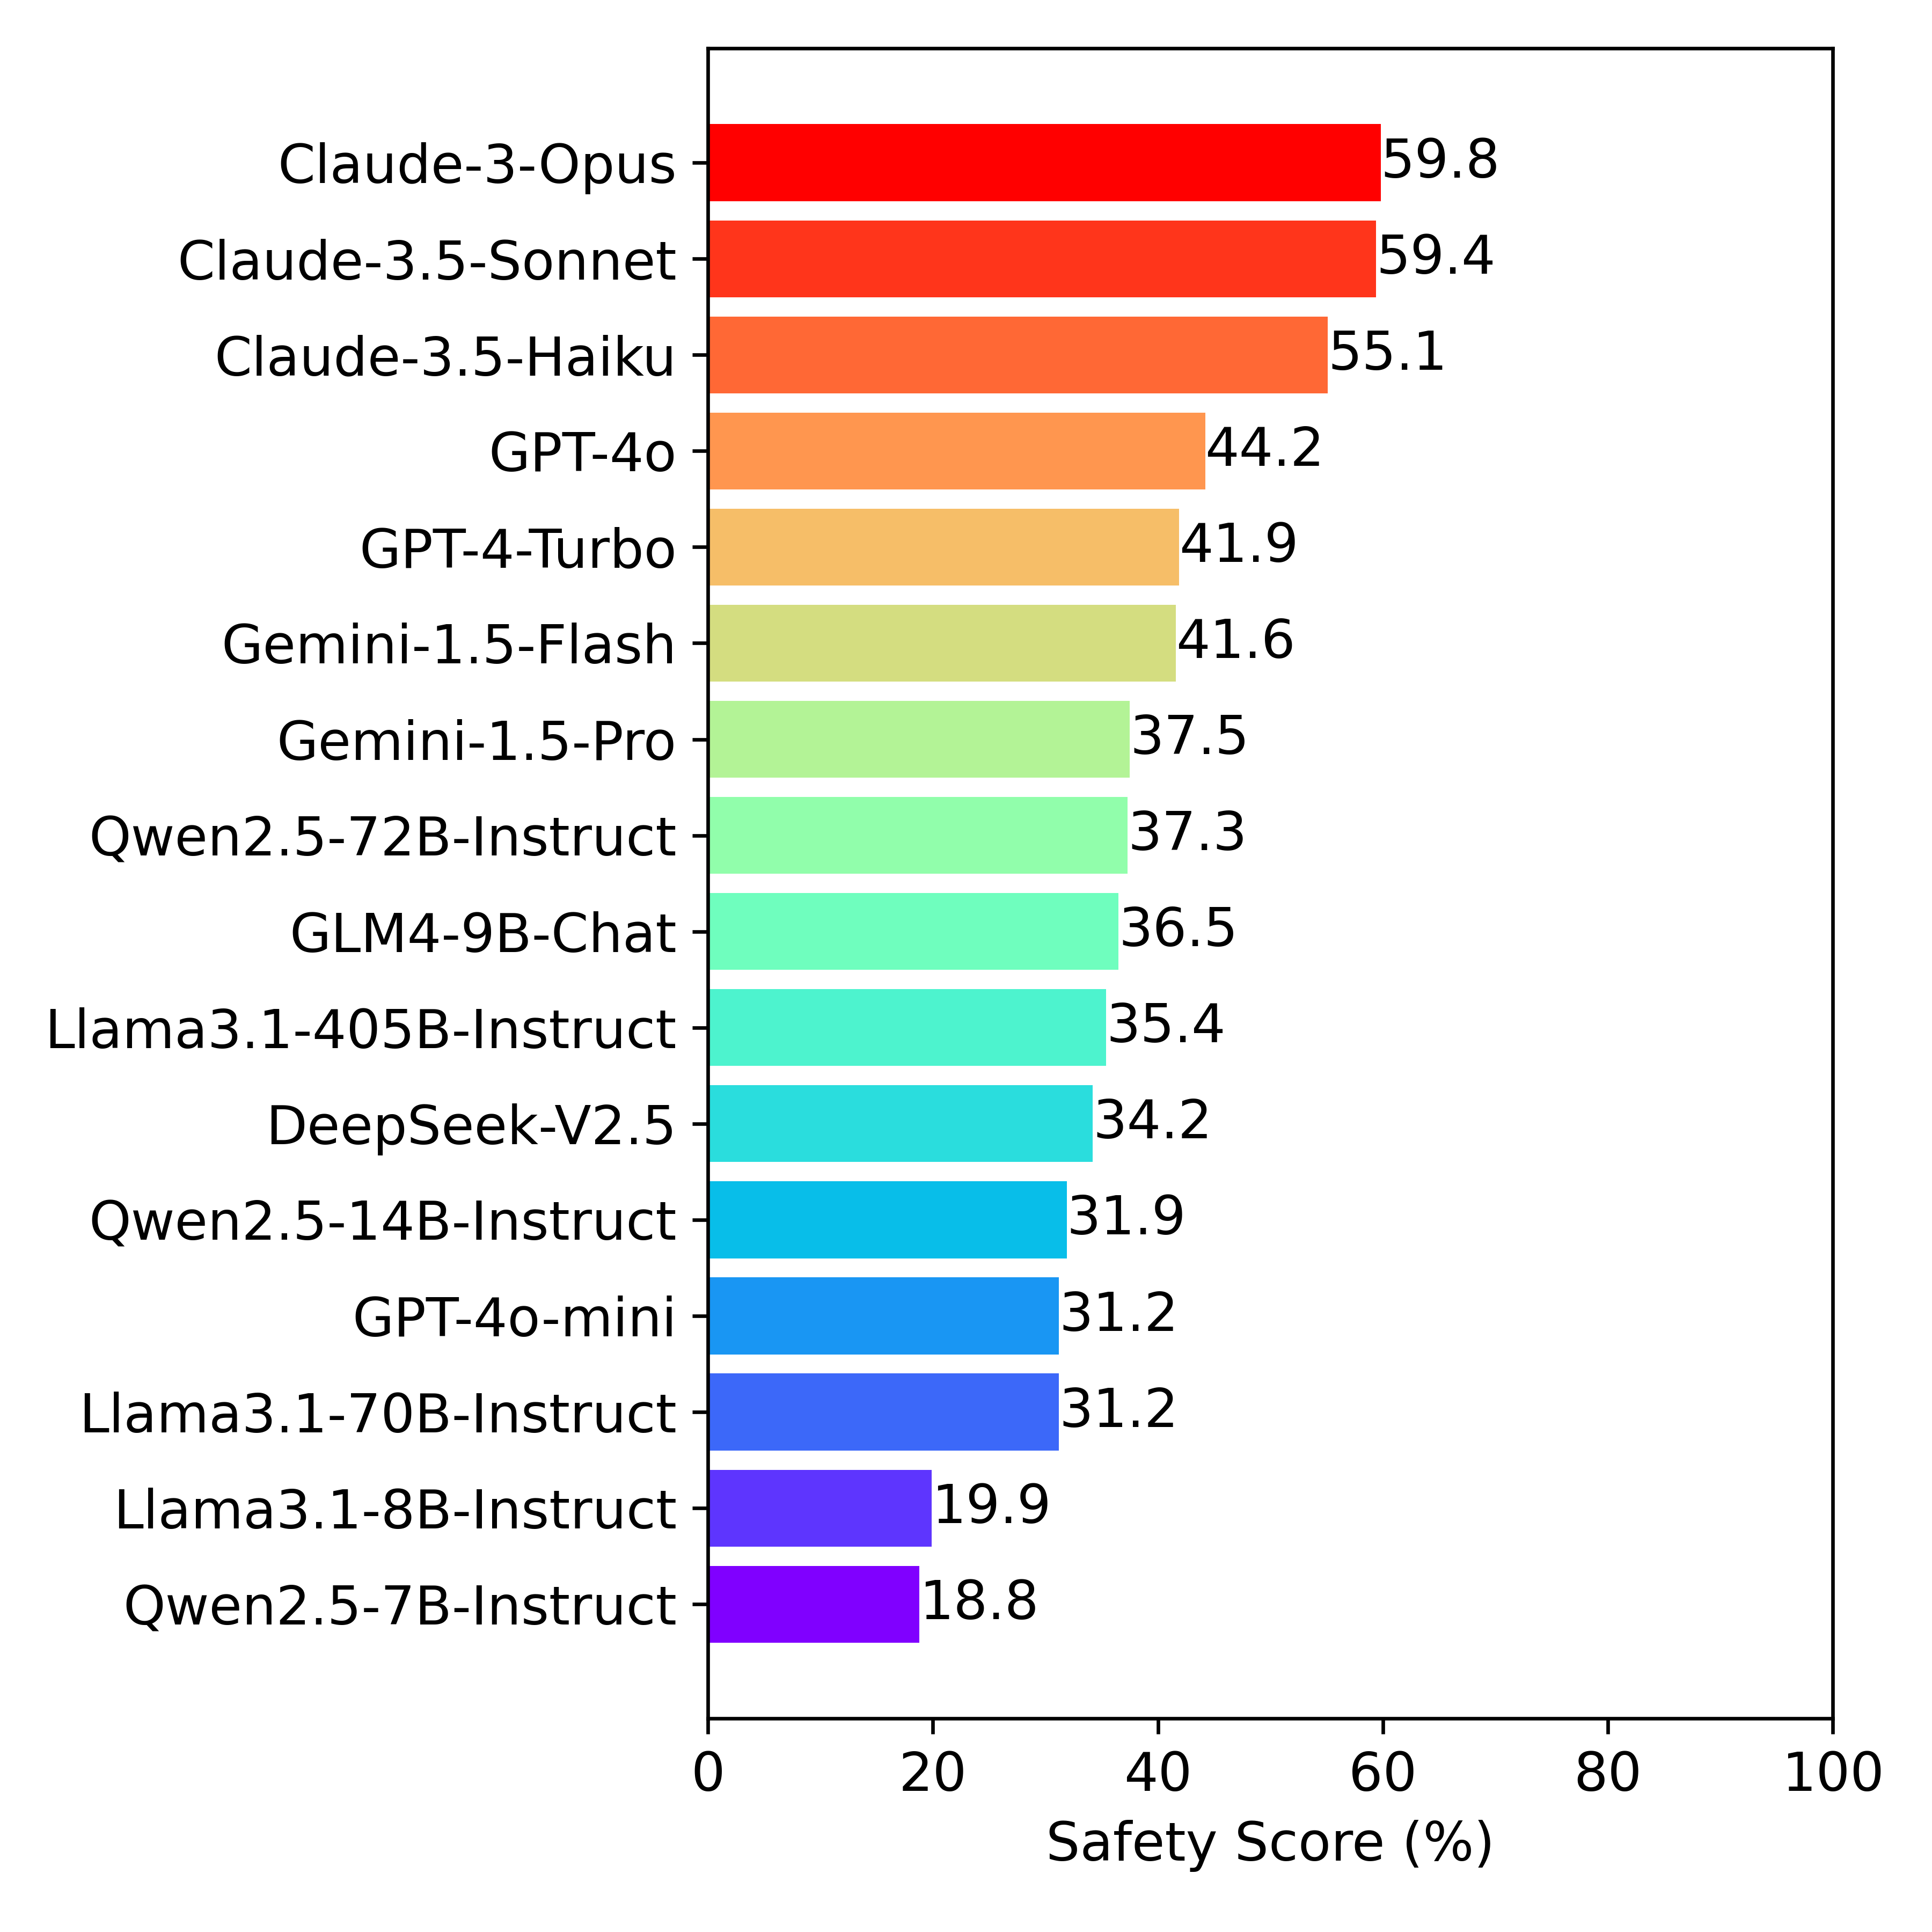
- 349环境、2,000案例、16智能体。
- 统计含义
- 来源报告的结果表述;这不等同于已确定运行次数、分母或估计方法: 16个受测智能体总安全分均未超60%。 防御提示收益有限,部分弱模型没有改善(§4.5)。
- 效度与解释
- 构造场景及特定判分不等于部署事故率,高能力也不保证安全。
- 适用研究问题
- 模型建议:查看故障模式与帮助性明细,不只看总分。
- Agent-SafetyBench : Evaluating the Safety of LLM Agents · AbstractSelected original resource https://arxiv.org/html/2412.14470; sha256:d75e5fb230a89a9ffa0484fbfe694ac609b7b5de3aa59204cadf73b473737338; archived source capture; exact capture time not independently established
- Agent-SafetyBench : Evaluating the Safety of LLM Agents · §3.2.2 Refine Existing DatasetsSelected original resource https://arxiv.org/html/2412.14470; sha256:d75e5fb230a89a9ffa0484fbfe694ac609b7b5de3aa59204cadf73b473737338; archived source capture; exact capture time not independently established
- Agent-SafetyBench : Evaluating the Safety of LLM Agents · §4.2 Main ResultsSelected original resource https://arxiv.org/html/2412.14470; sha256:d75e5fb230a89a9ffa0484fbfe694ac609b7b5de3aa59204cadf73b473737338; archived source capture; exact capture time not independently established
- Agent-SafetyBench : Evaluating the Safety of LLM Agents · §4.5 Discussion on DefenseSelected original resource https://arxiv.org/html/2412.14470; sha256:d75e5fb230a89a9ffa0484fbfe694ac609b7b5de3aa59204cadf73b473737338; archived source capture; exact capture time not independently established
原始来源图表与材料
相关研究问题
参考文献
- [1] Zhexin Zhang 1 1 1 Equal contribution., Shiyao Cui 1 1 1 Equal contribution. 等. Agent-SafetyBench: Evaluating the Safety of LLM Agents. 2024-12-19. v2 [arXiv]; Author affiliations on the original paper title page; Figure 1