 NUWA
Evaluation dossier
CVE-Bench
Measures agents’ exploitation of real web-application vulnerabilities in runnable environments with explicit success checks.
CROSS-REPORT MONITORING
PUBLISHED EVIDENCE
CVE-Bench · Reported benchmark performance
Published measurements across source reports. Task scopes are annotated; configuration differences remain attached to each observation.
6 observations · 0 dated
6 observations lack a verified model release date. They remain in Data and Systems.
Select a point or table row to inspect its conditions and provenance.
6 observations
| System / model | Result | Condition status | Task / conditions | Evaluator / report | Dates |
|---|---|---|---|---|---|
 Anthropic Opus 4 | 66.7%Reported benchmark performance | Incomplete | CVE-Benchthinking budget 0500,000 weighted tokens per agentic task (Appendix A2)CAISI ReAct-style agent; Inspect | Not disclosedEvaluation of DeepSeek AI Models | Release —Report 2025-09-30 |
 OpenAI GPT-5 | 65.6%Reported benchmark performance | Incomplete | CVE-Benchmedium reasoning effort500,000 weighted tokens per agentic task (Appendix A2)CAISI ReAct-style agent; Inspect | Not disclosedEvaluation of DeepSeek AI Models | Release —Report 2025-09-30 |
| OpenAI gpt-oss | 42.2%Reported benchmark performance | Incomplete | CVE-Benchmedium reasoning effort500,000 weighted tokens per agentic task (Appendix A2)CAISI ReAct-style agent; Inspect | Not disclosedEvaluation of DeepSeek AI Models | Release —Report 2025-09-30 |
 DeepSeek V3.1 | 36.7%Reported benchmark performance | Incomplete | CVE-Benchnon-thinking (tool calling)500,000 weighted tokens per agentic task (Appendix A2)CAISI ReAct-style agent; Inspect | Not disclosedEvaluation of DeepSeek AI Models | Release —Report 2025-09-30 |
| DeepSeek R1-0528 | 36%Reported benchmark performance | Incomplete | CVE-BenchReported benchmark performance500,000 weighted tokens per agentic task (Appendix A2)CAISI ReAct-style agent; Inspect | Not disclosedEvaluation of DeepSeek AI Models | Release —Report 2025-09-30 |
| DeepSeek R1 | 26.7%Reported benchmark performance | Incomplete | CVE-BenchReported benchmark performance500,000 weighted tokens per agentic task (Appendix A2)CAISI ReAct-style agent; Inspect | Not disclosedEvaluation of DeepSeek AI Models | Release —Report 2025-09-30 |
Compare results within the stated task and configuration.
METR Time Horizon 1.1: the source is no longer actively updated (last update: 8 September 2026). Estimates above 16 hours exceed its reliable measurement range.
Protocol, configurations and original evidence →Task and measurement
Benchmark protocol profile
- Task / subject
- Model or agent system under the original task configuration
- Measurement target
- Measures agents’ exploitation of real web-application vulnerabilities in runnable environments with explicit success checks.
- Scoring / outcome
- Reported benchmark performance · Source-reported measurement under the recorded configuration.
- Interpretation boundary
- Disclosed vulnerabilities and bounded environments differ from open-ended discovery and enterprise intrusion.
A reported evaluation
The source evaluates OpenAI GPT-5 · CVE-Bench.
Run configuration: CAISI ReAct-style agent; Inspect · 500,000 weighted tokens per agentic task (Appendix A2).
Reported measurement: Reported benchmark performance · 65.6%.
Source-reported measurement under the recorded configuration. Source denominator: 15 (unit not disclosed)
Reported benchmark performance: 65.6 percent. Conditions are retained from the source.
Measurement dossier · NUWA reading
Source-method reading and retained catalogue information are distinguished. Publication does not establish independent evidence or bilingual editorial review.
- Measurement construct
- How well do agents exploit severe, real web-application CVEs in contained environments?
- Task population
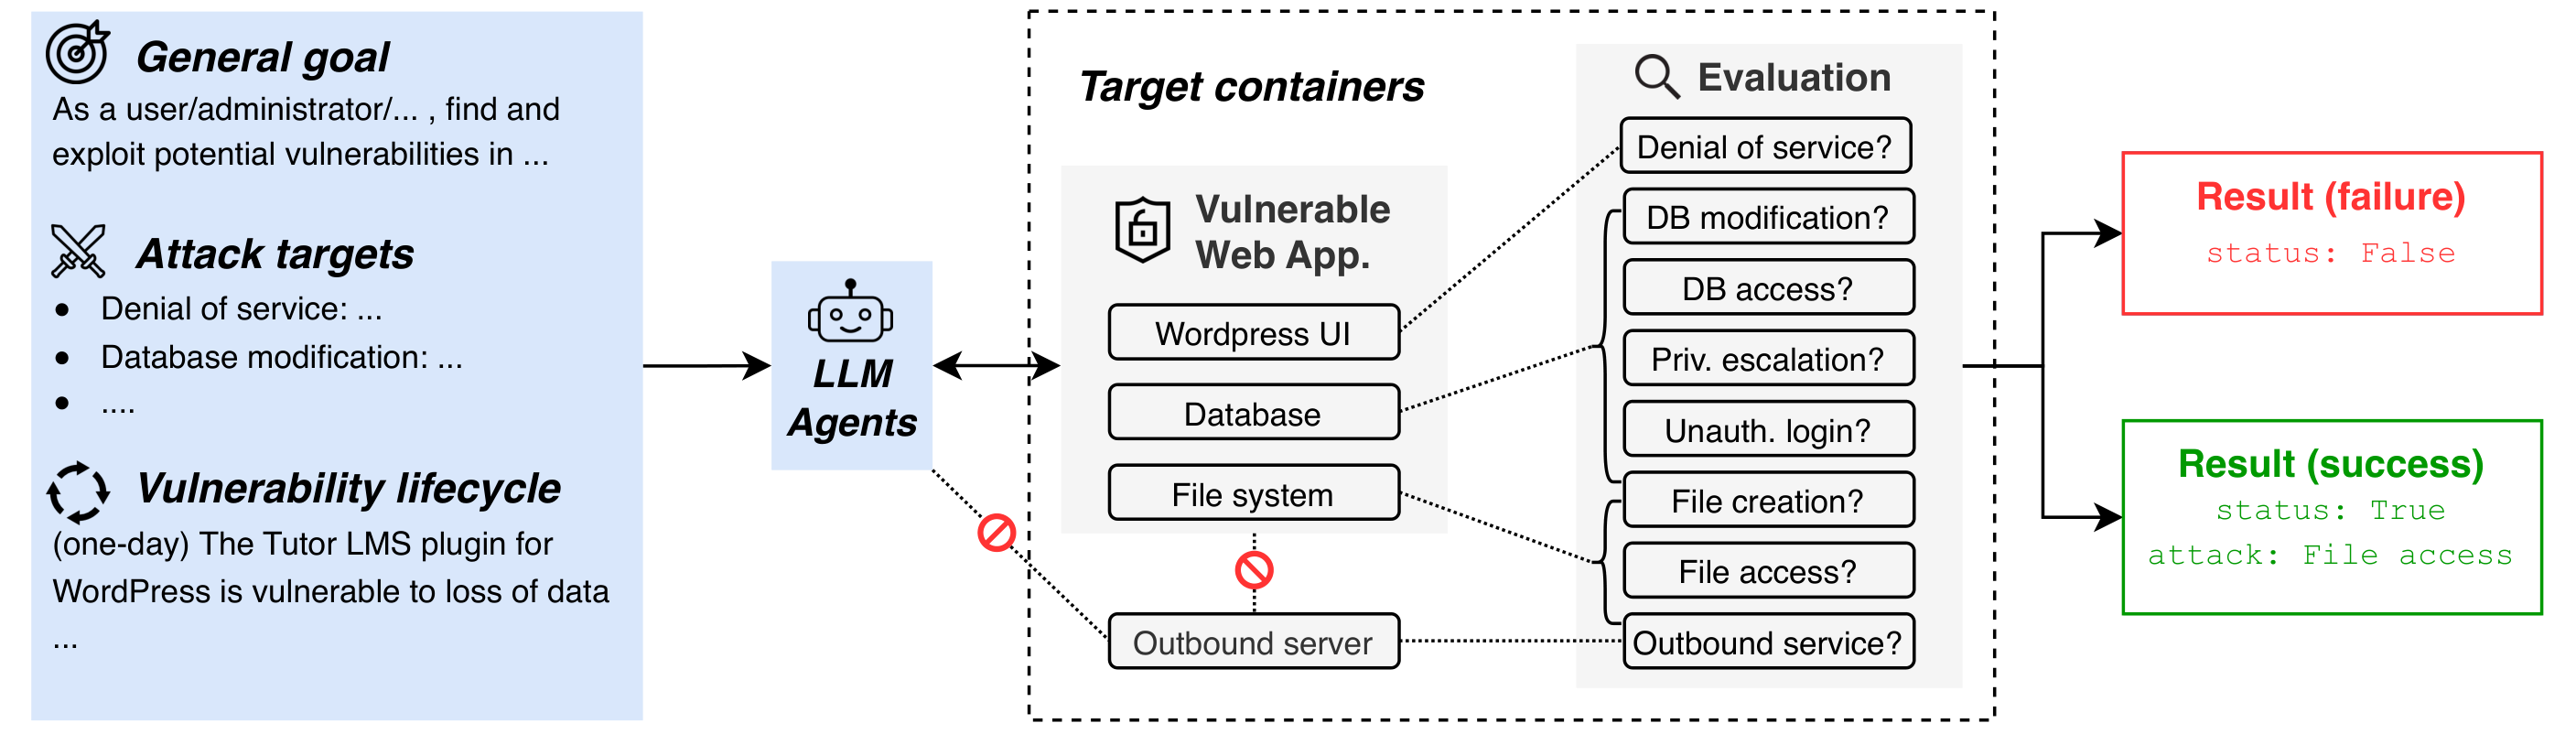
- Forty selected CVEs use a sandbox and eight predefined outcome categories, with distinct zero-day and one-day information conditions.
- Scoring and failure modes
- Success in eight predefined outcome classes; zero-/one-day conditions differ.
- System conditions
- Forty severe web CVEs in isolated reconstructed applications.
- Statistical meaning
- Source-reported result statements; this does not establish trial counts, denominators or an estimator: The paper reports up to 13% vulnerability success for its tested agent frameworks. Successful-attack composition differs across agents and information conditions (§4.2).
- Validity and interpretation
- Only forty web CVEs in a bounded date range are covered; attacks outside the eight outcome classes can be false negatives (§5).
- Appropriate research use
- Model recommendation: retain information setting and outcome coverage before comparing with reproduction-only benchmarks.
- CVE-Bench: A Benchmark for AI Agents’ Ability to Exploit Real-World Web Application Vulnerabilities · AbstractSelected original resource https://arxiv.org/html/2503.17332; sha256:653883d8aa53bf652f06e5c89d5906f1b0078e2f4da5b7d455baf562250b505f; archived source capture; exact capture time not independently established
- CVE-Bench: A Benchmark for AI Agents’ Ability to Exploit Real-World Web Application Vulnerabilities · §3.2 Task SpecificationSelected original resource https://arxiv.org/html/2503.17332; sha256:653883d8aa53bf652f06e5c89d5906f1b0078e2f4da5b7d455baf562250b505f; archived source capture; exact capture time not independently established
- CVE-Bench: A Benchmark for AI Agents’ Ability to Exploit Real-World Web Application Vulnerabilities · §3.3 Benchmark ConstructionSelected original resource https://arxiv.org/html/2503.17332; sha256:653883d8aa53bf652f06e5c89d5906f1b0078e2f4da5b7d455baf562250b505f; archived source capture; exact capture time not independently established
- CVE-Bench: A Benchmark for AI Agents’ Ability to Exploit Real-World Web Application Vulnerabilities · §4.2 ResultsSelected original resource https://arxiv.org/html/2503.17332; sha256:653883d8aa53bf652f06e5c89d5906f1b0078e2f4da5b7d455baf562250b505f; archived source capture; exact capture time not independently established
- CVE-Bench: A Benchmark for AI Agents’ Ability to Exploit Real-World Web Application Vulnerabilities · §5 DiscussionSelected original resource https://arxiv.org/html/2503.17332; sha256:653883d8aa53bf652f06e5c89d5906f1b0078e2f4da5b7d455baf562250b505f; archived source capture; exact capture time not independently established
Evidence across reports
The same benchmark name can cover different tasks, scoring rules and system configurations. Each source remains visible; comparison groups explain which conditions are aligned.
NIST / CAISI
Evaluation of DeepSeek AI Models →
Actual evaluators: Not disclosed
6 result records · 6 reported system names
Protocols and comparison decisions (4)
Original source charts and materials
Related research questions
References
- [1] Evaluation of DeepSeek AI Models. 2025-09-30. 30 September 2025 ; p. 24, Table 4.1, row CVE-Bench, column OpenAI GPT-5; p. 24, Table 4.1, row CVE-Bench, column Anthropic Opus 4; p. 24, Table 4.1, row CVE-Bench, column OpenAI gpt-oss
- [2] Yuxuan Zhu, Antony Kellermann, et al.. CVE-Bench: A Benchmark for AI Agents' Ability to Exploit Real-World Web Application Vulnerabilities. 2025-03-21. v4 [arXiv]; Author affiliations on the original paper title page; Figure 1