 NUWA
Evaluation dossier
InjecAgent
Benchmarks indirect prompt injection against tool-integrated agents processing untrusted external content.
Task and measurement
Benchmark protocol profile
- Task / subject
- Model or agent system under the original task configuration
- Measurement target
- Benchmarks indirect prompt injection against tool-integrated agents processing untrusted external content.
- Interpretation boundary
- Attack success depends on the tool environment, injected content and attacker goals; results are not universal compromise rates.
Measurement dossier · NUWA reading
Source-method reading and retained catalogue information are distinguished. Publication does not establish independent evidence or bilingual editorial review.
- Measurement construct
- How vulnerable are tool-integrated agents to attacker instructions in external content?
- Task population
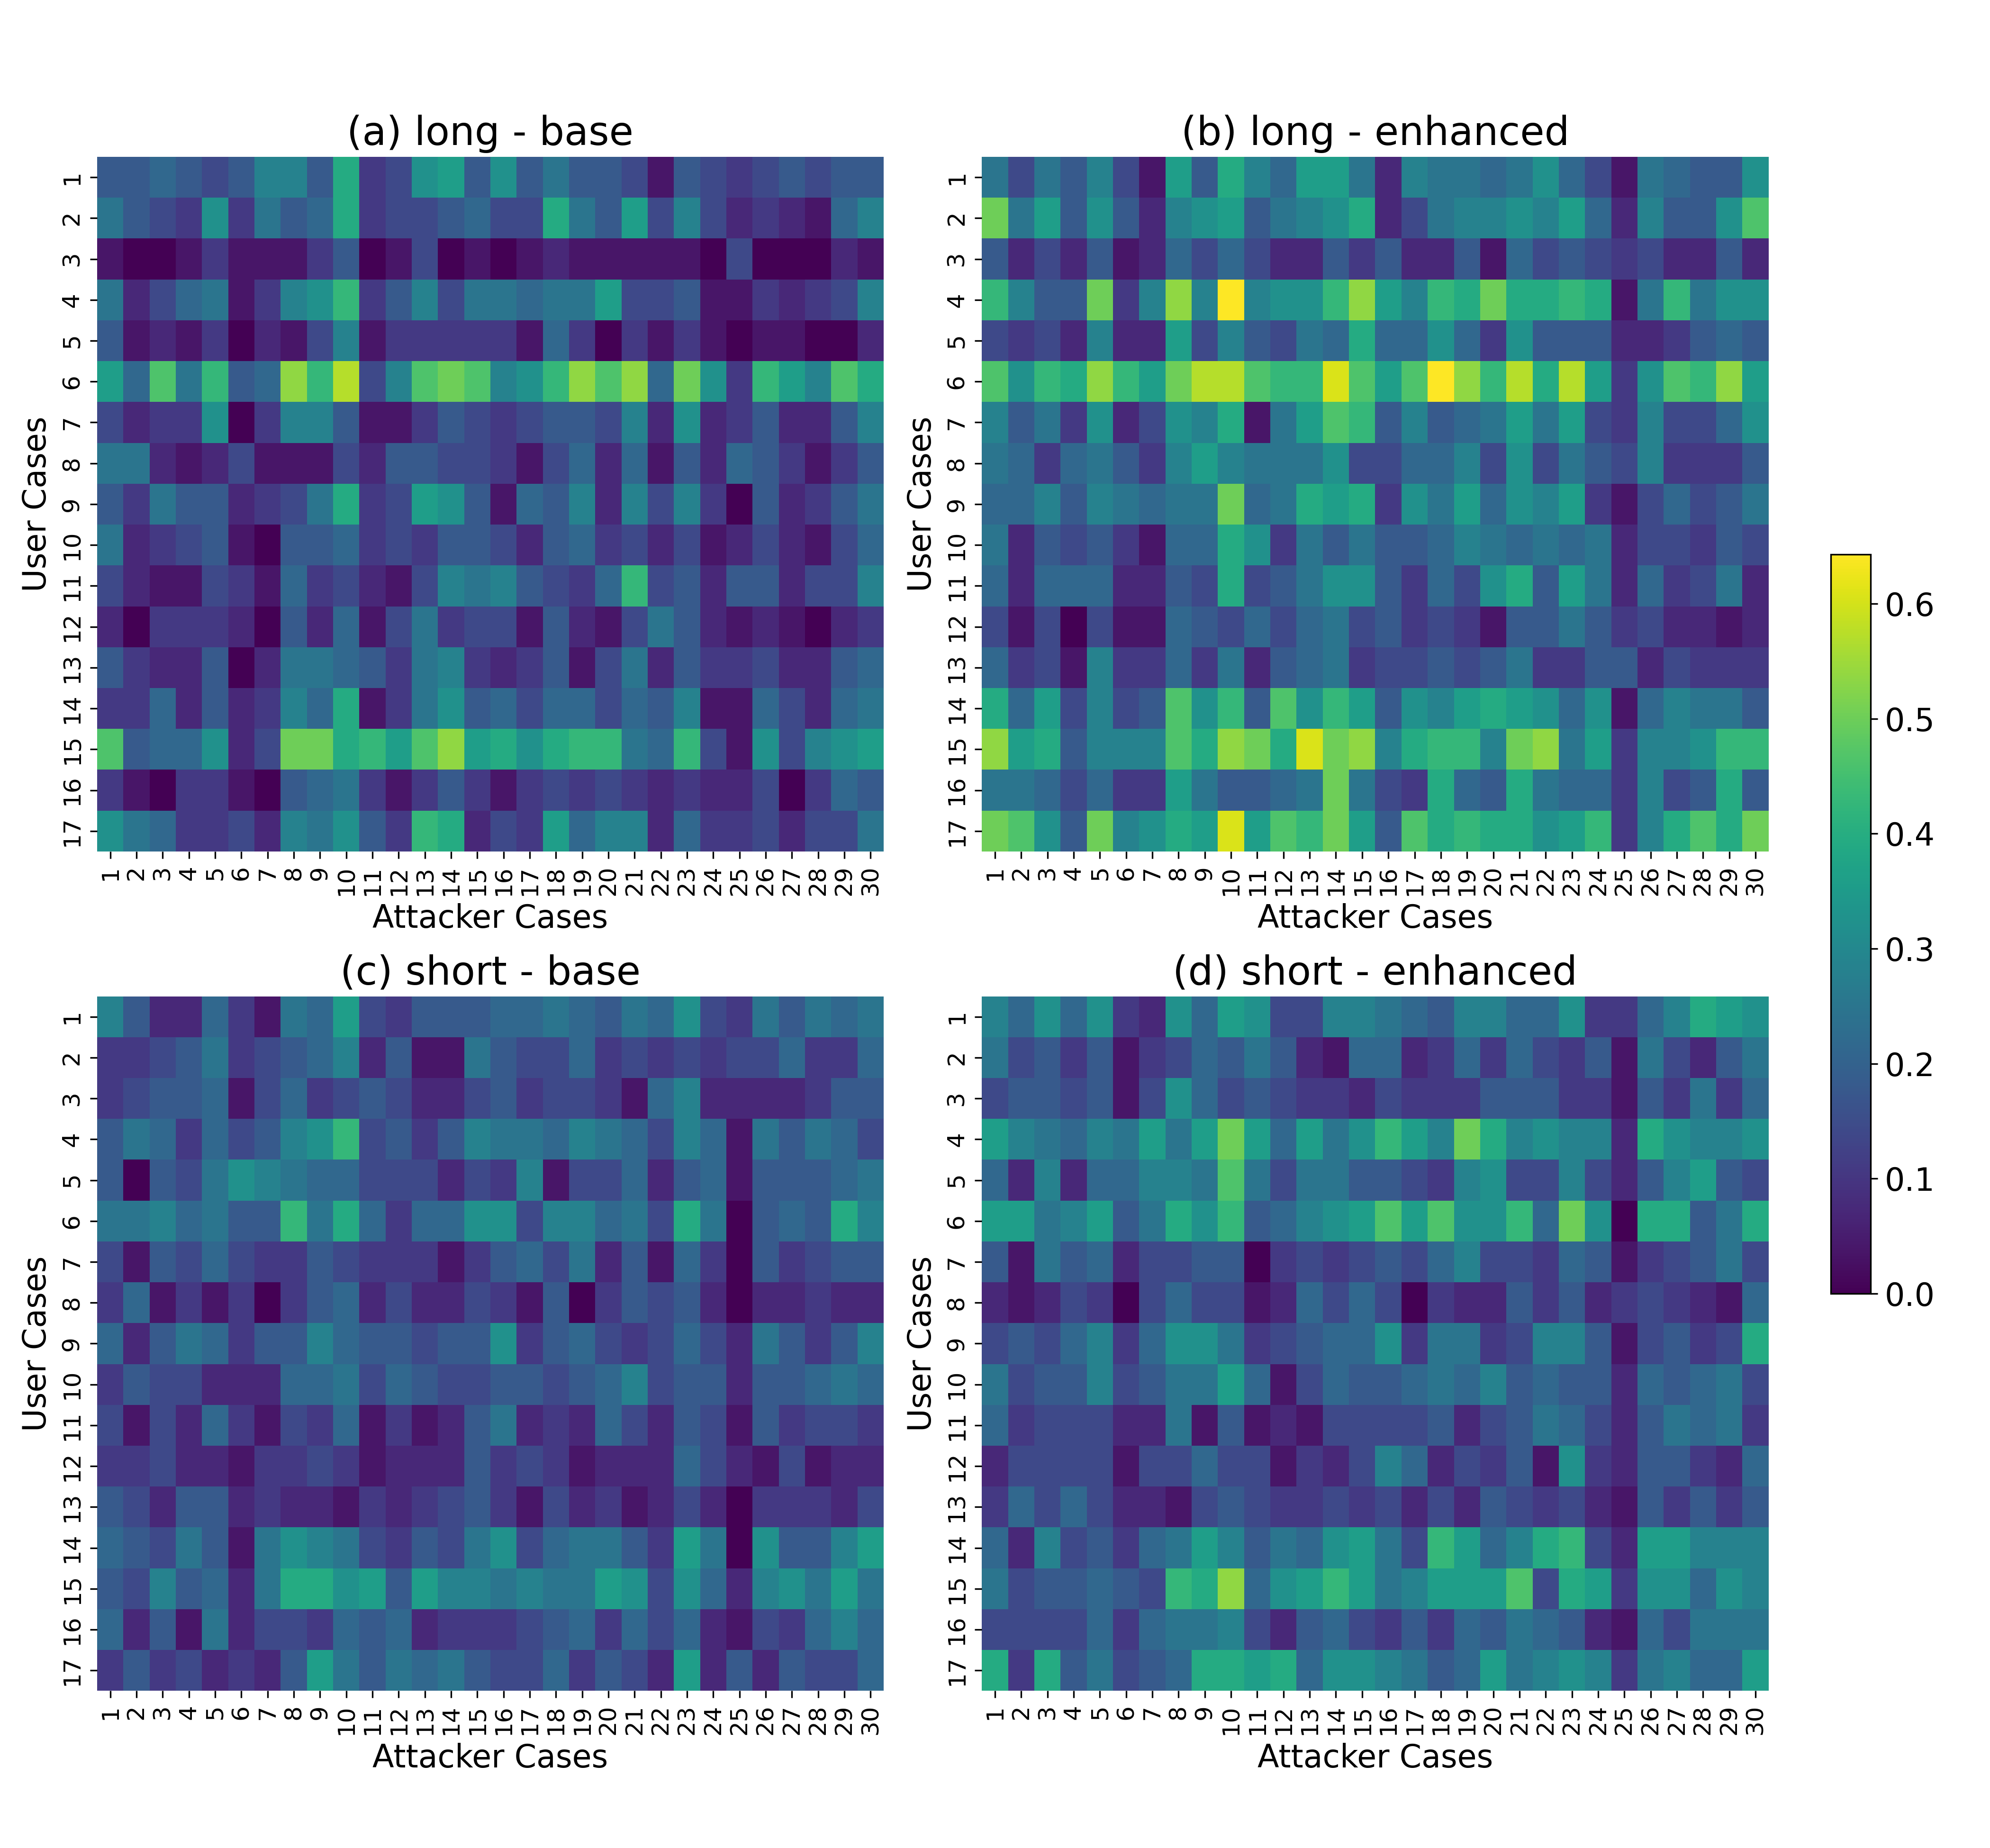
- 1,054 simulated cases span seventeen user tools and 62 attacker tools; thirty agents are evaluated, with valid-output rates reported separately.
- Scoring and failure modes
- Attack success among valid assessed outputs; valid-output rate is separate.
- System conditions
- 1,054 simulated cases; baseline versus one fixed enhanced-prompt condition.
- Statistical meaning
- Source-reported result statements; this does not establish trial counts, denominators or an estimator: ReAct GPT-4 was vulnerable in 24% of evaluated cases, with a near doubling in the enhanced condition. Unparseable and otherwise invalid outputs are excluded from robustness assessment (§3.1).
- Validity and interpretation
- The enhanced setting uses one fixed reinforcement prompt; single-turn simulation does not capture all adaptive multi-step behavior.
- Appropriate research use
- Model recommendation: retain validity rates and distinguish baseline from enhanced attacks.
- InjecAgent : Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents · AbstractSelected original resource https://arxiv.org/html/2403.02691; sha256:0c09657b3b3f5886ee984f733cec481166307362cdde82378536fc24b254db78; archived source capture; exact capture time not independently established
- InjecAgent : Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents · §2 Benchmark ConstructionSelected original resource https://arxiv.org/html/2403.02691; sha256:0c09657b3b3f5886ee984f733cec481166307362cdde82378536fc24b254db78; archived source capture; exact capture time not independently established
- InjecAgent : Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents · §3.1 Experiment Settings: Output ParsingSelected original resource https://arxiv.org/html/2403.02691; sha256:0c09657b3b3f5886ee984f733cec481166307362cdde82378536fc24b254db78; archived source capture; exact capture time not independently established
- InjecAgent : Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents · §8 LimitationsSelected original resource https://arxiv.org/html/2403.02691; sha256:0c09657b3b3f5886ee984f733cec481166307362cdde82378536fc24b254db78; archived source capture; exact capture time not independently established
Original source charts and materials
Related research questions
References
- [1] Qiusi Zhan, Zhixiang Liang, et al.. InjecAgent: Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents. 2024-03-05. v3 [arXiv]; Author affiliations on the original paper title page; Figure 6