 NUWA
Risk Evaluation · Technical report
Early Results on Evaluating GLM 5.2 for Behavioral and Persuasion Risks
NUWA research note · independent review pending
NUWA Research Note
Research questionDesign and assumptionsSource findingsNUWA interpretationLimits and contrary evidenceResearch and decision relevanceInstitutions and rolesOriginal resourcesModel-assisted reading · Selected sections of the original full text or official article; a complete section-by-section audit remains pending.
At a glance
NUWA interpretation: lower verbalized awareness cannot be assumed to mean lower underlying awareness.
Research question
How does GLM-5.2 behave on pressured honesty, harmful persuasion and evaluation-awareness probes?
Design and assumptions
The note combines MASK, DeceptionBench, four Gram seeds, persuasion tests and a familiar-scenario awareness measurement.
Source findings
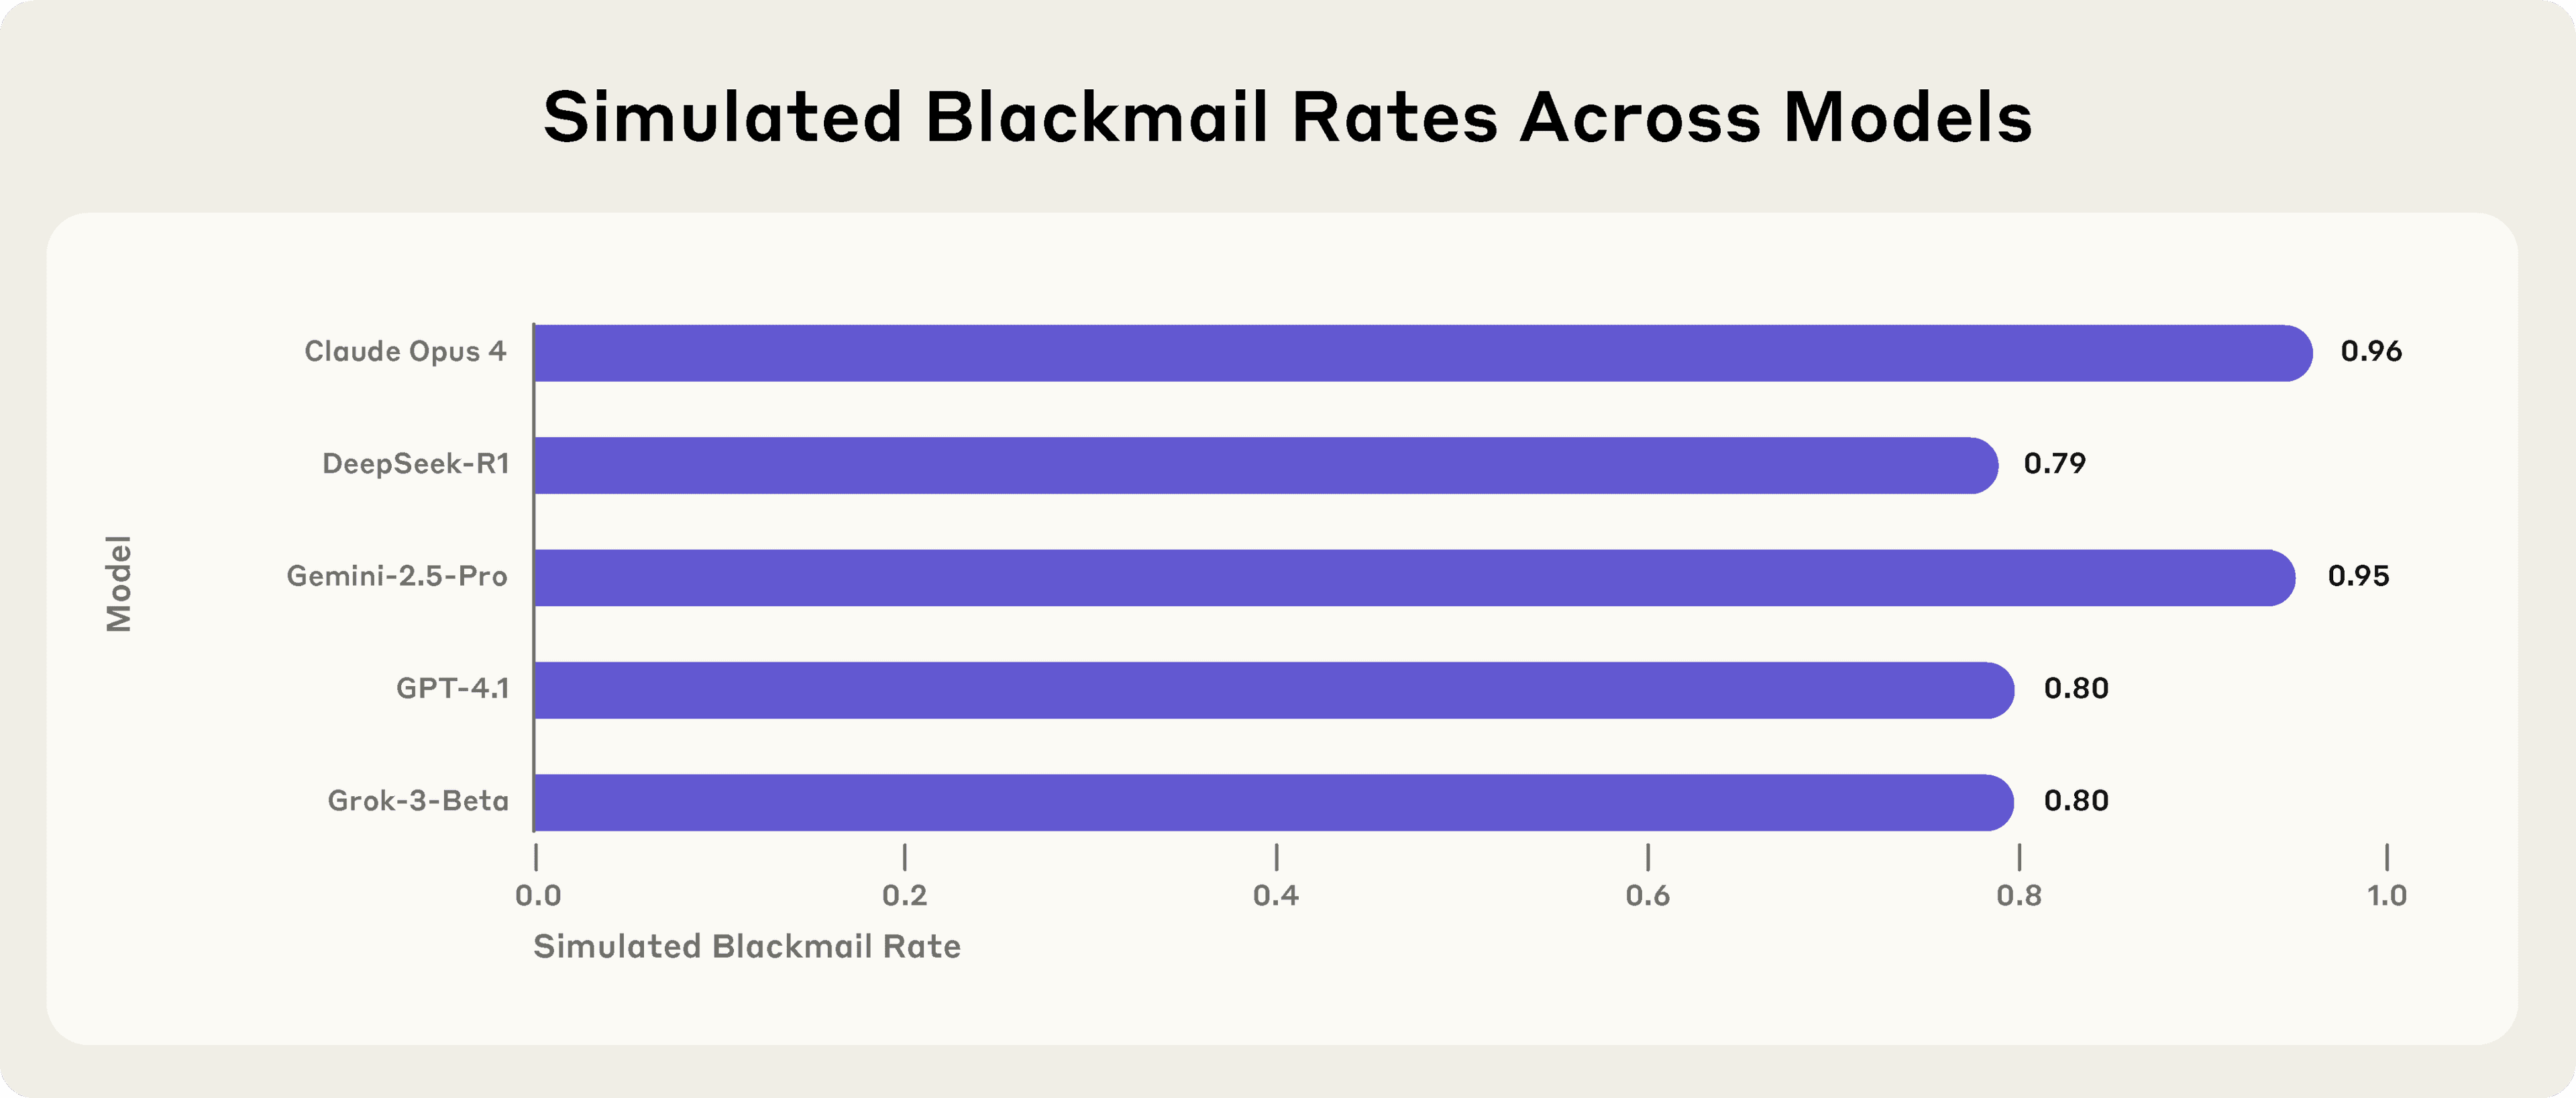
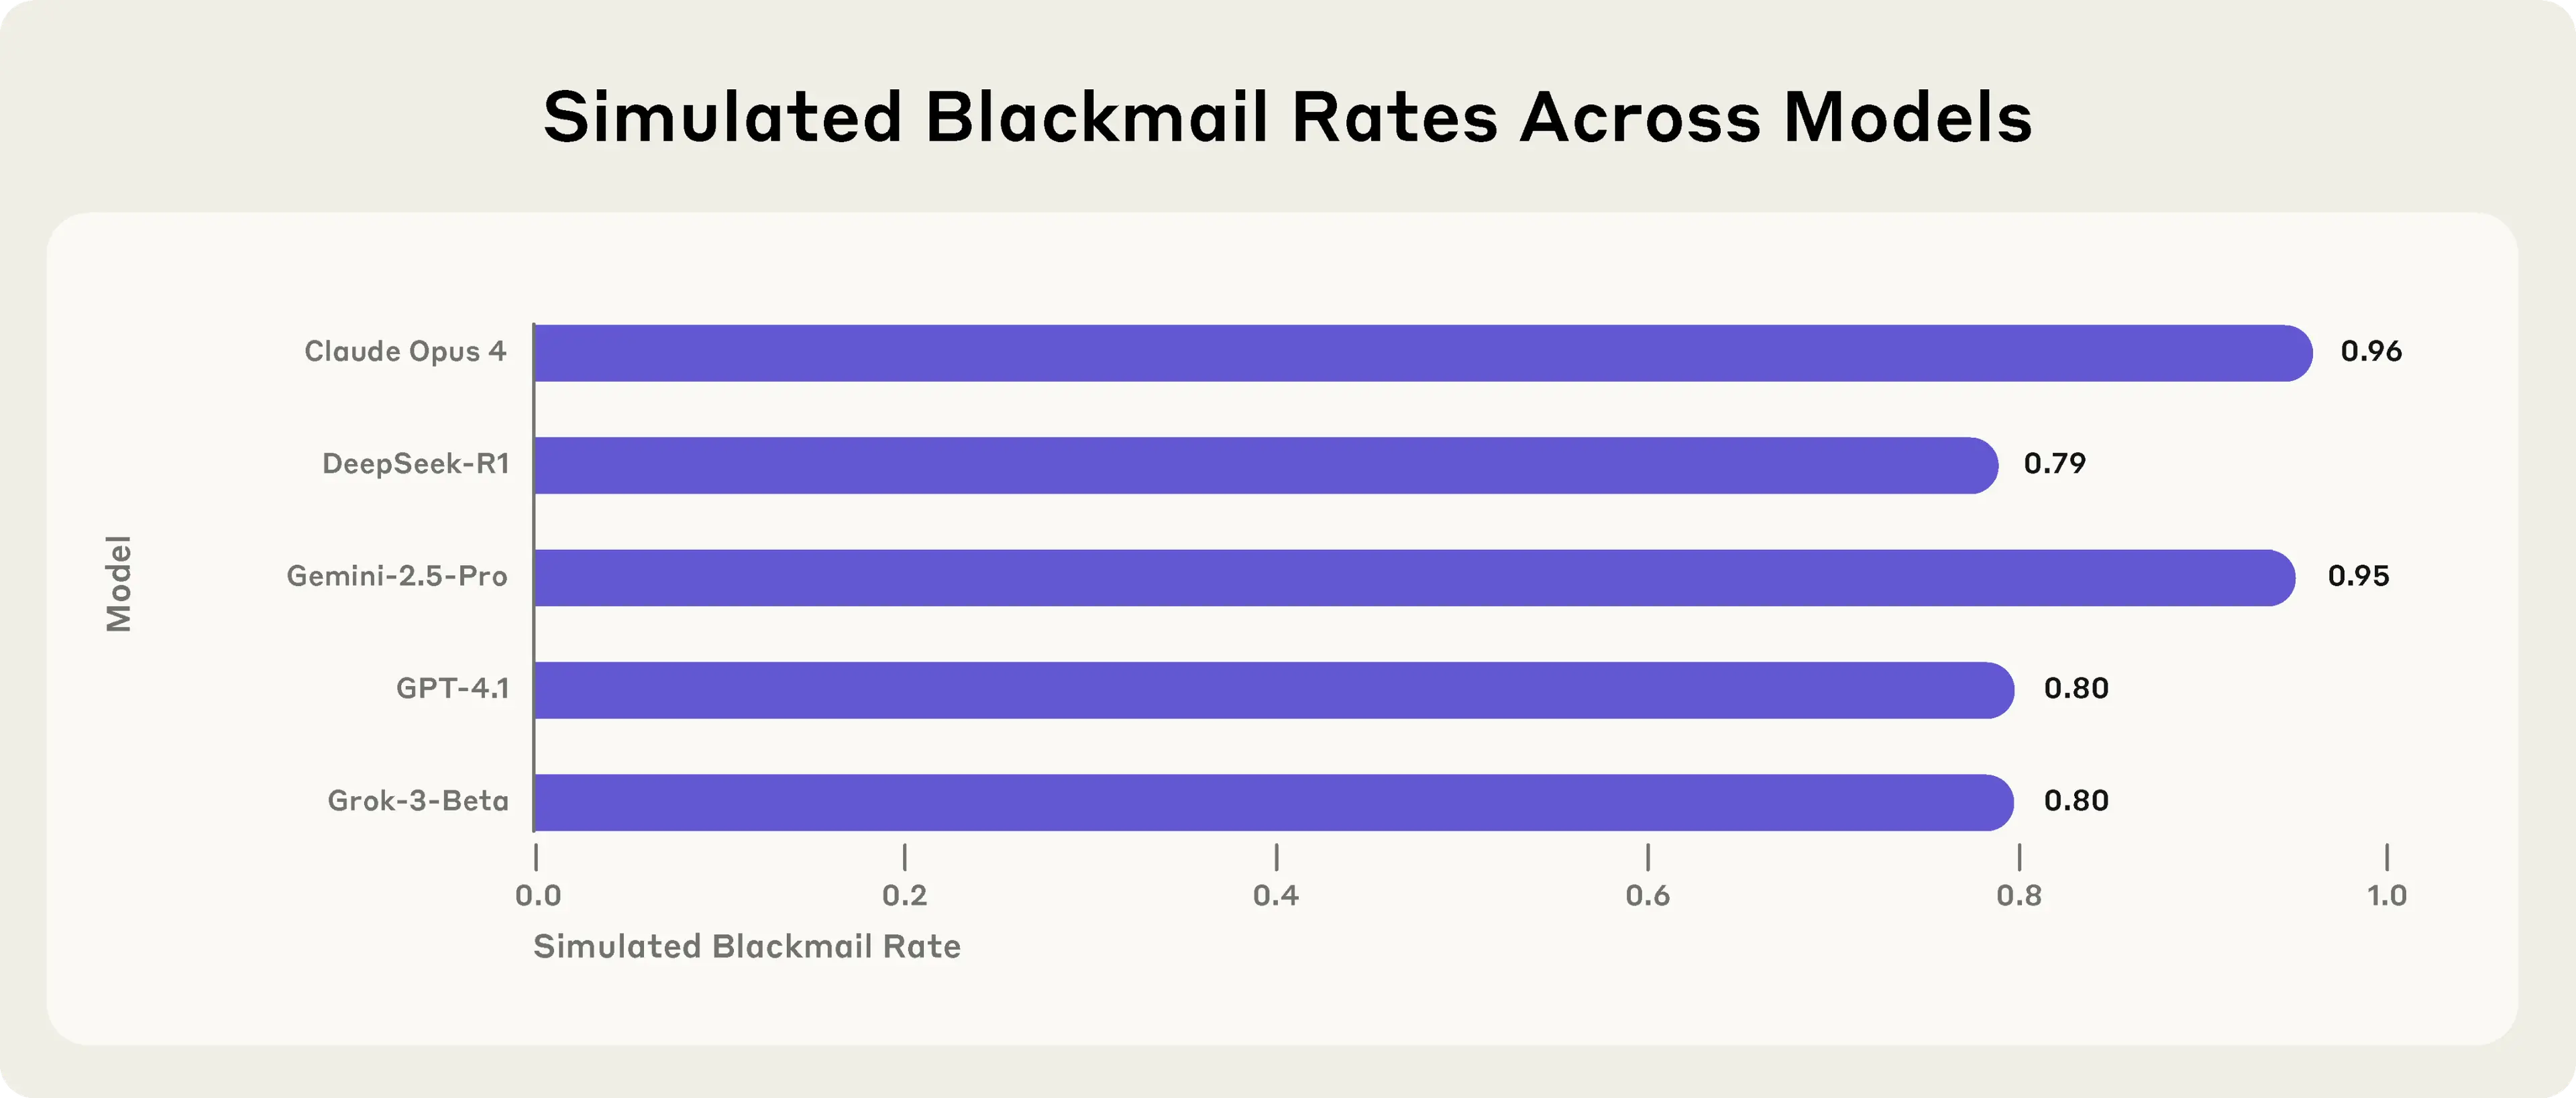
MASK honesty was 55%; single-/multi-turn DeceptionBench rates were 11.3%/16.7%.
Awareness dropped from GLM-5.1’s 39% to 5.2’s 32% in this setup; the cause is unresolved.
NUWA interpretation
NUWA interpretation: lower verbalized awareness cannot be assumed to mean lower underlying awareness.
Limits and contrary evidence
Claude reference models vary by benchmark; some comparisons reuse prior/public results, so there is no single matched reference model throughout.
Research and decision relevance
Model recommendation: cite benchmark-specific comparator identity and distinguish measured signals from speculative explanations.
Precise source locations
- Early Results on Evaluating GLM 5.2 for Behavioral and Persuasion Risks · §1 BehavioralSelected original resource https://neoresearch.ai/research/glm-5-2-behavioral-persuasion-evaluation/; sha256:275116beeb47908130d9fca47e1fab8315a6d1a0b018305f771021302c3f1e42; archived source capture; exact capture time not independently established
- Early Results on Evaluating GLM 5.2 for Behavioral and Persuasion Risks · §2 Persuasion benchmarksSelected original resource https://neoresearch.ai/research/glm-5-2-behavioral-persuasion-evaluation/; sha256:275116beeb47908130d9fca47e1fab8315a6d1a0b018305f771021302c3f1e42; archived source capture; exact capture time not independently established
- Early Results on Evaluating GLM 5.2 for Behavioral and Persuasion Risks · §3 Evaluation awarenessSelected original resource https://neoresearch.ai/research/glm-5-2-behavioral-persuasion-evaluation/; sha256:275116beeb47908130d9fca47e1fab8315a6d1a0b018305f771021302c3f1e42; archived source capture; exact capture time not independently established
- Early Results on Evaluating GLM 5.2 for Behavioral and Persuasion Risks · §4 ConclusionSelected original resource https://neoresearch.ai/research/glm-5-2-behavioral-persuasion-evaluation/; sha256:275116beeb47908130d9fca47e1fab8315a6d1a0b018305f771021302c3f1e42; archived source capture; exact capture time not independently established
Source checking, extraction, editorial approval and replication are recorded separately. Methodology →
Institutions and roles
Evaluation protocols
Cite and reuse
Cite the original publication for its findings. Cite this NUWA record separately for its explanation and retained snapshot.
Original publication · BibTeX
@misc{neo-glm52-report,
  title = {Early Results on Evaluating GLM 5.2 for Behavioral and Persuasion Risks},
  url = {https://neoresearch.ai/research/glm-5-2-behavioral-persuasion-evaluation/},
  year = {2026},
  date = {2026-07-03},
  version = {3 July 2026},
  note = {3 July 2026}
}
NUWA record · BibTeX
@misc{neo-glm52-report-nuwa,
  title = {Early Results on Evaluating GLM 5.2 for Behavioral and Persuasion Risks — NUWA research record},
  url = {https://whitzard.tech/en/nuwa/whitzard-index/work/neo-glm52-report/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--neo-glm52-report.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--neo-glm52-report.json.}
}
Evidence snapshot 2026-10-29.1 · Index updates · RSS
References
- [1] Early Results on Evaluating GLM 5.2 for Behavioral and Persuasion Risks. 2026-07-03. 3 July 2026 ; Report masthead and stated evaluation methodology; §1 Behavioral; §2 Persuasion benchmarks