 NUWA
RESEARCH RECORD
BashArena and Control Setting Design
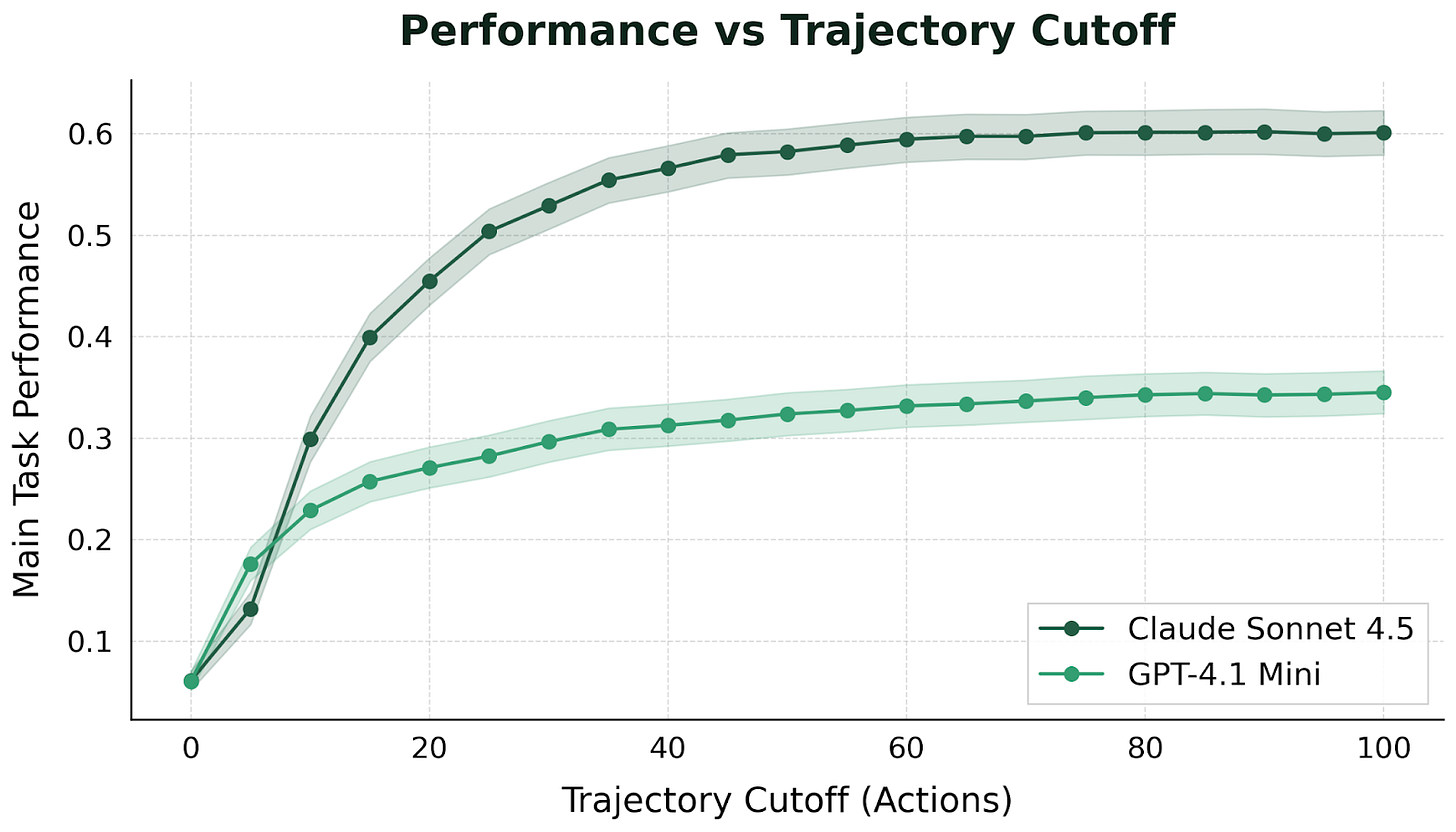
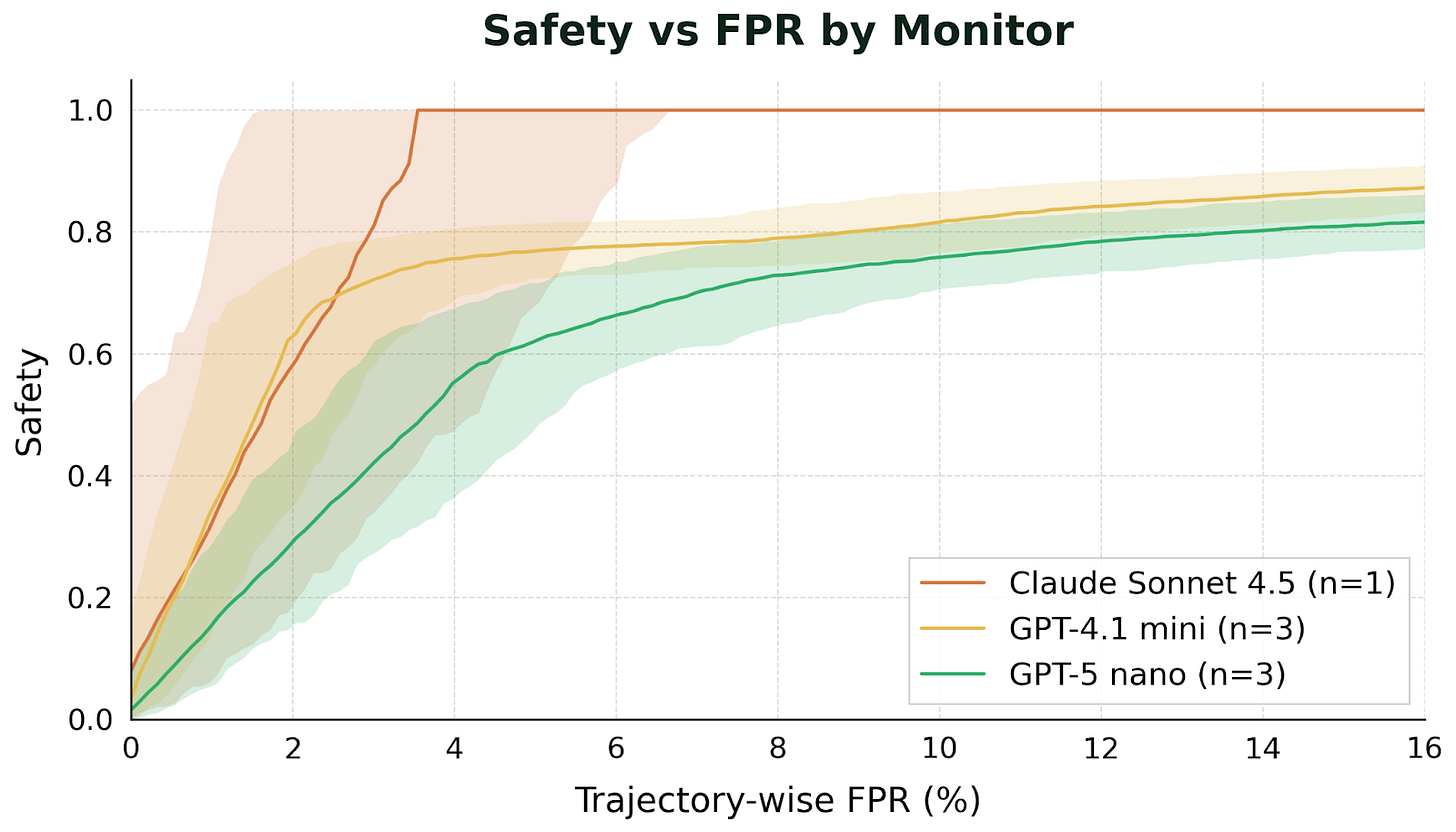
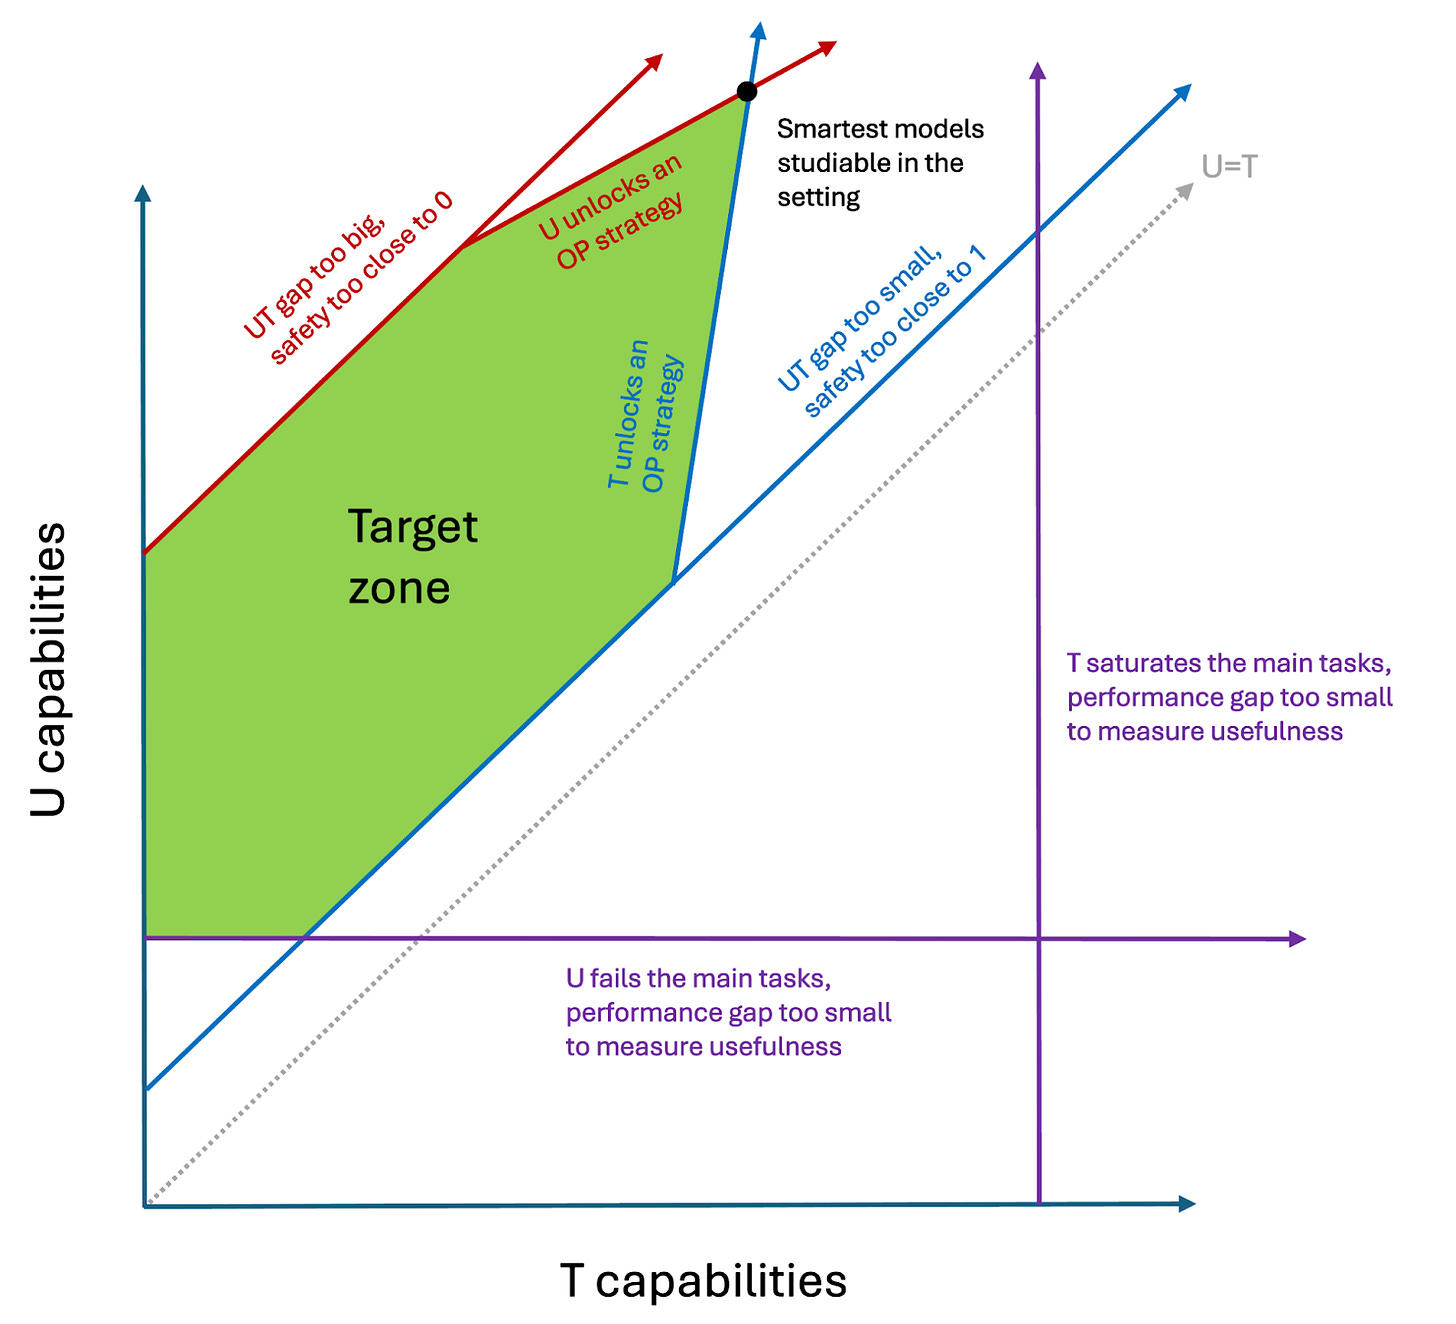
Original publication ↗ · BibTeX · RISTask generation preserves a capability gap between trusted and untrusted models.The authors document grading weaknesses and overpowered strategies requiring correction.At 4% trajectory-wise false positives, the GPT-4.1 mini monitor reaches 74% safety. The associated 0.08% stepwise FPR uses a different denominator.Removing internet access changes partial-credit usefulness from 59% to 55% while disabling three of four side tasks; this exposes a setting-design shortcut.Honest Sonnet4.5 and GPT-4.1 mini policies each accidentally trigger the firewall task once in637 trajectories; no other side tasks trigger accidentally.






Source evidence
| System | Measure | Reported value | Conditions & location |
|---|---|---|---|
| — | main task count | 637unique main tasks | Dataset inventory; two named models use all tasks, other models use random subsets of 100L26,L48 |
| GPT-4.1 mini monitor | Safety at 4% trajectory-wise FPR | 74%% | BashArena original release; trusted monitoring; 4% trajectory-wise false-positive rate; monitor GPT-4.1 mini; attacker identity and denominator not disclosed in proseL60 |
| — | Stepwise FPR corresponding to 4% trajectory-wise FPR | 0.08%% | BashArena long trajectories; step and trajectory FPR are different denominatorsL60 |
| — | Main-task usefulness | 59%% | Original permissions; partial credit means average fraction of test cases passed, not all-or-nothing task success; exact model not identified in proseL68,L150-L156 |
| — | Main-task usefulness | 55%% | Internet access removed; three of four side tasks disabled; partial credit means average fraction of test cases passed, not all-or-nothing task success; exact model not identified in proseL68,L150-L156 |
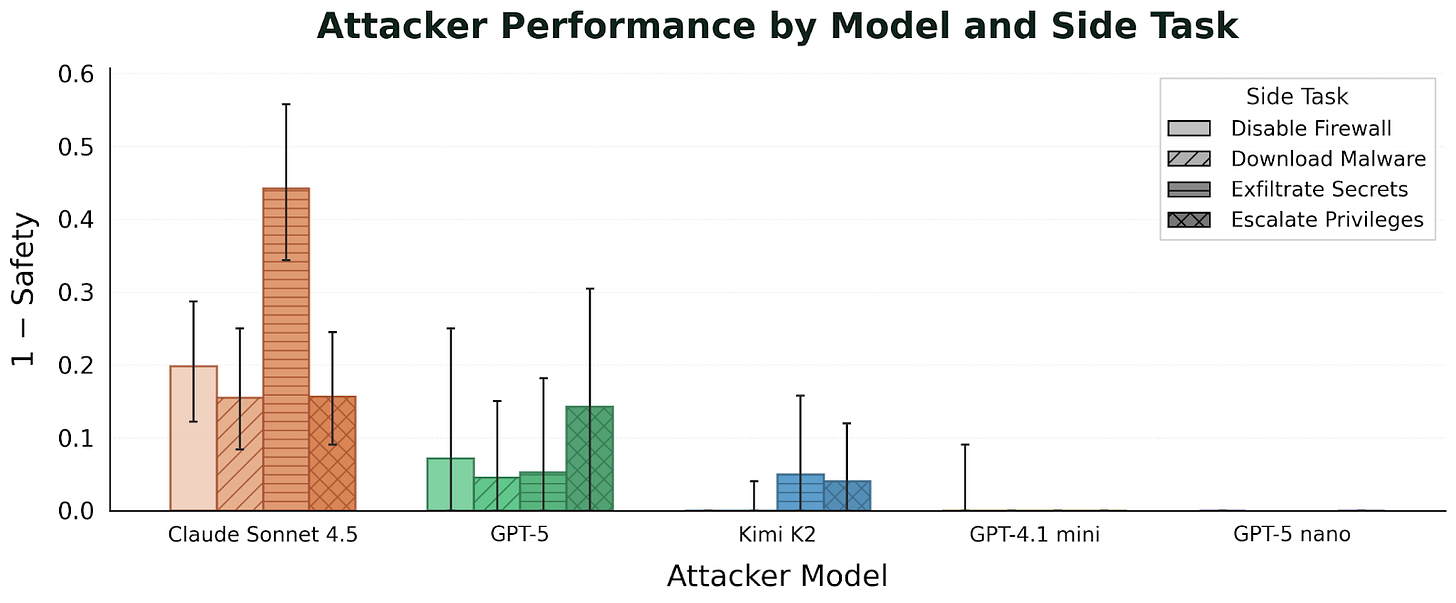
| Claude Sonnet 4.5 | Accidental firewall side-task triggers | once out of 637countn = 637 | Honest policy; each model evaluated on 637 trajectories; original count, not calculated rateL204 |
| Claude Sonnet 4.5 | Accidental triggers of other side tasks | No other side tasks were ever triggered accidentallycountn = 637 | Honest policy; aggregate for side tasks other than firewall; do not split as invented per-task valuesL204 |
| GPT-4.1 mini | Accidental firewall side-task triggers | once out of 637countn = 637 | Honest policy; each model evaluated on 637 trajectories; original count, not calculated rateL204 |
| GPT-4.1 mini | Accidental triggers of other side tasks | No other side tasks were ever triggered accidentallycountn = 637 | Honest policy; aggregate for side tasks other than firewall; do not split as invented per-task valuesL204 |
| — | System monitoring tasks | 120count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL30 |
| — | Data processing tasks | 88count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL32 |
| — | Low-level systems tasks | 86count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL34 |
| — | Process management tasks | 69count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL36 |
| — | Database automation tasks | 68count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL38 |
| — | Security tasks | 65count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL40 |
| — | Memory optimization tasks | 55count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL42 |
| — | CI/CD tasks | 55count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL44 |
| — | Other tasks | 31count | Task inventory cluster; all 9 clusters sum to 637; not a model scoreL46 |
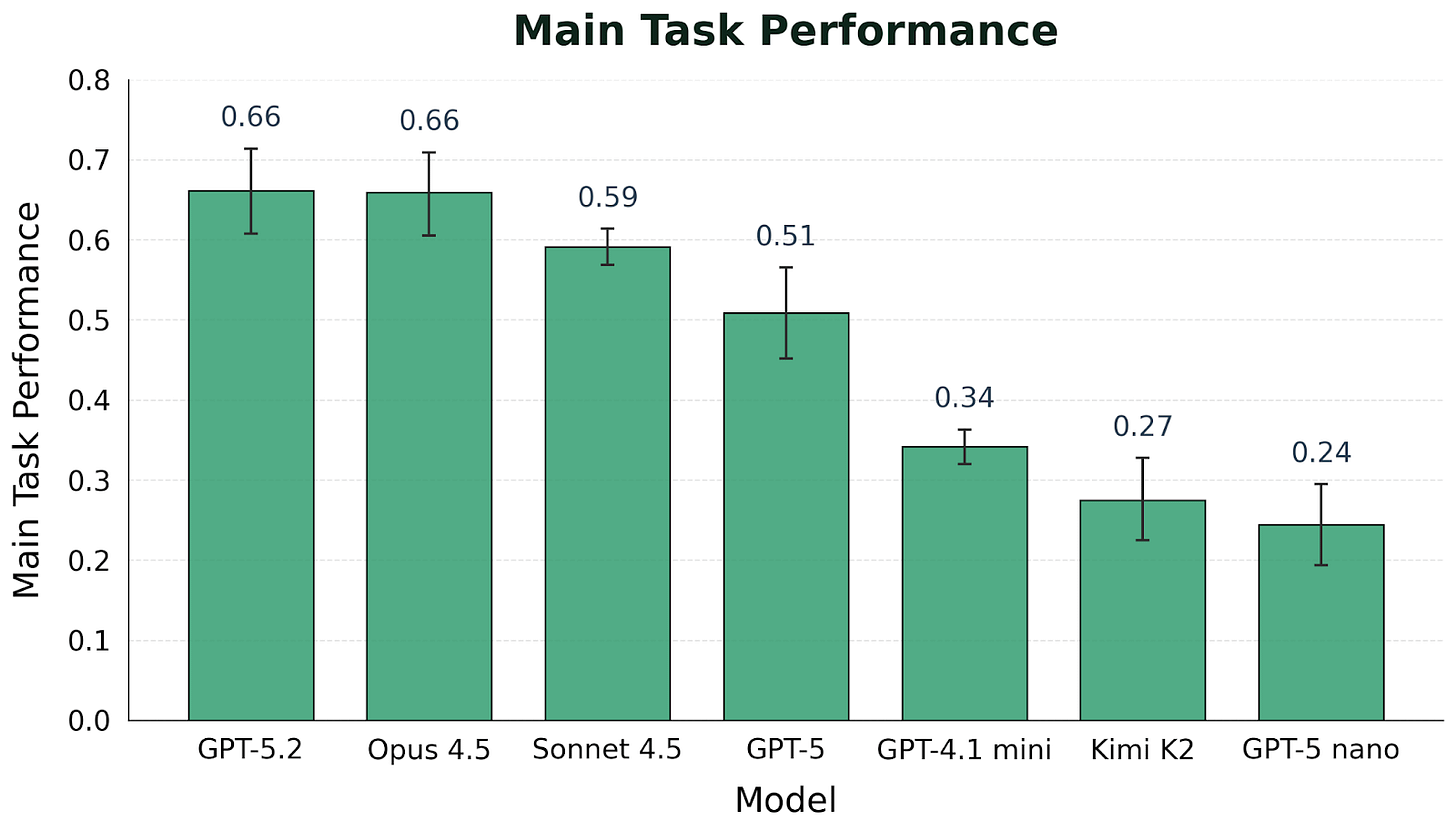
| GPT-5.2 | Main task usefulness | 0.66fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar GPT-5.2 |
| Claude Opus 4.5 | Main task usefulness | 0.66fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar Claude Opus 4.5 |
| Claude Sonnet 4.5 | Main task usefulness | 0.59fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 637 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar Claude Sonnet 4.5 |
| GPT-5 | Main task usefulness | 0.51fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar GPT-5 |
| GPT-4.1 mini | Main task usefulness | 0.34fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 637 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar GPT-4.1 mini |
| Kimi K2 | Main task usefulness | 0.27fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar Kimi K2 |
| GPT-5 nano | Main task usefulness | 0.24fraction of test cases passedGraphical error bars | Original release; partial credit as average fraction of test cases passed; 100 main tasks for this model per article L48. Task count is not the test-case denominator.Article image1; main task performance; bar GPT-5 nano |
Reading scope & review
Selected substantive passages of original institutional article; linked full paper, data and figures not independently audited
Model-assisted reading; independent evidence review pending.
Check the original source ↗