 NUWA
风险评测 · 评测基准
Task-Completion Time Horizons of Frontier AI Models
NUWA 研究解读 · 独立复核待完成
NUWA Research Note
研究问题研究设计与假设来源发现NUWA 解读局限与相反证据研究联系研究与决策意义证据补充机构与角色原始资源模型辅助整理 · 选读原始全文或官方文章中的相关章节;尚未完成逐章节审计。
研究速读
任务跨度把成功率与人类专家完成任务所需时间联系起来。它是特定任务分布上的拟合量,并非智能体连续自主运行的计时。
研究问题
以成功的人类基线用时衡量难度时,不同模型版本能够完成的软件任务范围如何变化?
研究设计与假设
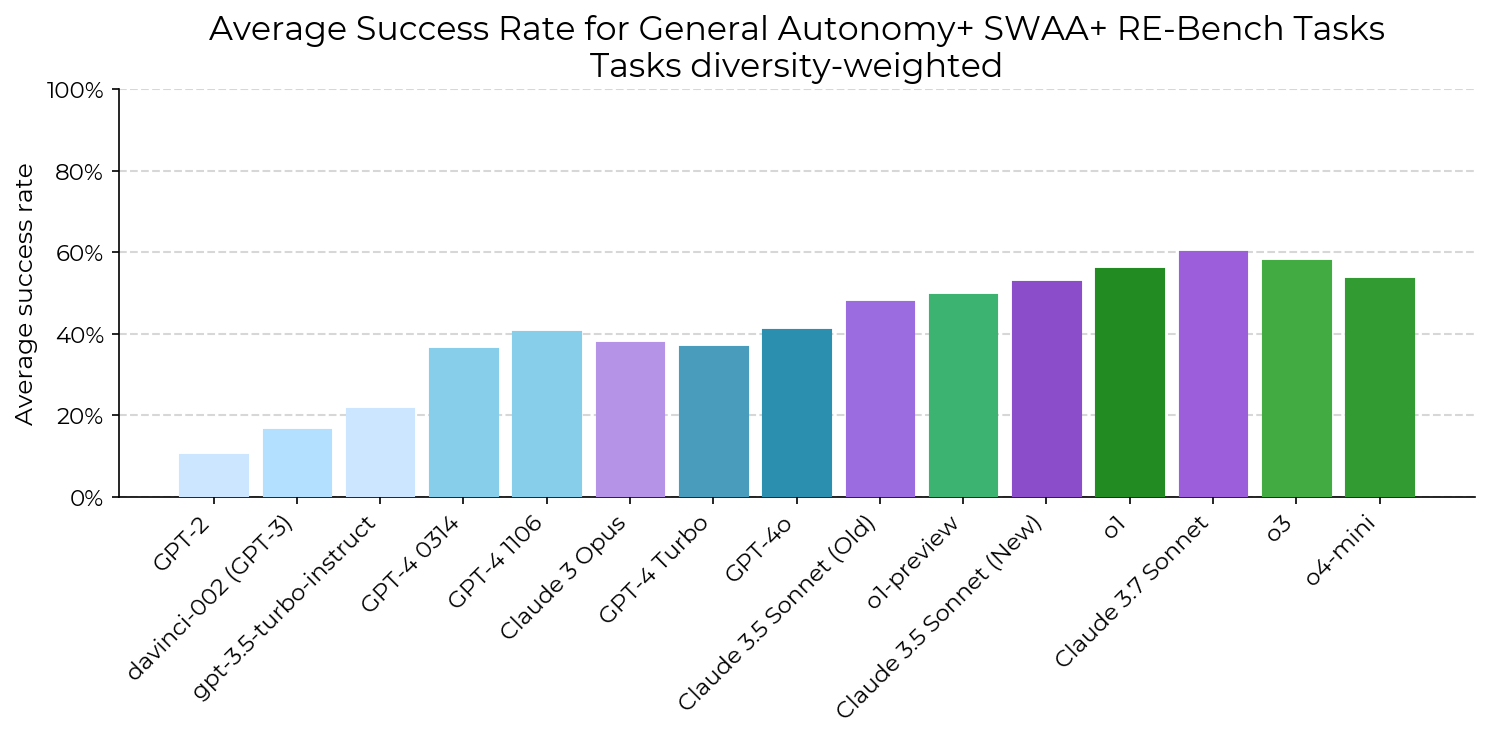
论文结合 HCAST 软件任务、RE-Bench 研究工程任务和软件原子操作。多数任务由人类基线确定用时,部分任务使用研究者估计。连续评分按任务阈值转为二元成功;逻辑回归把成功率与人类用时的对数关联,其中点定义 50% 任务跨度,并按任务族加权。
来源发现
论文观察到人类任务时长与智能体成功率的关系,以及所研究版本间任务跨度的上升(§§2.3–3)。
稳健性检查包含回溯预测、SWE-bench Verified、任务混杂程度和内部 PR;较混杂任务的绝对表现较低,人类背景知识也影响用时基线(§4)。
表 1 的 JSON 转换任务要求从输入输出示例推断规则;自动验收既使结果可测量,也体现了机器评分对任务开放性的约束。
NUWA 解读
较长跨度支持该软件任务分布中的能力提升,但不直接证明持续自主性、复制能力、抗拒干预或经济影响。论文外推依赖趋势延续与分布泛化的条件。
局限与相反证据
用时取决于专业经验和上下文;维护者与外部承包者的时长可能明显不同。自动评分、主要静态的环境缺少许多资源约束、交互和高代价错误。阈值、加权均是建模选择,原论文与后续 1.1 看板不能视为完全相同的任务集。
研究联系
RE-Bench 为该设计提供任务和人类基线(§2.1)。RepliBench 与关机抗拒测量其他条件和行为;与跨度建立联系需要同一系统的证据论证,不能平均分数。
研究与决策意义
模型建议:用跨度选择任务难度及可靠性目标,附上任务集版本与区间,并独立核查干预响应。
精确来源位置
- Measuring AI Ability to Complete Long Software Tasks · §2.1 Task suite / dataset; Table 1arXiv:2503.14499v4 (2026-10-25 capture)
- Measuring AI Ability to Complete Long Software Tasks · §2.2 BaseliningarXiv:2503.14499v4 (2026-10-25 capture)
- Measuring AI Ability to Complete Long Software Tasks · §3.1 Computing time horizon; Figure 4arXiv:2503.14499v4 (2026-10-25 capture)
- Measuring AI Ability to Complete Long Software Tasks · §4 External validity and robustnessarXiv:2503.14499v4 (2026-10-25 capture)
- Measuring AI Ability to Complete Long Software Tasks · §6 Discussion; Appendix B.2; Appendix E.3arXiv:2503.14499v4 (2026-10-25 capture)
来源核查、数据提取、编辑批准与实验复现分别记录。 方法说明 →
证据补充 · 2026-10-28
模型辅助整理 · 独立证据及双语编辑复核待完成。以下数值为来源发现或材料计数,与趋势结果序列分开保存。
解释跨度图时,应同时检查模型拟合版本、任务集是否接近饱和及人类时长测量。方法修订导致的估计变化不等于模型能力下降;跨度也不能直接换算成研发提速或连续自主运行时间。
关联阅读
NUWA 阅读关联;不据此声称原文引用、实验复现或成绩等价。
本次解释的来源
- Impact of modeling assumptions on time horizon results · Summary; model correction; uncertainty table; text lines 00043,00069,00240Original resource captured 2026-10-28T07:24:45.348612+00:00; sha256:9695043f6347be4a67091843e5b34b1db63f1ab11ee6a7956edcf1094182bd20
- Clarifying limitations of time horizon · Research note and limitations; text lines 00072Original resource captured 2026-10-28T07:24:45.640517+00:00; sha256:caec62e207534efe7e6fbcb55bb6a12459264f8591145eef7d9cac011c571860
机构与角色



作者 (26)
Thomas Kwa · Ben West · Joel Becker · Amy Deng · Katharyn Garcia · Max Hasin · Sami Jawhar · Megan Kinniment · Nate Rush · Sydney Von Arx · Ryan Bloom · Thomas Broadley · Haoxing Du · Brian Goodrich · Nikola Jurkovic · Luke Harold Miles · Seraphina Nix · Tao Lin · Chris Painter · Neev Parikh · David Rein · Lucas Jun Koba Sato · Hjalmar Wijk · Daniel M. Ziegler · Elizabeth Barnes · Lawrence Chan
评测协议
引用与复用
引用研究发现时请引用原始出版物;引用 NUWA 的整理与解释时,单独引用本站记录及对应快照。
原始出版物 · BibTeX
@misc{time-horizons,
  title = {Task-Completion Time Horizons of Frontier AI Models},
  url = {https://metr.org/time-horizons/},
  author = {Thomas Kwa and Ben West and Joel Becker and Amy Deng and Katharyn Garcia and Max Hasin and Sami Jawhar and Megan Kinniment and Nate Rush and Sydney Von Arx and Ryan Bloom and Thomas Broadley and Haoxing Du and Brian Goodrich and Nikola Jurkovic and Luke Harold Miles and Seraphina Nix and Tao Lin and Chris Painter and Neev Parikh and David Rein and Lucas Jun Koba Sato and Hjalmar Wijk and Daniel M. Ziegler and Elizabeth Barnes and Lawrence Chan},
  year = {2026},
  date = {2026-09-08},
  version = {Time Horizon 1.1; page updated 2026-09-08},
  note = {Time Horizon 1.1; page updated 2026-09-08}
}
NUWA 记录 · BibTeX
@misc{time-horizons-nuwa,
  title = {Task-Completion Time Horizons of Frontier AI Models — NUWA research record},
  url = {https://whitzard.tech/nuwa/whitzard-index/work/time-horizons/},
  version = {2026-10-29.1},
  organization = {NUWA Frontier AI Safety Lab},
  howpublished = {Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--time-horizons.json},
  note = {NUWA research note. Source-reading scope and independent review status are stated on the record. Snapshot 2026-10-29.1. Retained note edition: https://whitzard.tech/nuwa/whitzard-index/data/record-editions/2026-10-29.1--time-horizons.json.}
}
证据快照 2026-10-29.1 · 索引更新 · RSS
参考文献
- [1] Thomas Kwa, Ben West 等. Task-Completion Time Horizons of Frontier AI Models. 2026-09-08 ; Retained existing source-specific note sections; this pass audits duplicate/boilerplate structure and source availability, not complete section-level verification.
- [2] Thomas Kwa, Ben West 等. Measuring AI Ability to Complete Long Software Tasks ; Author affiliations on the original paper title page; §2.1 Task suite / dataset; Table 1; §2.2 Baselining