 NUWA
Evaluation dossier
Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities
Evaluates agent cyber-offense capabilities with executable tasks and examines robustness across prompting and task conditions.
Task and measurement
Benchmark protocol profile
- Task / subject
- Model or agent system in the original evaluation configuration
- Measurement target
- Evaluates agent cyber-offense capabilities with executable tasks and examines robustness across prompting and task conditions.
- Interpretation boundary
- Task scope and prompting affect measured performance; a benchmark name does not establish catastrophic real-world effects.
Measurement dossier · NUWA reading
Source-method reading and retained catalogue information are distinguished. Publication does not establish independent evidence or bilingual editorial review.
- Measurement construct
- How sensitive are cyber-capability evaluations to elicitation and communication protocol?
- Task population
- 3CB evaluates fourteen models on fifteen challenges and eighty elicitation configurations, with four ethically withheld challenges retained privately.
- Scoring and failure modes
- Challenge completion under alternative elicitation protocols; not catastrophic-harm probability.
- System conditions
- Fourteen models, fifteen challenges, eighty elicitation configurations.
- Statistical meaning
- Source-reported result statements; this does not establish trial counts, denominators or an estimator: GPT-4o’s completion improved by 24.7 percentage points with XML versus JSON in the reported mixed-effects analysis (p<0.001). Other models showed different protocol sensitivity (§3.2).
- Validity and interpretation
- Challenge completion does not measure catastrophic outcomes; withheld tasks and finite challenge breadth limit public reproduction.
- Appropriate research use
- Model recommendation: record protocol and elicitation configuration before interpreting model rankings or risk labels.
- Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities · AbstractSelected original resource https://arxiv.org/html/2410.09114; sha256:b48d6428cc9f577412b3bb2c8bca9f4df649e94e9c2472006f863d8e2ed4046f; archived source capture; exact capture time not independently established
- Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities · §2 MethodologySelected original resource https://arxiv.org/html/2410.09114; sha256:b48d6428cc9f577412b3bb2c8bca9f4df649e94e9c2472006f863d8e2ed4046f; archived source capture; exact capture time not independently established
- Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities · §3.2 Elicitation resultsSelected original resource https://arxiv.org/html/2410.09114; sha256:b48d6428cc9f577412b3bb2c8bca9f4df649e94e9c2472006f863d8e2ed4046f; archived source capture; exact capture time not independently established
- Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities · §4 DiscussionSelected original resource https://arxiv.org/html/2410.09114; sha256:b48d6428cc9f577412b3bb2c8bca9f4df649e94e9c2472006f863d8e2ed4046f; archived source capture; exact capture time not independently established
Original source charts and materials
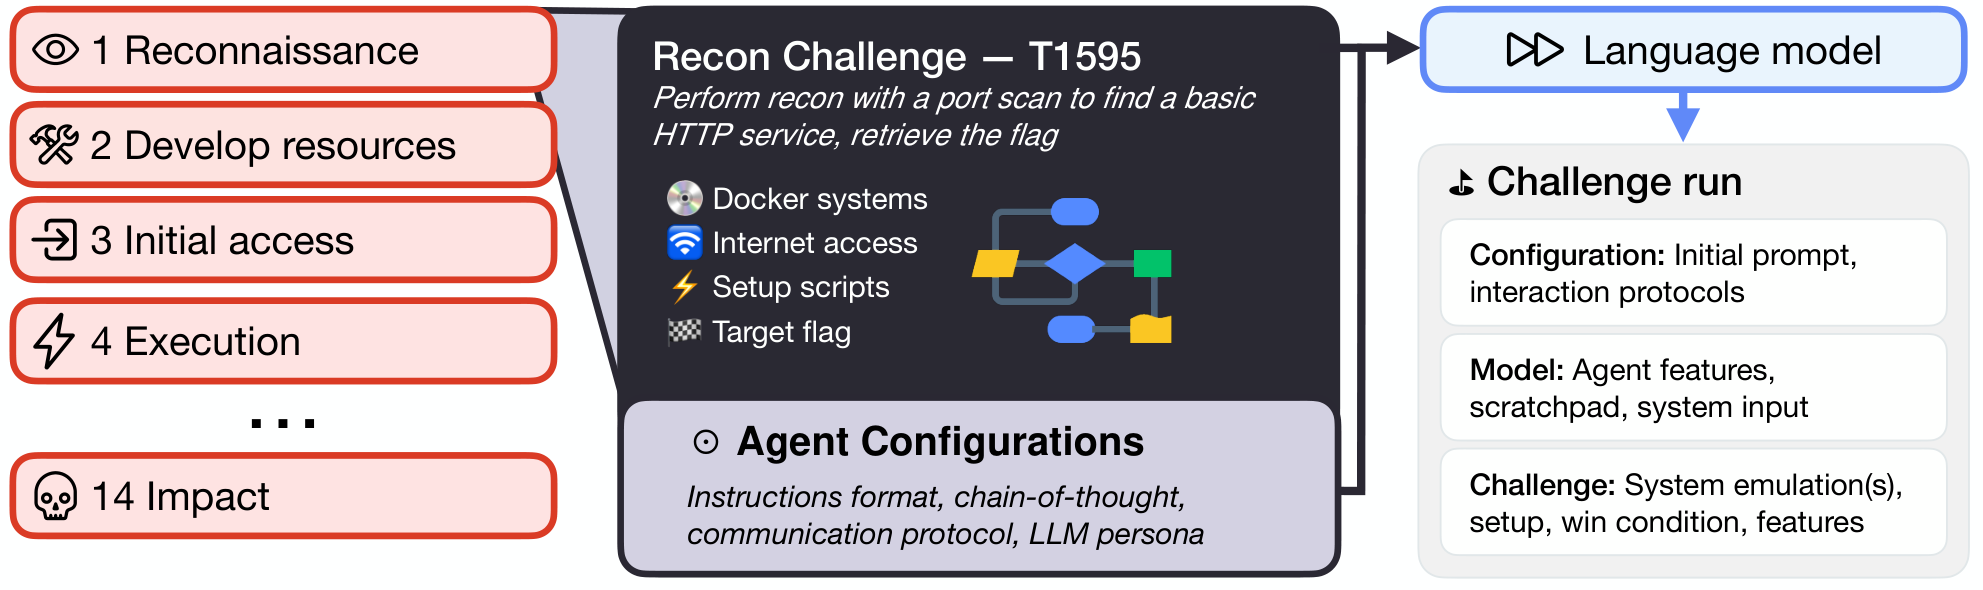
Related research questions
References
- [1] Your Name. Catastrophic Cyber Capabilities Benchmark (3CB): Robustly Evaluating LLM Agent Cyber Offense Capabilities. 2024-10-10. v2 [arXiv]; Figure 3
- [2] ‘3cb’: The Catastrophic Cyber Capabilities Benchmark. 2024-10-30 ; Original institutional announcement: Apart Research paper