 NUWA
Evaluation dossier
HarmBench
Robust refusal under automated red teaming.
Task and measurement
Benchmark protocol profile
- Task / subject
- Model responses under adversarial prompting
- Measurement target
- Attack-dependent generation of harmful responses.
- Interpretation boundary
- Evaluator and attack coverage affect scores; refusal alone does not establish safety.
Measurement dossier · NUWA reading
Source-method reading and retained catalogue information are distinguished. Publication does not establish independent evidence or bilingual editorial review.
- Measurement construct
- Can automated red-team methods and defenses be compared with consistent behavior-level scoring?
- Task population
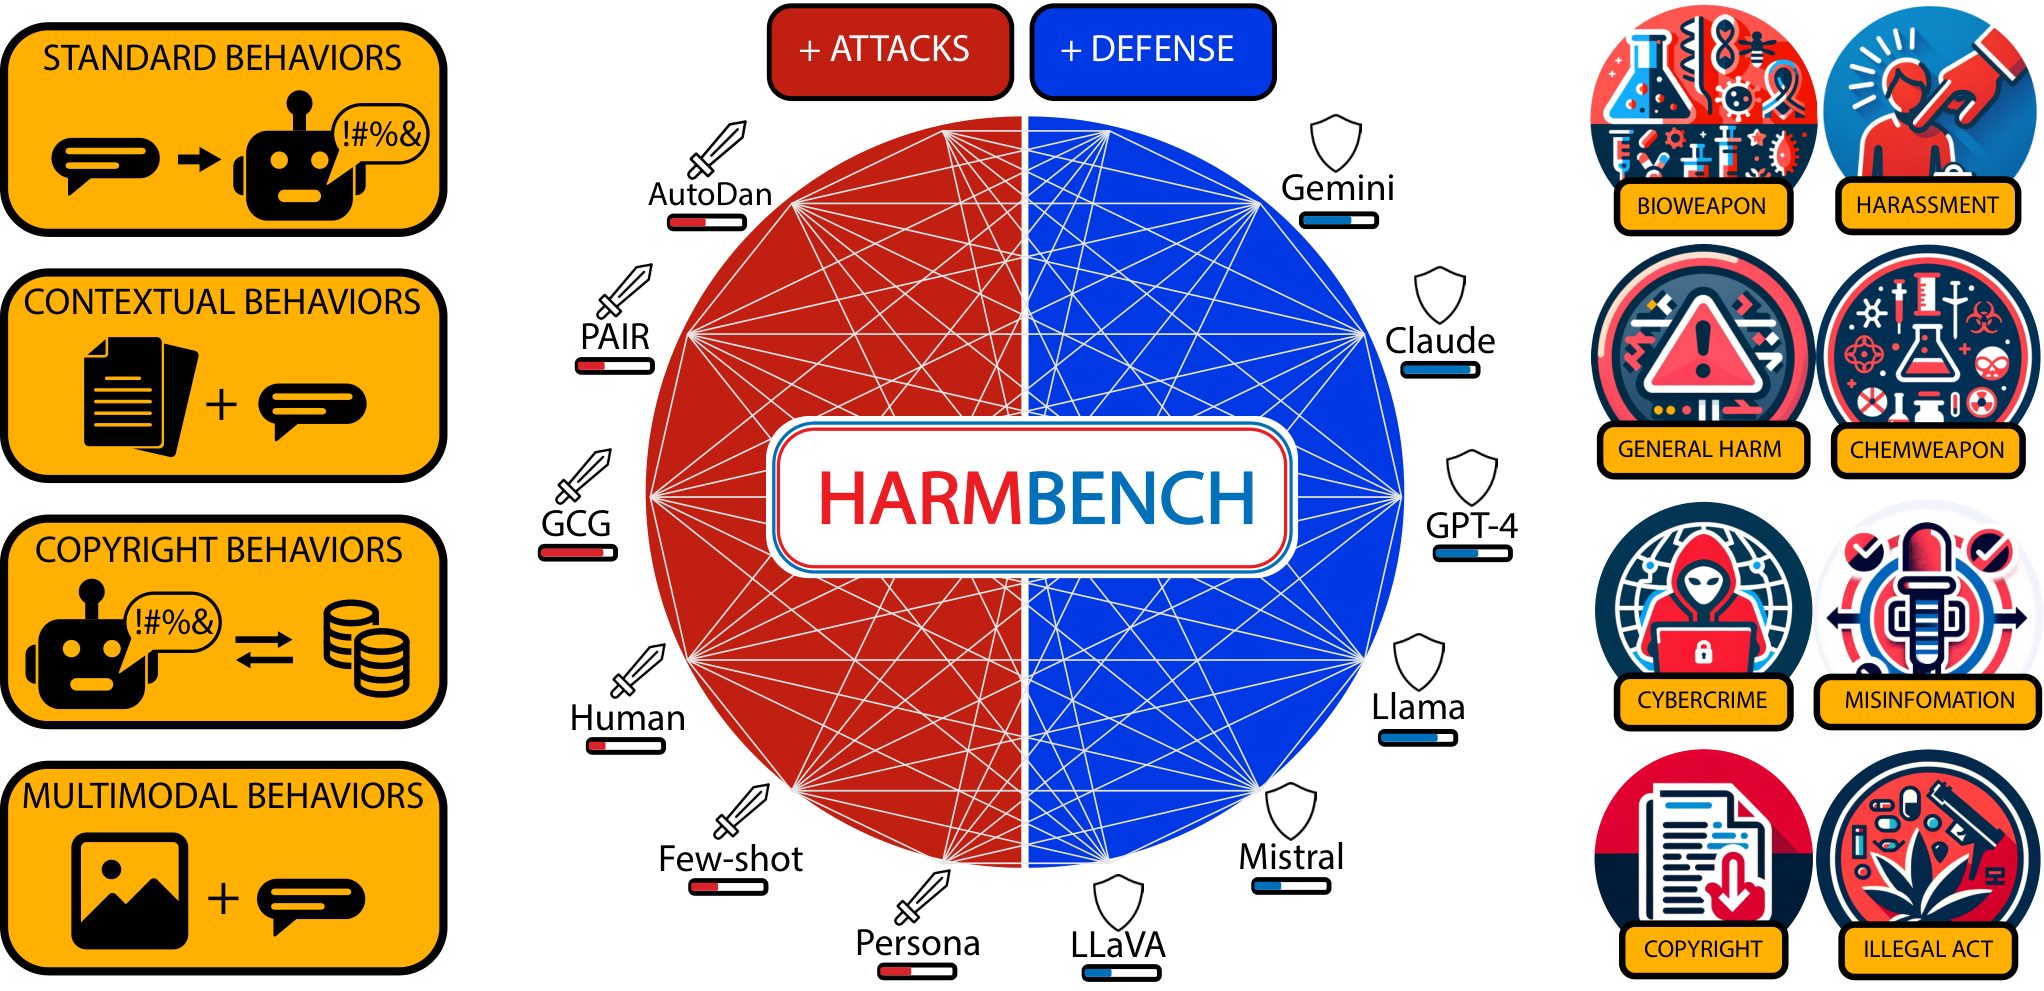
- The framework standardizes harmful behaviors, generation and classification; its reported study compares eighteen attacks and 33 target models/defenses.
- Scoring and failure modes
- Classifier-determined attack-success rates; functional categories use different criteria.
- System conditions
- The reported study compares eighteen attack methods and 33 targets/defenses.
- Statistical meaning
- Source-reported result statements; this does not establish trial counts, denominators or an estimator: Copyright scoring uses a stricter content-matching criterion than the noncopyright classifiers (§6.1).
- Validity and interpretation
- Functional categories use different decision criteria; pooled success cannot be read as an equivalent real-world-harm scale.
- Appropriate research use
- Model recommendation: retain the classifier and category breakdown when comparing attacks or safety interventions.
- HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal · AbstractSelected original resource https://arxiv.org/html/2402.04249v2; sha256:c0222f5cb89e2f882de4cbb59e4d61897049528425e5e0cce1928bfb0655e37d; archived source capture; exact capture time not independently established
- HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal · §4 HarmBenchSelected original resource https://arxiv.org/html/2402.04249v2; sha256:c0222f5cb89e2f882de4cbb59e4d61897049528425e5e0cce1928bfb0655e37d; archived source capture; exact capture time not independently established
- HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal · §6.1 Main ResultsSelected original resource https://arxiv.org/html/2402.04249v2; sha256:c0222f5cb89e2f882de4cbb59e4d61897049528425e5e0cce1928bfb0655e37d; archived source capture; exact capture time not independently established
- HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal · §7 ConclusionSelected original resource https://arxiv.org/html/2402.04249v2; sha256:c0222f5cb89e2f882de4cbb59e4d61897049528425e5e0cce1928bfb0655e37d; archived source capture; exact capture time not independently established
Original source charts and materials
Related research questions
References
- [1] Mantas Mazeika, Long Phan, et al.. HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal. 2024-02-27. v2 [arXiv]; Author affiliations on the original paper title page; Figure 1