 NUWA
Evaluation dossier
SEC-bench
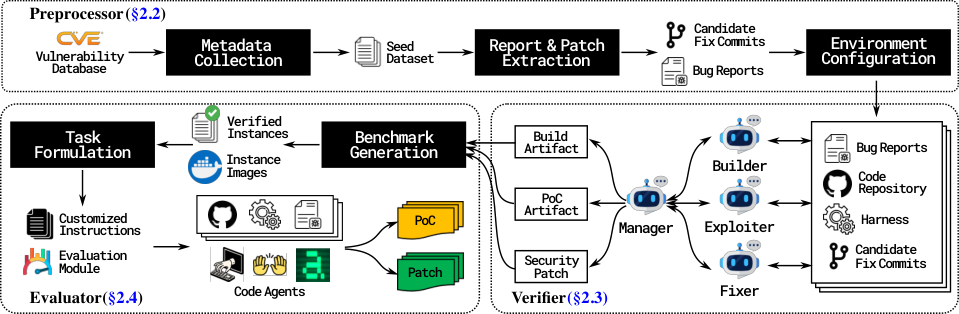
Tests vulnerability reproduction and patching in executable software environments assembled with an automated construction pipeline.
Task and measurement
Benchmark protocol profile
- Task / subject
- Model or agent system under the original task configuration
- Measurement target
- Tests vulnerability reproduction and patching in executable software environments assembled with an automated construction pipeline.
- Interpretation boundary
- Reproduction and patching are different outcomes; executable verification and task construction quality constrain interpretation.
Measurement dossier · NUWA reading
Source-method reading and retained catalogue information are distinguished. Publication does not establish independent evidence or bilingual editorial review.
- Measurement construct
- Can security-agent datasets be built with reproducible vulnerability and patch checks?
- Task population
- An automated pipeline reconstructs C/C++ projects, verifies memory-safety defects and evaluates PoC generation and patching with multiple coding scaffolds.
- Scoring and failure modes
- Sanitizer-validated PoC generation success versus vulnerability-patching success.
- System conditions
- C/C++ projects, supported memory-safety defects and differing task information.
- Statistical meaning
- Source-reported result statements; this does not establish trial counts, denominators or an estimator: The reported best success rates were 18.0% for PoC generation and 34.0% for patching on the complete dataset.
- Validity and interpretation
- Sanitizer-detectable memory-safety defects and C/C++ coverage exclude many web, kernel and distributed-system failure classes (§5).
- Appropriate research use
- Model recommendation: retain task type and provided location information; do not equate sanitizer reproduction with exploit impact.
- SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks · AbstractSelected original resource https://arxiv.org/html/2506.11791; sha256:857cf5e1b82d84f586aabf5eabc8626b00d66bd6ff321c8e170bee6eba519ca6; archived source capture; exact capture time not independently established
- SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks · §3.1 Experimental SetupSelected original resource https://arxiv.org/html/2506.11791; sha256:857cf5e1b82d84f586aabf5eabc8626b00d66bd6ff321c8e170bee6eba519ca6; archived source capture; exact capture time not independently established
- SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks · §3.2 Performance of LLM Agents in Security TasksSelected original resource https://arxiv.org/html/2506.11791; sha256:857cf5e1b82d84f586aabf5eabc8626b00d66bd6ff321c8e170bee6eba519ca6; archived source capture; exact capture time not independently established
- SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks · §5 Limitations and Future WorkSelected original resource https://arxiv.org/html/2506.11791; sha256:857cf5e1b82d84f586aabf5eabc8626b00d66bd6ff321c8e170bee6eba519ca6; archived source capture; exact capture time not independently established
Original source charts and materials
Related research questions
References
- [1] Hwiwon Lee Ziqi Zhang Hanxiao Lu † Lingming Zhang. SEC-bench: Automated Benchmarking of LLM Agents on Real-World Software Security Tasks. 2025-06-13. v2 [arXiv]; Author affiliations on the original paper title page; Figure 1